Uploaded March 2025 | Updated September 2026, 2 weeks ago
I made this #FluidX3D #CFD simulation run on a frankenstein zoo of 🟥AMD + 🟩Nvidia + 🟦Intel #GPU​s! 🖖🤪
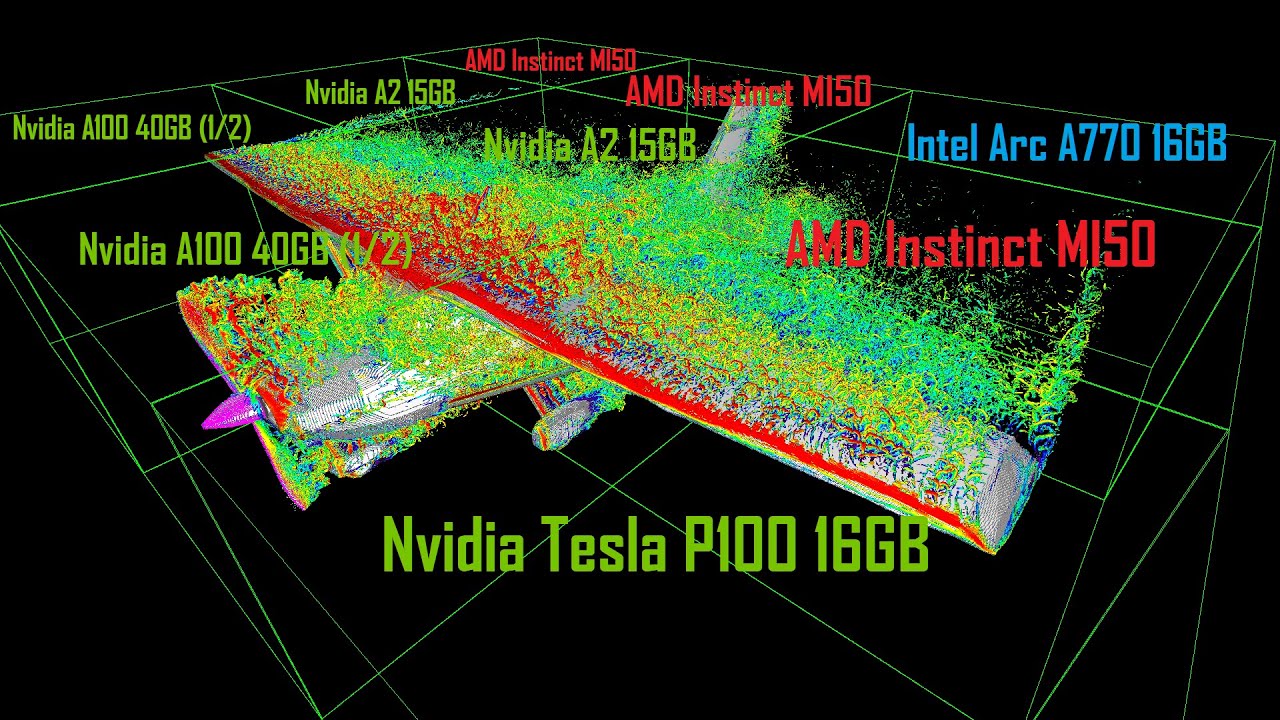
This RGB SLI abomination setup consists of 8 GPUs from 3 vendors in one server:
- 1x Nvidia A100 40GB (2 domains)
- 1x Nvidia Tesla P100 16GB (1 domain)
- 2x Nvidia A2 15GB (1 domain each)
- 3x AMD Instinct MI50 (1 domain each)
- 1x Intel Arc A770 16GB (1 domain)
I split the simulation box with 2322×1857×581 = 2.5 Billion grid cells (132GB VRAM requirement) up into 9 equal domains of ~15GB each, which run on 8 GPUs. The A100 is fast enough to take 2 domains while the other GPUs each get 1 domain. This is 5 completely different GPU microarchitectures seamlessly communicating over PCIe 4.0 x128. Under #OpenCL they are all created equal and don't care what vendor the GPU is which computes the neighbor domain.
This demonstrates that heterogenious #GPGPU compute is actually very practical. FluidX3D users can run the hardware they already have, and freely expand with any other hardware that is best value at the time, rather than being vendor-locked and having to buy more expensive GPUs that bring less value.
The demo setup itself is the Cessna-172 in flight fir 1 second real time, at 226 km/h airspeed. 159022 time steps, 11h27min runtime consisting of 9h16min (compute) + 2h11min (rendering).
Setup: github.com/ProjectPhysX/FluidX3D/blob/master/src/setup.cpp#L771
Cessna-172 3D model: thingiverse.com/thing:814319/files
I created the FluidX3D CFD software from scratch and put the entire source code on #GitHub, for anyone to use for free. Have fun!
github.com/ProjectPhysX/FluidX3D
Huge thanks to Tobias Ribizel from TUM Campus Heilbronn for providing the hardware for this test!
I made this #FluidX3D #CFD simulation run on a frankenstein zoo of 🟥AMD + 🟩Nvidia + 🟦Intel #GPU​s! 🖖🤪
This RGB SLI abomination setup consists of 8 GPUs from 3 vendors in one server:
- 1x Nvidia A100 40GB (2 domains)
- 1x Nvidia Tesla P100 16GB (1 domain)
- 2x Nvidia A2 15GB (1 domain each)
- 3x AMD Instinct MI50 (1 domain each)
- 1x Intel Arc A770 16GB (1 domain)
I split the simulation box with 2322×1857×581 = 2.5 Billion grid cells (132GB VRAM requirement) up into 9 equal domains of ~15GB each, which run on 8 GPUs. The A100 is fast enough to take 2 domains while the other GPUs each get 1 domain. This is 5 completely different GPU microarchitectures seamlessly communicating over PCIe 4.0 x128. Under #OpenCL they are all created equal and don't care what vendor the GPU is which computes the neighbor domain.
This demonstrates that heterogenious #GPGPU compute is actually very practical. FluidX3D users can run the hardware they already have, and freely expand with any other hardware that is best value at the time, rather than being vendor-locked and having to buy more expensive GPUs that bring less value.
The demo setup itself is the Cessna-172 in flight fir 1 second real time, at 226 km/h airspeed. 159022 time steps, 11h27min runtime consisting of 9h16min (compute) + 2h11min (rendering).
Setup: github.com/ProjectPhysX/FluidX3D/blob/master/src/setup.cpp#L771
Cessna-172 3D model: thingiverse.com/thing:814319/files
I created the FluidX3D CFD software from scratch and put the entire source code on #GitHub, for anyone to use for free. Have fun!
github.com/ProjectPhysX/FluidX3D
Huge thanks to Tobias Ribizel from TUM Campus Heilbronn for providing the hardware for this test!
![Line3D [GRAPHICS ENGINE] Dynamische Beleuchtung
Ich hab noch ein bisschen an der Java-Grafikausgabe aus meinem Projekt PhysX3D weiter geschrieben. Aus einfachen Linien sind Polygone geworden, die dynamisch von einer (oder auch mehreren) frei beweglichen Lichtquellen beleuchtet werden. In diesem Beispiel berechnet die CPU auf einem Kern 25.600 Dreiecke pro Frame, und das etwa 30 Mal in der Sekunde.
Ich verwende dazu nur die elementarsten Java-Bibliotheken wie das JFrame, ein Fenster, in dem ich Linien, Text und Vielecke zeichnen kann.
Wie funktioniert die Berechnung?
Für jedes Dreieck wird der Normalenvektor berechnet. Das ist sozusagen eine Linie, die immer senkrecht auf der Fläche des Dreiecks steht. Dann wird der Normalenvektor skalar mit dem Vektor vom Mittelpunkt des Dreiecks zur Lichtquelle multipliziert. Einfach ausgedrückt vergleicht man dabei, ob der Normalenvektor zur Lichtquelle zeigt. Wenn er das tut, ist die Fläche heller, sonst dunkler. Mit dem Ergebnis der skalaren Multiplikation wird die Helligkeit des Dreiecks skaliert.
Die Lichtquelle muss nicht immer am selben Punkt sein, sie kann sich auch bewegen, wie hier im Video demonstriert.
Was ist der praktische Nutzen davon?
Das Prinzip der dynamischen Beleuchtung ist heutzutage in jedem Computerspiel und in jeder Rendering-Software zu finden, bloß werden dort die Dreiecke noch viel kleiner gemacht, damit zum Beispiel ein animiertes Gesicht nicht eckig aussieht. Line3D [GRAPHICS ENGINE] Dynamische Beleuchtung](https://i.ytimg.com/vi/_9i8RSxTkjA/mqdefault.jpg)


![FluidX3D [FLUID SIMULATION] - Real Time Free Surface LBM with Volume-of-Fluid
FluidX3D is a real time 3D fluid simulation based on the lattice Boltzmann method. It is written in OpenCL C (GPU code) and optimized to the physical limit (video memory bandwith, ~520GB/s).
All demonstrations in the video are simulated and visualized in real time on a Nvidia Titan Xp. Graphics are done with the OpenCL C version of Line3D, the fastest graphics engine ever written for primitive shapes like lines, dots and circles. It can handle up to 2 billion lines per second.
The free surface is done with the volume-of-fluid (VoF) extension to LBM. It allows simulating free surfaces with a sharp interface layer. Having to avoid race conditions makes an efficient GPU implementation of VoF is quite challenging. Currently there is no surface tension yet; the curvature estimation algorithm is still under construction.
The volume force (gavity) is implemented with the Gou forcing scheme.
Hardware Setup:
CPU: Intel Core i7-8700K @ 4,5GHz all core
GPU: Nvidia Titan Xp
RAM: 2x8GB Corsair Vengeance LPX DDR4 3200MHz CL16
Mainboard: ASUS ROG STRIX Z370-I GAMING
SSD 1: Samsung 970 PRO 512GB
SSD 2: Samsung 860 EVO 1TB
CPU Cooler: Cooltek LP53
PSU: Corsair SF600
Housing: Fractal Design Node 202
Timestamps:
0:00 - Intro
0:02 - honey coiling
0:34 - large drop impact
0:45 - drop splashing in flowing water
0:55 - throwing drop sideways in resting water
1:00 - eternal periodic water tap
1:07 - dam break without obstacles
1:18 - asymmetric dam break with two connected chambers
1:29 - droplet impact
1:39 - eternal periodic fountain
1:50 - dam break with cuboid obstacle
2:06 - more honey coiling (just because it is so cool)
More information at http://www.projectphysx.de
Music: Notaker - Fatal System Error FluidX3D [FLUID SIMULATION] - Real Time Free Surface LBM with Volume-of-Fluid](https://i.ytimg.com/vi/a1u2g9ahIDk/mqdefault.jpg)
![FluidX3D [FLUID SIMULATION] - Smashing the Memory Wall with FP16 | 100 Subscriber Special
FluidX3D is a real time 3D fluid simulation based on the lattice Boltzmann method. It is written in OpenCL C (GPU code) and optimized to the physical limit (video memory bandwith, ~520GB/s).
All demonstrations in the video are simulated and visualized in real time on a Nvidia Titan Xp. Graphics are done with the OpenCL C version of Line3D, the fastest graphics engine ever written for primitive shapes like lines, dots and circles. It can handle up to 2 billion lines per second.
LBM performance is only limited by video memory bandwidth - the so-called memory wall. Storing the LBM distribution functions in memory as FP16 instead of FP32 cuts the memory bandwidth requirements in half, doubling the simulation speed at the cost of a bit of accuracy. My implementation has a hardware efficiency of up to 95%, meaning that 520 GB/s of the total 548 GB/s of video memory bandwidth are used. This results in a peak performance of 5.2 GLUPs (giga lattice updates per second, how many LBM lattice points are processed in 1 second) for the D3Q19 velocity set.
More information at http://www.projectphysx.de
Music: Notaker - Fatal System Error FluidX3D [FLUID SIMULATION] - Smashing the Memory Wall with FP16 | 100 Subscriber Special](https://i.ytimg.com/vi/aWFi__zMUkk/mqdefault.jpg)