Uploaded August 2026 | Updated September 2026, 3 weeks ago
Running Quen 3.827B on 12GB VRAM causes significant speed bottlenecks due to system RAM offloading. Learn if your hardware is actually bottlenecking your local LLM performance.
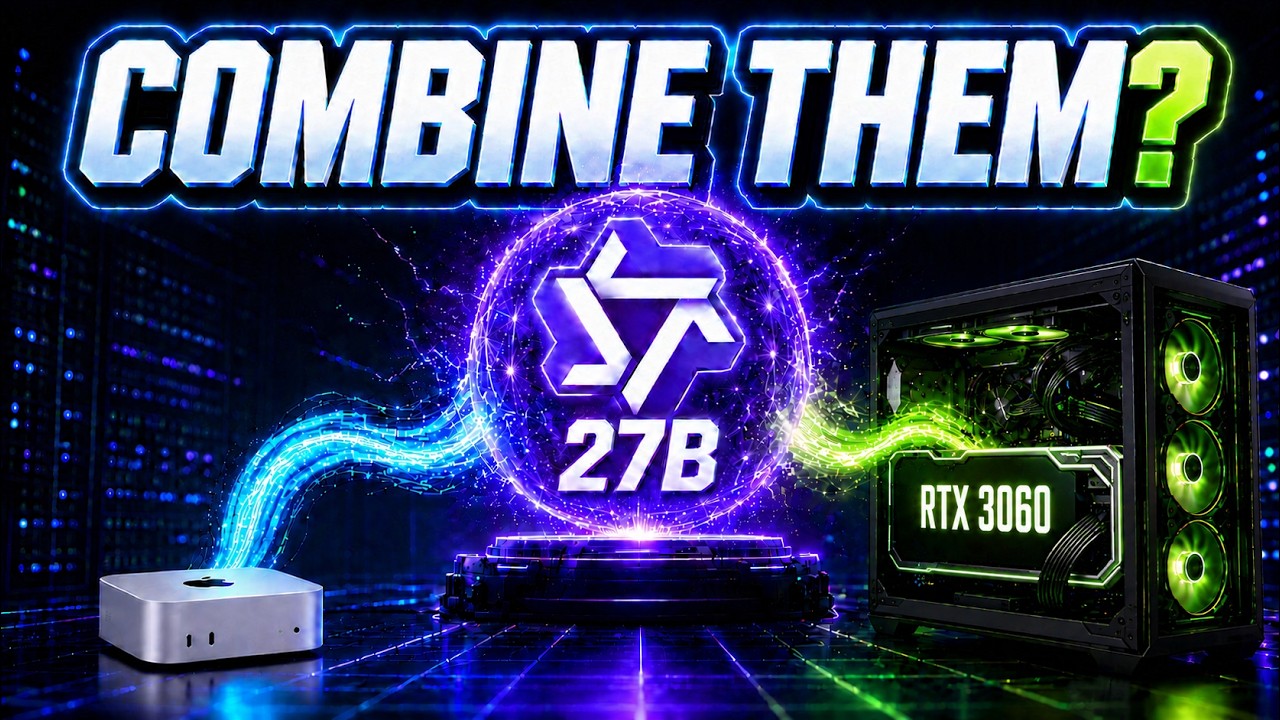
This performance review breaks down why the Quen 3.827B model struggles on standard 12GB VRAM setups. We examine the exact point where memory constraints force the model to offload data, causing inference speeds to plummet. If you are tired of slow local inference, this technical assessment clarifies why VRAM capacity is the primary limiting factor for this specific architecture.
We also compare single-card limitations against multi-GPU configurations to see if adding hardware is the right fix for your specific use case. You will get a clear understanding of the trade-offs between memory offloading and dedicated GPU memory management, helping you decide if an upgrade is necessary for your workflow.
Subscribe for weekly local LLM hardware breakdowns and comment below if you want us to test this model on different hardware configurations next.
⚠️ TL;DR is pinned in the comments if you just want the result.
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
⏱️ CHAPTERS
0:00 Hook
0:59 The model that doesn't fit
2:24 The two multi-GPU configurations
3:43 Smoke test
5:28 The bigger model
9:22 Crank it up a notch
11:50 It isn't just speed, it's room
12:53 Will this work on your machines?
14:17 Compared with a real multi-GPU box
16:04 What it actually costs
17:52 The verdict
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
🔧 THE SETUP — two commands
Build llama.cpp on both machines with RPC enabled:
cmake -B build -DGGML_RPC=ON
cmake --build build --config Release
On the machine you're borrowing:
ggml-rpc-server -H 0.0.0.0 -p 50052 -c -d MTL0
⚠️ `-d` pins ONE device. Without it, rpc-server advertises every backend it finds — on the Mac that
includes Apple's BLAS, and the scheduler crashes. Use `-d MTL0` on a Mac, `-d CUDA0` on Nvidia.
`-c` caches weights locally so later starts skip the transfer.
On your main machine:
llama-server -m model.gguf --rpc 192.168.1.x:50052 -ngl 99
My tuned invocation for Qwen3.8-27B at 128k:
-dev RPC0,CUDA0 -ts 6,4 -c 131072 --flash-attn 1 -ub 512
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
📊 THE NUMBERS
Qwen3.8 27b Q4_K_M · 15.92 GiB · 65 layers
6.79 t/s 3060 alone, layers offloaded to RAM
13.69 t/s 3060 + Mac over RPC, before tuning
13.98 t/s Mac alone — the cluster was doing nothing
16.39 t/s after fixing device order
22 t/s with MTP, empty context
~19.5 t/s with MTP, once context grows
⚠️ 22 t/s is a live llama-server run. On a llama-bench sweep at the same config
(131072 · f16 · -ts 6,4 · -ub 512) the figure is 20.05 — a bench and a serve run measure
different things.
Measured on llama.cpp master 84e908c62 (2026-08-12). ⛔ Not "latest master" — RPC and MTP
behaviour moves between builds, and today's HEAD may not reproduce these numbers.
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
⚠️ SECURITY — read this bit
rpc-server has NO AUTHENTICATION. Anyone who can reach the port can use it.
· Never expose it to the internet
· Firewall the port to specific machines
· Don't run it as root
· A VPN helps, but it is not an allow-list
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
🧰 THE FOUR TRAPS
1. Pin each worker with `-d`, or the Mac advertises BLAS as a device and crashes
2. Build separately per Linux version, or use matching containers
3. Keep the llama.cpp build identical at both ends — a mismatch looks like a network failure
4. macOS gives the GPU only ~75% of unified memory by default
Raise it: `sudo sysctl iogpu.wired_limit_mb=20480`
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
🖥️ HARDWARE
· RTX 3060 · 12 GB VRAM · 61 GB system RAM · Linux
· Apple Silicon Mac · 24 GB unified (~18 GB reaches the GPU)
· Wired gigabit, 1.19 ms RTT
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
🔗 LINKS
llama.cpp — github.com/ggml-org/llama.cpp
RPC backend docs — github.com/ggml-org/llama.cpp/tree/master/tools/rpc
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
Got machines sitting there doing nothing? Tell me what's in them.
#localai #llamacpp #llm #selfhostedai #qwen3 #homelab
Running Quen 3.827B on 12GB VRAM causes significant speed bottlenecks due to system RAM offloading. Learn if your hardware is actually bottlenecking your local LLM performance.
This performance review breaks down why the Quen 3.827B model struggles on standard 12GB VRAM setups. We examine the exact point where memory constraints force the model to offload data, causing inference speeds to plummet. If you are tired of slow local inference, this technical assessment clarifies why VRAM capacity is the primary limiting factor for this specific architecture.
We also compare single-card limitations against multi-GPU configurations to see if adding hardware is the right fix for your specific use case. You will get a clear understanding of the trade-offs between memory offloading and dedicated GPU memory management, helping you decide if an upgrade is necessary for your workflow.
Subscribe for weekly local LLM hardware breakdowns and comment below if you want us to test this model on different hardware configurations next.
⚠️ TL;DR is pinned in the comments if you just want the result.
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
⏱️ CHAPTERS
0:00 Hook
0:59 The model that doesn't fit
2:24 The two multi-GPU configurations
3:43 Smoke test
5:28 The bigger model
9:22 Crank it up a notch
11:50 It isn't just speed, it's room
12:53 Will this work on your machines?
14:17 Compared with a real multi-GPU box
16:04 What it actually costs
17:52 The verdict
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
🔧 THE SETUP — two commands
Build llama.cpp on both machines with RPC enabled:
cmake -B build -DGGML_RPC=ON
cmake --build build --config Release
On the machine you're borrowing:
ggml-rpc-server -H 0.0.0.0 -p 50052 -c -d MTL0
⚠️ `-d` pins ONE device. Without it, rpc-server advertises every backend it finds — on the Mac that
includes Apple's BLAS, and the scheduler crashes. Use `-d MTL0` on a Mac, `-d CUDA0` on Nvidia.
`-c` caches weights locally so later starts skip the transfer.
On your main machine:
llama-server -m model.gguf --rpc 192.168.1.x:50052 -ngl 99
My tuned invocation for Qwen3.8-27B at 128k:
-dev RPC0,CUDA0 -ts 6,4 -c 131072 --flash-attn 1 -ub 512
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
📊 THE NUMBERS
Qwen3.8 27b Q4_K_M · 15.92 GiB · 65 layers
6.79 t/s 3060 alone, layers offloaded to RAM
13.69 t/s 3060 + Mac over RPC, before tuning
13.98 t/s Mac alone — the cluster was doing nothing
16.39 t/s after fixing device order
22 t/s with MTP, empty context
~19.5 t/s with MTP, once context grows
⚠️ 22 t/s is a live llama-server run. On a llama-bench sweep at the same config
(131072 · f16 · -ts 6,4 · -ub 512) the figure is 20.05 — a bench and a serve run measure
different things.
Measured on llama.cpp master 84e908c62 (2026-08-12). ⛔ Not "latest master" — RPC and MTP
behaviour moves between builds, and today's HEAD may not reproduce these numbers.
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
⚠️ SECURITY — read this bit
rpc-server has NO AUTHENTICATION. Anyone who can reach the port can use it.
· Never expose it to the internet
· Firewall the port to specific machines
· Don't run it as root
· A VPN helps, but it is not an allow-list
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
🧰 THE FOUR TRAPS
1. Pin each worker with `-d`, or the Mac advertises BLAS as a device and crashes
2. Build separately per Linux version, or use matching containers
3. Keep the llama.cpp build identical at both ends — a mismatch looks like a network failure
4. macOS gives the GPU only ~75% of unified memory by default
Raise it: `sudo sysctl iogpu.wired_limit_mb=20480`
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
🖥️ HARDWARE
· RTX 3060 · 12 GB VRAM · 61 GB system RAM · Linux
· Apple Silicon Mac · 24 GB unified (~18 GB reaches the GPU)
· Wired gigabit, 1.19 ms RTT
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
🔗 LINKS
llama.cpp — github.com/ggml-org/llama.cpp
RPC backend docs — github.com/ggml-org/llama.cpp/tree/master/tools/rpc
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
Got machines sitting there doing nothing? Tell me what's in them.
#localai #llamacpp #llm #selfhostedai #qwen3 #homelab