Uploaded August 2026 | Updated September 2026, 3 weeks ago
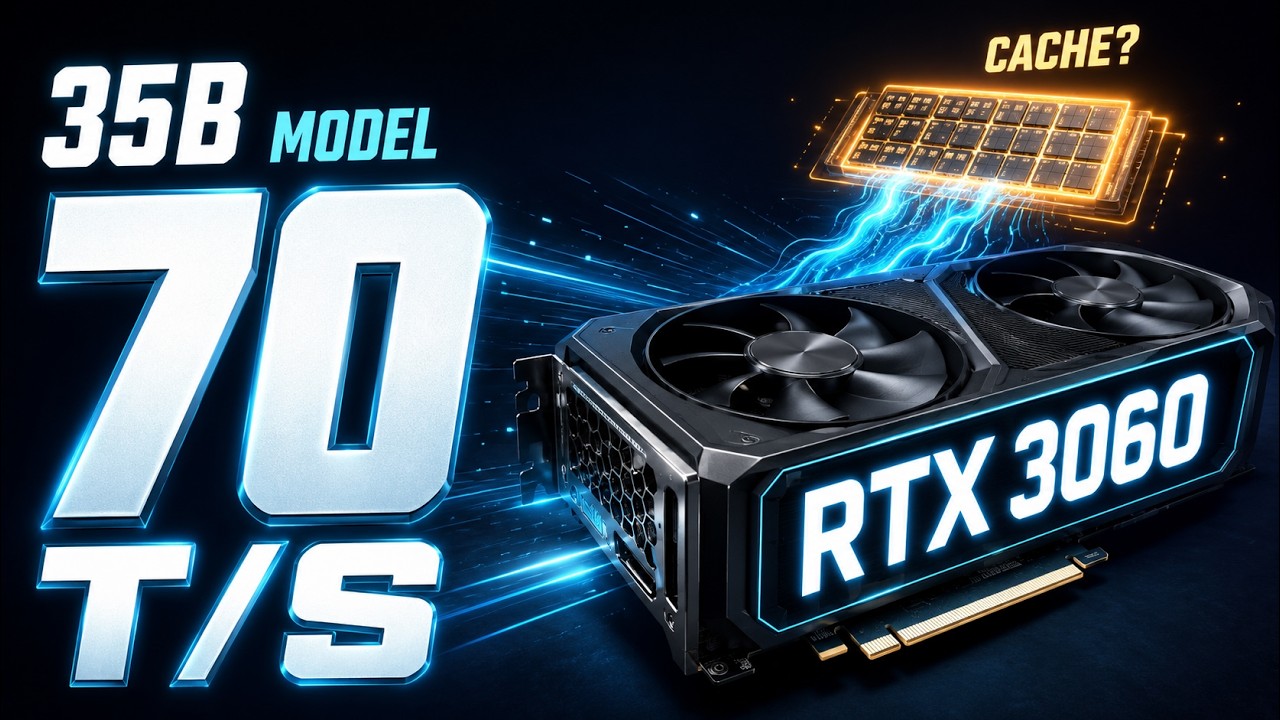
I built an expert cache for MoE models, keep the hottest experts parked in VRAM, stream the rest from system RAM.
The baseline was 42. This is what it took to find out why, and where it ended up: 80 tokens a second at peak, and still over 70 with real context in the window.
One RTX 3060. A 35B model. The part I did not expect: the cache is worth almost nothing on its own. What makes it worth something is what it does to speculative decoding underneath it.
⚙️ THE TWO FLAGS
Everything else here is the command you already run. These two are new:
--moe-cache-profile [path.csv]
--moe-cache-slots [n]
Full commands, both steps, in the pinned comment.
⏱️ CHAPTERS
0:00 Intro
0:31 The graveyard
2:35 The data says don't
5:47 The build, and the gut punch
7:42 The scheduler betrayal
10:54 Turning it up
14:08 Why it works
17:58 Your GPU
📊 THE NUMBERS
baseline, no cache ............ 42 tok/s
cache "working" ............... 6 tok/s ← the two days
cache actually working ........ 44 tok/s
cache, 124 slots .............. 55 tok/s
speculative decoding alone .... 55 tok/s
both together ................. 70 tok/s ← more than either
parallel GPU/CPU chains ....... 75 tok/s
peak .......................... 80 tok/s
with real context ............. 70+ tok/s
⚠️ WILL IT HELP YOU?
Depends how much of the model fits. On a 3060 with the 35B, about half the experts fit and the gain is large. On a 118B model where only 36 of 256 experts fit, the gain drops to 5%. Below roughly 15–20% resident, a fixed set stops being the right approach at all. Chapter 7 covers where the line is for your card.
🔧 SETUP
Qwen3.6-35B-A3B UD-Q4_K_M
RTX 3060 12GB · Ryzen 5600X · 30GB RAM · Ubuntu 24.04 llama.cpp with MoE expert caching
—
If you run models locally and want to get more out of the hardware you already own, that's what this channel is for. Subscribe there's a lot more coming.
#localllm #llamacpp #rtx3060 #qwen3 #selfhostedai #localai
I built an expert cache for MoE models, keep the hottest experts parked in VRAM, stream the rest from system RAM.
The baseline was 42. This is what it took to find out why, and where it ended up: 80 tokens a second at peak, and still over 70 with real context in the window.
One RTX 3060. A 35B model. The part I did not expect: the cache is worth almost nothing on its own. What makes it worth something is what it does to speculative decoding underneath it.
⚙️ THE TWO FLAGS
Everything else here is the command you already run. These two are new:
--moe-cache-profile [path.csv]
--moe-cache-slots [n]
Full commands, both steps, in the pinned comment.
⏱️ CHAPTERS
0:00 Intro
0:31 The graveyard
2:35 The data says don't
5:47 The build, and the gut punch
7:42 The scheduler betrayal
10:54 Turning it up
14:08 Why it works
17:58 Your GPU
📊 THE NUMBERS
baseline, no cache ............ 42 tok/s
cache "working" ............... 6 tok/s ← the two days
cache actually working ........ 44 tok/s
cache, 124 slots .............. 55 tok/s
speculative decoding alone .... 55 tok/s
both together ................. 70 tok/s ← more than either
parallel GPU/CPU chains ....... 75 tok/s
peak .......................... 80 tok/s
with real context ............. 70+ tok/s
⚠️ WILL IT HELP YOU?
Depends how much of the model fits. On a 3060 with the 35B, about half the experts fit and the gain is large. On a 118B model where only 36 of 256 experts fit, the gain drops to 5%. Below roughly 15–20% resident, a fixed set stops being the right approach at all. Chapter 7 covers where the line is for your card.
🔧 SETUP
Qwen3.6-35B-A3B UD-Q4_K_M
RTX 3060 12GB · Ryzen 5600X · 30GB RAM · Ubuntu 24.04 llama.cpp with MoE expert caching
—
If you run models locally and want to get more out of the hardware you already own, that's what this channel is for. Subscribe there's a lot more coming.
#localllm #llamacpp #rtx3060 #qwen3 #selfhostedai #localai