Uploaded May 2026 | Updated September 2026, 3 weeks ago
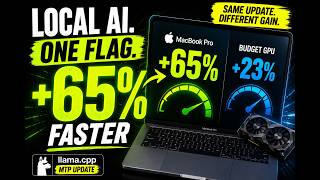
One llama.cpp update just made Local AI 65% faster on a MacBook Pro — and 23% faster on a budget GPU using the exact same flag.
The feature is called Multi-Token Prediction (MTP), recently merged into llama.cpp. And depending on whether your setup is CPU-bound or GPU-bound, the speed gains can be massive.
In this video:
— What MTP / Multi-Token Prediction actually does
— Why Local AI inference suddenly got much faster
— MacBook Pro benchmarks (+65%)
— Budget GPU + MoE offload benchmarks (+23%)
— Why the same llama.cpp update behaves differently on different hardware
— Qwen 3.6 MTP GGUF testing
— ngram-mod speculative decoding explained
— Best llama.cpp flags for local LLM speed
The results:
• MacBook Pro (Metal, dense 27B): 1.65x speedup, 92.8% draft acceptance
• Budget GPU + MoE offload (35B-A3B): 1.23x speedup, 84.4% draft acceptance
Same model family. Same llama.cpp update. Completely different scaling behavior.
If you run Local AI, llama.cpp, Qwen, MoE models, or self-hosted LLMs — this update matters.
━━━━━━━━━━━━━━━━━━━━━━
🕒 CHAPTERS
━━━━━━━━━━━━━━━━━━━━━━
0:00 Local AI just got faster
0:44 What MTP actually does
1:54 MacBook Pro result — +65%
3:04 Budget GPU result — +23%
4:46 Why the gains split
6:28 ngram-mod speculative decoding
7:29 Best settings cheat sheet
━━━━━━━━━━━━━━━━━━━━━━
🔗 RESOURCES
━━━━━━━━━━━━━━━━━━━━━━
• llama.cpp PR #22673 (MTP merge)
github.com/ggml-org/llama.cpp/pull/22673
• Unsloth Qwen 3.6 27B MTP GGUF
huggingface.co/unsloth/Qwen3.6-27B-MTP-GGUF
• Unsloth Qwen 3.6 35B-A3B MTP GGUF
huggingface.co/unsloth/Qwen3.6-35B-A3B-MTP-GGUF
• Previous video: DFlash speculative decoding deep dive
━━━━━━━━━━━━━━━━━━━━━━
🟢 DISCORD
━━━━━━━━━━━━━━━━━━━━━━
Local AI, llama.cpp, homelab builds, weird inference experiments, low-VRAM setups.
If you're building ownership-first AI systems too:
discord.gg/XgBzczAWs
━━━━━━━━━━━━━━━━━━━━━━
I read llama.cpp draft PRs the day they land so you don’t have to.
Subscribe for:
• Local AI
• llama.cpp optimization
• MoE offload experiments
• low-VRAM inference
• self-hosted AI systems
• weird benchmark discoveries
#localai #llamacpp #mtp #qwen #speculativedecoding #ai
One llama.cpp update just made Local AI 65% faster on a MacBook Pro — and 23% faster on a budget GPU using the exact same flag.
The feature is called Multi-Token Prediction (MTP), recently merged into llama.cpp. And depending on whether your setup is CPU-bound or GPU-bound, the speed gains can be massive.
In this video:
— What MTP / Multi-Token Prediction actually does
— Why Local AI inference suddenly got much faster
— MacBook Pro benchmarks (+65%)
— Budget GPU + MoE offload benchmarks (+23%)
— Why the same llama.cpp update behaves differently on different hardware
— Qwen 3.6 MTP GGUF testing
— ngram-mod speculative decoding explained
— Best llama.cpp flags for local LLM speed
The results:
• MacBook Pro (Metal, dense 27B): 1.65x speedup, 92.8% draft acceptance
• Budget GPU + MoE offload (35B-A3B): 1.23x speedup, 84.4% draft acceptance
Same model family. Same llama.cpp update. Completely different scaling behavior.
If you run Local AI, llama.cpp, Qwen, MoE models, or self-hosted LLMs — this update matters.
━━━━━━━━━━━━━━━━━━━━━━
🕒 CHAPTERS
━━━━━━━━━━━━━━━━━━━━━━
0:00 Local AI just got faster
0:44 What MTP actually does
1:54 MacBook Pro result — +65%
3:04 Budget GPU result — +23%
4:46 Why the gains split
6:28 ngram-mod speculative decoding
7:29 Best settings cheat sheet
━━━━━━━━━━━━━━━━━━━━━━
🔗 RESOURCES
━━━━━━━━━━━━━━━━━━━━━━
• llama.cpp PR #22673 (MTP merge)
github.com/ggml-org/llama.cpp/pull/22673
• Unsloth Qwen 3.6 27B MTP GGUF
huggingface.co/unsloth/Qwen3.6-27B-MTP-GGUF
• Unsloth Qwen 3.6 35B-A3B MTP GGUF
huggingface.co/unsloth/Qwen3.6-35B-A3B-MTP-GGUF
• Previous video: DFlash speculative decoding deep dive
━━━━━━━━━━━━━━━━━━━━━━
🟢 DISCORD
━━━━━━━━━━━━━━━━━━━━━━
Local AI, llama.cpp, homelab builds, weird inference experiments, low-VRAM setups.
If you're building ownership-first AI systems too:
discord.gg/XgBzczAWs
━━━━━━━━━━━━━━━━━━━━━━
I read llama.cpp draft PRs the day they land so you don’t have to.
Subscribe for:
• Local AI
• llama.cpp optimization
• MoE offload experiments
• low-VRAM inference
• self-hosted AI systems
• weird benchmark discoveries
#localai #llamacpp #mtp #qwen #speculativedecoding #ai