Uploaded August 2026 | Updated September 2026, 3 weeks ago
Building autonomous agents that actually work requires rethinking your architecture for long-running AI tasks. Learn why minimal design is the key to reliability.
Most developers struggle with agent fragility because they overcomplicate the underlying logic. This video breaks down the essential design principles—minimalism, transparency, and pluggability—required to build systems that handle extended processes without crashing. Whether you are scaling internal tools or building custom automation, these architectural shifts will help you create more stable software.
We also evaluate the trade-offs between cloud infrastructure and local AI agents. Often, local execution provides superior control for complex workflows, making your agents easier to debug and audit. If you are tired of black-box AI systems that fail silently, these concepts will provide a roadmap for better engineering practices.
Which autonomous agents have you abandoned recently and why did they fail? Subscribe for weekly software architecture breakdowns and practical AI engineering guides.
On April 4th, Anthropic stopped covering third-party harnesses under Claude subscription limits. The setup I'd been living in stopped working, so I tried to rebuild it on hardware I own — one RTX 3060 running a 35B model at about 70 tokens a second.
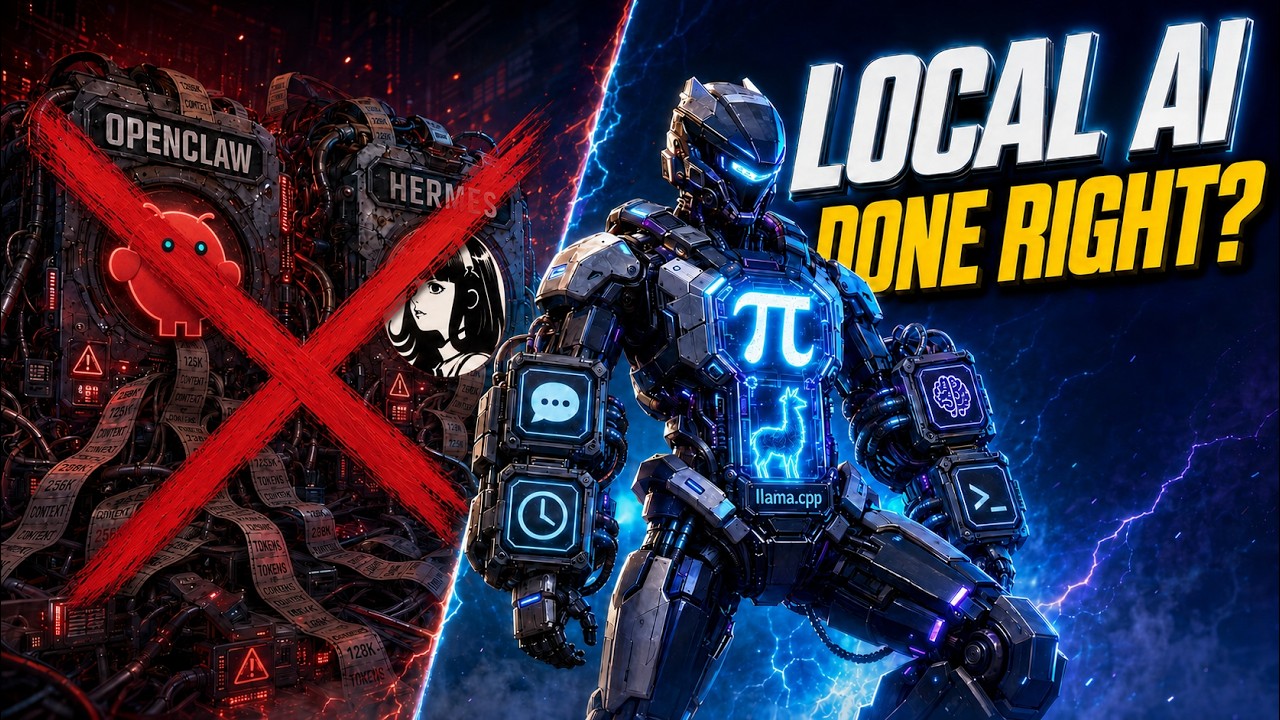
I tried OpenClaw. I tried Hermes. Both beat me. Not because they're bad, but because they were built for a model you rent: they assume tokens are cheap and they don't show you what they're spending them on. On my box I could afford neither the context nor the blindness. So I gave up on autonomous local AI entirely and settled for a coding agent plus some n8n automations.
Then I got annoyed that anything agentic meant leaving my laptop open, and I built a small web UI for a pi session on my server. Then I got lazy and added Telegram. Then schedules. Then memory.
Somewhere in there I looked at what I'd built and realised it was the thing I quit.
This is that story — including the bugs, which are the actual content: four .jsonl files that were supposed to be one conversation, a Telegram deadlock that took a day to see, and a local model that read its own identity file correctly and still told me it was made by Baidu. Each one taught me something about what a harness actually is.
And the part I didn't expect: every design decision that made this good came from the model being local. Context is the budget, so tools have to be earned instead of granted. Latency you'd never notice on a hosted API is painful when you're already waiting on prefill. Small models take instructions literally in ways Claude never does. None of those pressures exist when you're renting frontier tokens — which is exactly why nobody builds for them.
Nothing leaves the network. llama-server on localhost, portal on the LAN or over Tailscale.
⏱️ CHAPTERS
0:00 — The Laptop Is Closed and It's Still Working
0:58 — The Rule That Changed Under Me
2:03 — I Tried the Existing Harnesses. I Lost.
3:15 — One Small Annoyance (and the portal)
4:58 — Then I Got Lazy (Telegram, and the deadlock)
6:32 — Wait — I've Built This Before
7:44 — Schedules, and the Memory Problem
8:41 — "I'm Pi, Created by Baidu"
10:29 — Why It Only Worked Because It's Local
12:12 — What It Actually Is
13:51 — Which One Did You Give Up On?
🔗 LINKS
▶ Pithagoras : github.com/thecodacus/pithagoras
▶ pi : github.com/earendil-works/pi
▶ understory: github.com/thecodacus/understory
🛠️ THE RIG
RTX 3060 12GB
· Ryzen 5 5600X
· 32GB DDR4
Model: qwen36-35b-a3b-mtp (~70 tok/s) (mtp + custom llama.cpp improvement)
· 128k context budget
#localai #aiagents #selfhosted #openclaw #hermes #llamacpp
Building autonomous agents that actually work requires rethinking your architecture for long-running AI tasks. Learn why minimal design is the key to reliability.
Most developers struggle with agent fragility because they overcomplicate the underlying logic. This video breaks down the essential design principles—minimalism, transparency, and pluggability—required to build systems that handle extended processes without crashing. Whether you are scaling internal tools or building custom automation, these architectural shifts will help you create more stable software.
We also evaluate the trade-offs between cloud infrastructure and local AI agents. Often, local execution provides superior control for complex workflows, making your agents easier to debug and audit. If you are tired of black-box AI systems that fail silently, these concepts will provide a roadmap for better engineering practices.
Which autonomous agents have you abandoned recently and why did they fail? Subscribe for weekly software architecture breakdowns and practical AI engineering guides.
On April 4th, Anthropic stopped covering third-party harnesses under Claude subscription limits. The setup I'd been living in stopped working, so I tried to rebuild it on hardware I own — one RTX 3060 running a 35B model at about 70 tokens a second.
I tried OpenClaw. I tried Hermes. Both beat me. Not because they're bad, but because they were built for a model you rent: they assume tokens are cheap and they don't show you what they're spending them on. On my box I could afford neither the context nor the blindness. So I gave up on autonomous local AI entirely and settled for a coding agent plus some n8n automations.
Then I got annoyed that anything agentic meant leaving my laptop open, and I built a small web UI for a pi session on my server. Then I got lazy and added Telegram. Then schedules. Then memory.
Somewhere in there I looked at what I'd built and realised it was the thing I quit.
This is that story — including the bugs, which are the actual content: four .jsonl files that were supposed to be one conversation, a Telegram deadlock that took a day to see, and a local model that read its own identity file correctly and still told me it was made by Baidu. Each one taught me something about what a harness actually is.
And the part I didn't expect: every design decision that made this good came from the model being local. Context is the budget, so tools have to be earned instead of granted. Latency you'd never notice on a hosted API is painful when you're already waiting on prefill. Small models take instructions literally in ways Claude never does. None of those pressures exist when you're renting frontier tokens — which is exactly why nobody builds for them.
Nothing leaves the network. llama-server on localhost, portal on the LAN or over Tailscale.
⏱️ CHAPTERS
0:00 — The Laptop Is Closed and It's Still Working
0:58 — The Rule That Changed Under Me
2:03 — I Tried the Existing Harnesses. I Lost.
3:15 — One Small Annoyance (and the portal)
4:58 — Then I Got Lazy (Telegram, and the deadlock)
6:32 — Wait — I've Built This Before
7:44 — Schedules, and the Memory Problem
8:41 — "I'm Pi, Created by Baidu"
10:29 — Why It Only Worked Because It's Local
12:12 — What It Actually Is
13:51 — Which One Did You Give Up On?
🔗 LINKS
▶ Pithagoras : github.com/thecodacus/pithagoras
▶ pi : github.com/earendil-works/pi
▶ understory: github.com/thecodacus/understory
🛠️ THE RIG
RTX 3060 12GB
· Ryzen 5 5600X
· 32GB DDR4
Model: qwen36-35b-a3b-mtp (~70 tok/s) (mtp + custom llama.cpp improvement)
· 128k context budget
#localai #aiagents #selfhosted #openclaw #hermes #llamacpp