Uploaded September 2026 | Updated September 2026, 1 week ago
Jiaoyang Huang (University of Pennsylvania)
https://simons.berkeley.edu/talks/jiaoyang-huang-university-pennsylvania-2026-09-03
Joint Boot Camp: Spectral Theory Beyond Graphs + Pseudorandomness and High-Dimensional Expansion
Extremal eigenvalues of graphs are of particular interest in theoretical computer science and combinatorics. Specifically, the spectral gap—the difference between the largest and second-largest eigenvalues—measures the expansion properties of a graph.
In this talk, I will begin by providing background on the eigenvalues of random d-regular graphs and their connections to random matrix theory. Then I will discuss our results on eigenvalue rigidity and edge universality for these graphs. Eigenvalue rigidity asserts that, with high probability, each eigenvalue concentrates around its classical location as predicted by the Kesten-McKay distribution. Edge universality states that the second-largest eigenvalue and the smallest eigenvalue of random d-regular graphs converge to the Tracy-Widom distribution from the Gaussian Orthogonal Ensemble. Consequently, approximately 69% of d-regular graphs are Ramanujan graphs. Finally I will present a streamlined framework for proving the convergence to the random matrix statistics based on a microscopic version of the loop equations. These characterizations provide a direct route to universality: it suffices to verify the corresponding approximate loop equations for the ensemble under consideration. In many models, these equations follow from local laws and integration by parts.
Jiaoyang Huang (University of Pennsylvania)
https://simons.berkeley.edu/talks/jiaoyang-huang-university-pennsylvania-2026-09-03
Joint Boot Camp: Spectral Theory Beyond Graphs + Pseudorandomness and High-Dimensional Expansion
Extremal eigenvalues of graphs are of particular interest in theoretical computer science and combinatorics. Specifically, the spectral gap—the difference between the largest and second-largest eigenvalues—measures the expansion properties of a graph.
In this talk, I will begin by providing background on the eigenvalues of random d-regular graphs and their connections to random matrix theory. Then I will discuss our results on eigenvalue rigidity and edge universality for these graphs. Eigenvalue rigidity asserts that, with high probability, each eigenvalue concentrates around its classical location as predicted by the Kesten-McKay distribution. Edge universality states that the second-largest eigenvalue and the smallest eigenvalue of random d-regular graphs converge to the Tracy-Widom distribution from the Gaussian Orthogonal Ensemble. Consequently, approximately 69% of d-regular graphs are Ramanujan graphs. Finally I will present a streamlined framework for proving the convergence to the random matrix statistics based on a microscopic version of the loop equations. These characterizations provide a direct route to universality: it suffices to verify the corresponding approximate loop equations for the ensemble under consideration. In many models, these equations follow from local laws and integration by parts.

![From the Ball-proximal (Broximal) Point Method to Efficient Training of LLM
Peter Richtarik (KAUST)
https://simons.berkeley.edu/talks/peter-richtarik-kaust-2026-02-23
Learning from Heterogeneous Sources
Non-smooth and non-convex global optimization poses significant challenges across various applications, where standard gradient-based methods often struggle. We propose the Ball-Proximal Point Method, Broximal Point Method, or Ball Point Method (BPM) for short – a novel algorithmic framework inspired by the classical Proximal Point Method (PPM) [8], which, as we show, sheds new light on several foundational optimization paradigms and phenomena, including non-convex and non-smooth optimization, acceleration, smoothing, adaptive stepsize selection, and trust-region methods. At the core of BPM lies the ball-proximal (“broximal”) operator, which arises from the classical proximal operator by replacing the quadratic distance penalty by a ball constraint. Surprisingly, and in sharp contrast with the sublinear rate of PPM in the nonsmooth convex regime, we prove that BPM converges linearly and in a finite number of steps in the same regime. Furthermore, by introducing the concept of ball-convexity, we prove that BPM retains the same global convergence guarantees under weaker assumptions, making it a powerful tool for a broader class of potentially non-convex optimization problems. Just like PPM plays the role of a conceptual method inspiring the development of practically efficient algorithms and algorithmic elements, e.g., gradient descent, adaptive step sizes, acceleration [1], and “W” in AdamW [9], we believe that BPM should be understood in the same manner: as a blueprint and inspiration for further development. Generalization non-Euclidean ball constraints can be found in the follow-up work [3].
The Broximal Point Method (BPM) [2] offers an idealized optimization framework based on iteratively minimizing the objective function over norm balls centered at the current iterate. It enjoys striking global convergence guarantees, converging linearly and in a finite number of steps for proper, closed and convex functions. However, its theoretical analysis has so far been confined to the Euclidean geometry. At the same time, emerging trends in deep learning optimization, exemplified by algorithms such as Muon [4] and Scion [6], demonstrate the practical advantages of minimizing over balls defined via non-Euclidean norms which better align with the underlying geometry of the associated loss landscapes. We ask whether the convergence theory of BPM can be extended to this more general, non-Euclidean setting. We give a positive answer, showing that most of the elegant guarantees of the original method carry over to arbitrary norm geometries. Along the way, we clarify which properties are preserved and which necessarily break down when leaving the Euclidean realm. Our analysis positions Non-Euclidean BPM as a conceptual blueprint for understanding a broad class of geometry-aware optimization algorithms, shedding light on the principles behind their practical effectiveness.
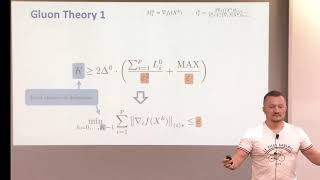
Latest developments in deep learning optimization have brought about radically new algorithms based on the Linear Minimization Oracle (LMO) framework, such as Muon [4] and Scion [6]. After over a decade of Adam’s [5] dominance, these LMO-based methods are emerging as viable replacements, offering several practical advantages such as improved memory efficiency, better hyperparameter transferability, and most importantly, superior empirical performance on large-scale tasks, including LLM training. However, a significant gap remains between their practical use and our current theoretical understanding: prior analyses (1) overlook the layer-wise LMO application of these optimizers in practice, and (2) rely on an unrealistic smoothness assumption, leading to impractically small stepsizes. To address both, we propose a new LMO-based method called Gluon, capturing prior theoretically analyzed methods as special cases, and introduce a new refined generalized smoothness model that captures the layer-wise geometry of neural networks, matches the layer-wise practical implementation of Muon and Scion, and leads to con- vergence guarantees with strong practical predictive power. Unlike prior results, our theoretical stepsizes closely match the fine-tuned values reported in [6]. Our experiments with NanoGPT and CNN confirm that our assumption holds along the optimization trajectory, ultimately closing the gap between theory and practice... From the Ball-proximal (Broximal) Point Method to Efficient Training of LLM](https://i.ytimg.com/vi/Va7ER6bRodA/mqdefault.jpg)