Uploaded June 2026 | Updated September 2026, 2 weeks ago
Vikram Gadagkar (Columbia University)
https://simons.berkeley.edu/talks/vikram-gadagkar-columbia-university-2026-06-10
Topics in Intelligence: World Models and Social Reasoning
Many natural motor skills, like speaking or locomotion, are learned through trial-and-error over development. It has long been hypothesized that dopamine plays a critical role in this process, motivated by artificial learning experiments. Dopamine in the basal ganglia is thought to guide reward-based trial-and-error learning by encoding reward prediction errors, decreasing after worse-than-predicted rewards and increasing after better-than-predicted ones. Similarly, by changing perceived song quality with distorted auditory feedback, our previous work in adult zebra finches showed that dopamine in Area X, the singing-related basal ganglia, encodes performance prediction error: dopamine is suppressed after worse-than-predicted (distorted syllables) and activated after better-than-predicted (undistorted syllables) performance. However, it remains unknown if the learning of natural behaviors, such as developmental vocal learning, occurs through dopamine-based reinforcement. Here we tracked song learning trajectories in juvenile zebra finches and used fiber photometry to monitor concurrent dopamine activity in Area X. We found that dopamine was activated after syllable renditions that were closer to the eventual adult version of the song and suppressed after renditions that were farther away. Furthermore, the relationship between dopamine and song revealed that dopamine predicted the future evolution of song, suggesting that dopamine drives behavior. Finally, dopamine activity was explained by the contrast between the quality of the current rendition against the recent history of renditions, consistent with its hypothesized role of encoding prediction errors. Reinforcement learning algorithms explain learning in reward-based laboratory tasks as well as drive autonomous learning in artificial intelligence. Our results suggest that complex natural behaviors in biological systems can also be learned through dopamine-mediated reinforcement.
Vikram Gadagkar (Columbia University)
https://simons.berkeley.edu/talks/vikram-gadagkar-columbia-university-2026-06-10
Topics in Intelligence: World Models and Social Reasoning
Many natural motor skills, like speaking or locomotion, are learned through trial-and-error over development. It has long been hypothesized that dopamine plays a critical role in this process, motivated by artificial learning experiments. Dopamine in the basal ganglia is thought to guide reward-based trial-and-error learning by encoding reward prediction errors, decreasing after worse-than-predicted rewards and increasing after better-than-predicted ones. Similarly, by changing perceived song quality with distorted auditory feedback, our previous work in adult zebra finches showed that dopamine in Area X, the singing-related basal ganglia, encodes performance prediction error: dopamine is suppressed after worse-than-predicted (distorted syllables) and activated after better-than-predicted (undistorted syllables) performance. However, it remains unknown if the learning of natural behaviors, such as developmental vocal learning, occurs through dopamine-based reinforcement. Here we tracked song learning trajectories in juvenile zebra finches and used fiber photometry to monitor concurrent dopamine activity in Area X. We found that dopamine was activated after syllable renditions that were closer to the eventual adult version of the song and suppressed after renditions that were farther away. Furthermore, the relationship between dopamine and song revealed that dopamine predicted the future evolution of song, suggesting that dopamine drives behavior. Finally, dopamine activity was explained by the contrast between the quality of the current rendition against the recent history of renditions, consistent with its hypothesized role of encoding prediction errors. Reinforcement learning algorithms explain learning in reward-based laboratory tasks as well as drive autonomous learning in artificial intelligence. Our results suggest that complex natural behaviors in biological systems can also be learned through dopamine-mediated reinforcement.

![From the Ball-proximal (Broximal) Point Method to Efficient Training of LLM
Peter Richtarik (KAUST)
https://simons.berkeley.edu/talks/peter-richtarik-kaust-2026-02-23
Learning from Heterogeneous Sources
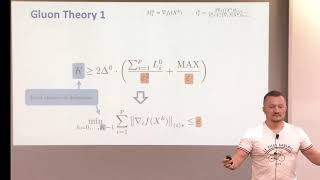
Non-smooth and non-convex global optimization poses significant challenges across various applications, where standard gradient-based methods often struggle. We propose the Ball-Proximal Point Method, Broximal Point Method, or Ball Point Method (BPM) for short – a novel algorithmic framework inspired by the classical Proximal Point Method (PPM) [8], which, as we show, sheds new light on several foundational optimization paradigms and phenomena, including non-convex and non-smooth optimization, acceleration, smoothing, adaptive stepsize selection, and trust-region methods. At the core of BPM lies the ball-proximal (“broximal”) operator, which arises from the classical proximal operator by replacing the quadratic distance penalty by a ball constraint. Surprisingly, and in sharp contrast with the sublinear rate of PPM in the nonsmooth convex regime, we prove that BPM converges linearly and in a finite number of steps in the same regime. Furthermore, by introducing the concept of ball-convexity, we prove that BPM retains the same global convergence guarantees under weaker assumptions, making it a powerful tool for a broader class of potentially non-convex optimization problems. Just like PPM plays the role of a conceptual method inspiring the development of practically efficient algorithms and algorithmic elements, e.g., gradient descent, adaptive step sizes, acceleration [1], and “W” in AdamW [9], we believe that BPM should be understood in the same manner: as a blueprint and inspiration for further development. Generalization non-Euclidean ball constraints can be found in the follow-up work [3].
The Broximal Point Method (BPM) [2] offers an idealized optimization framework based on iteratively minimizing the objective function over norm balls centered at the current iterate. It enjoys striking global convergence guarantees, converging linearly and in a finite number of steps for proper, closed and convex functions. However, its theoretical analysis has so far been confined to the Euclidean geometry. At the same time, emerging trends in deep learning optimization, exemplified by algorithms such as Muon [4] and Scion [6], demonstrate the practical advantages of minimizing over balls defined via non-Euclidean norms which better align with the underlying geometry of the associated loss landscapes. We ask whether the convergence theory of BPM can be extended to this more general, non-Euclidean setting. We give a positive answer, showing that most of the elegant guarantees of the original method carry over to arbitrary norm geometries. Along the way, we clarify which properties are preserved and which necessarily break down when leaving the Euclidean realm. Our analysis positions Non-Euclidean BPM as a conceptual blueprint for understanding a broad class of geometry-aware optimization algorithms, shedding light on the principles behind their practical effectiveness.
Latest developments in deep learning optimization have brought about radically new algorithms based on the Linear Minimization Oracle (LMO) framework, such as Muon [4] and Scion [6]. After over a decade of Adam’s [5] dominance, these LMO-based methods are emerging as viable replacements, offering several practical advantages such as improved memory efficiency, better hyperparameter transferability, and most importantly, superior empirical performance on large-scale tasks, including LLM training. However, a significant gap remains between their practical use and our current theoretical understanding: prior analyses (1) overlook the layer-wise LMO application of these optimizers in practice, and (2) rely on an unrealistic smoothness assumption, leading to impractically small stepsizes. To address both, we propose a new LMO-based method called Gluon, capturing prior theoretically analyzed methods as special cases, and introduce a new refined generalized smoothness model that captures the layer-wise geometry of neural networks, matches the layer-wise practical implementation of Muon and Scion, and leads to con- vergence guarantees with strong practical predictive power. Unlike prior results, our theoretical stepsizes closely match the fine-tuned values reported in [6]. Our experiments with NanoGPT and CNN confirm that our assumption holds along the optimization trajectory, ultimately closing the gap between theory and practice... From the Ball-proximal (Broximal) Point Method to Efficient Training of LLM](https://i.ytimg.com/vi/Va7ER6bRodA/mqdefault.jpg)