Uploaded October 2026 | Updated November 2026, 3 days ago
A used RTX 4090 now costs more than it did brand new. It launched at $1,600, used ones now sell for around $2,000,
and the new RTX 5090 costs around $2,000 more than that. So is the RTX 5090 worth the extra money for local AI?
I compared my RTX 5090 with community RTX 4090 tests on Qwen 3.8 27B. My RTX 5090 hit 74 tokens per second,
the RTX 4090 got around 47 tokens per second without MTP. Roughly 1.5× faster.
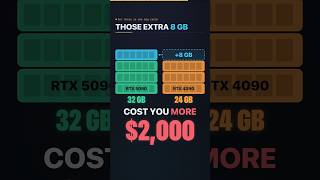
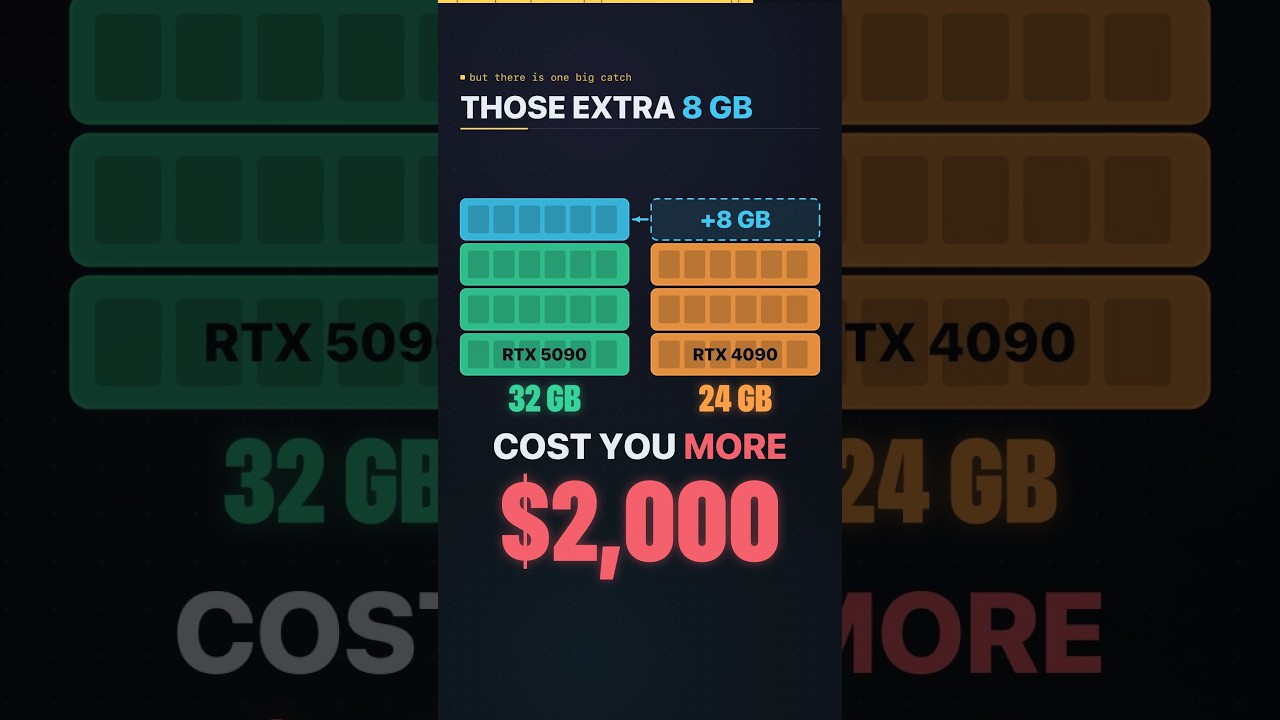
But speed is not the real difference. Memory is. The RTX 5090 has 32 GB of VRAM, the RTX 4090 has 24 GB.
VRAM is the GPU's own memory: a bigger desk holds a bigger book and more notes. With 32 GB, Qwen 3.8 27B ran with
256,000 tokens of context. On 24 GB, testers had to compress the model's working memory and cut the context,
and the 8-bit version of the 27B model fits only on the RTX 5090.
The catch: those extra 8 GB cost you $2,000 more.
My verdict: for 4-bit models up to around 30B parameters and normal chat, buy a used RTX 4090.
For long context or 8-bit quality, pay for the RTX 5090.
Would you pay this extra $2,000 for 8 GB more VRAM? Tell me in the comments.
#rtx5090 #rtx4090 #localai #llm #qwen #vram #gpu #shorts
A used RTX 4090 now costs more than it did brand new. It launched at $1,600, used ones now sell for around $2,000,
and the new RTX 5090 costs around $2,000 more than that. So is the RTX 5090 worth the extra money for local AI?
I compared my RTX 5090 with community RTX 4090 tests on Qwen 3.8 27B. My RTX 5090 hit 74 tokens per second,
the RTX 4090 got around 47 tokens per second without MTP. Roughly 1.5× faster.
But speed is not the real difference. Memory is. The RTX 5090 has 32 GB of VRAM, the RTX 4090 has 24 GB.
VRAM is the GPU's own memory: a bigger desk holds a bigger book and more notes. With 32 GB, Qwen 3.8 27B ran with
256,000 tokens of context. On 24 GB, testers had to compress the model's working memory and cut the context,
and the 8-bit version of the 27B model fits only on the RTX 5090.
The catch: those extra 8 GB cost you $2,000 more.
My verdict: for 4-bit models up to around 30B parameters and normal chat, buy a used RTX 4090.
For long context or 8-bit quality, pay for the RTX 5090.
Would you pay this extra $2,000 for 8 GB more VRAM? Tell me in the comments.
#rtx5090 #rtx4090 #localai #llm #qwen #vram #gpu #shorts