Uploaded October 2026 | Updated November 2026, 2 days ago
This 180-billion-parameter AI model runs on a PC without any GPU. Qwen 3.8 Flash Next is Alibaba's 180B model.
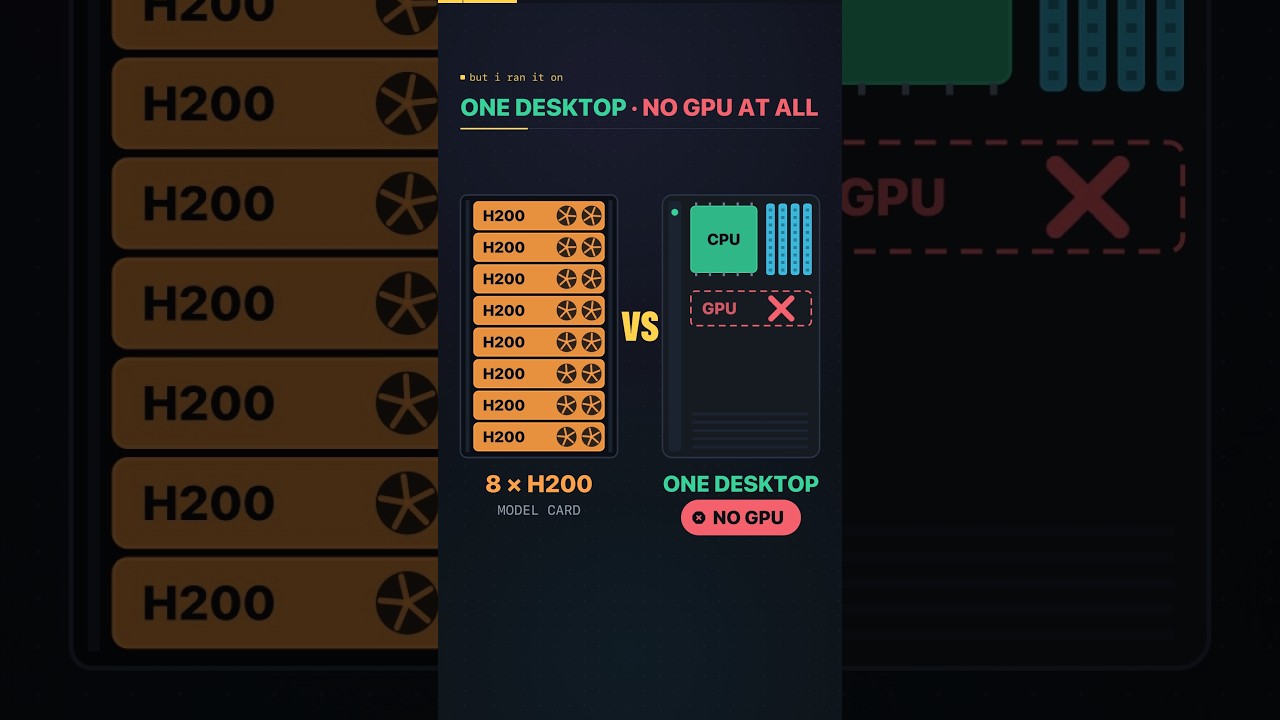
Its model card recommends 8 H200 GPUs, but I ran it on a single desktop with no GPU at all, using 96 GB of normal RAM.
The trick: it's a mixture-of-experts model. It has 180 billion parameters, but only around 6 billion are active for each token.
I used the 1-bit version. On CPU alone I got 11 tokens per second; adding an RTX 5090 took it to 52 tokens per second.
It even beat 4-bit Qwen 3.8 27B on my standard text benchmark.
The catch is long documents: with CPU only, a 30,000-token document took around 16 minutes just to generate the first word.
My verdict: for short chats, a CPU with enough RAM can actually work; for long documents you need a GPU.
1-bit 180B or 4-bit 27B: which one would you run? Let me know in the comments.
Full benchmark: kgptalkie.com/tutorials/llm-benchmarking/qwen-3-8-flash-next-on-cpu-only
#qwen #localai #llm #moe #cpu #rtx5090 #shorts
qwen 3.8 flash next, qwen, alibaba qwen, 180b model, run llm on cpu, no gpu, cpu only llm, local llm, local ai, mixture of experts, moe,
1-bit quantization, gguf, unsloth, rtx 5090, h200, 96gb ram, tokens per second, qwen 3.8 27b, llm benchmark, long context, kgptalkie
This 180-billion-parameter AI model runs on a PC without any GPU. Qwen 3.8 Flash Next is Alibaba's 180B model.
Its model card recommends 8 H200 GPUs, but I ran it on a single desktop with no GPU at all, using 96 GB of normal RAM.
The trick: it's a mixture-of-experts model. It has 180 billion parameters, but only around 6 billion are active for each token.
I used the 1-bit version. On CPU alone I got 11 tokens per second; adding an RTX 5090 took it to 52 tokens per second.
It even beat 4-bit Qwen 3.8 27B on my standard text benchmark.
The catch is long documents: with CPU only, a 30,000-token document took around 16 minutes just to generate the first word.
My verdict: for short chats, a CPU with enough RAM can actually work; for long documents you need a GPU.
1-bit 180B or 4-bit 27B: which one would you run? Let me know in the comments.
Full benchmark: kgptalkie.com/tutorials/llm-benchmarking/qwen-3-8-flash-next-on-cpu-only
#qwen #localai #llm #moe #cpu #rtx5090 #shorts
qwen 3.8 flash next, qwen, alibaba qwen, 180b model, run llm on cpu, no gpu, cpu only llm, local llm, local ai, mixture of experts, moe,
1-bit quantization, gguf, unsloth, rtx 5090, h200, 96gb ram, tokens per second, qwen 3.8 27b, llm benchmark, long context, kgptalkie