Uploaded August 2026 | Updated September 2026, 2 weeks ago
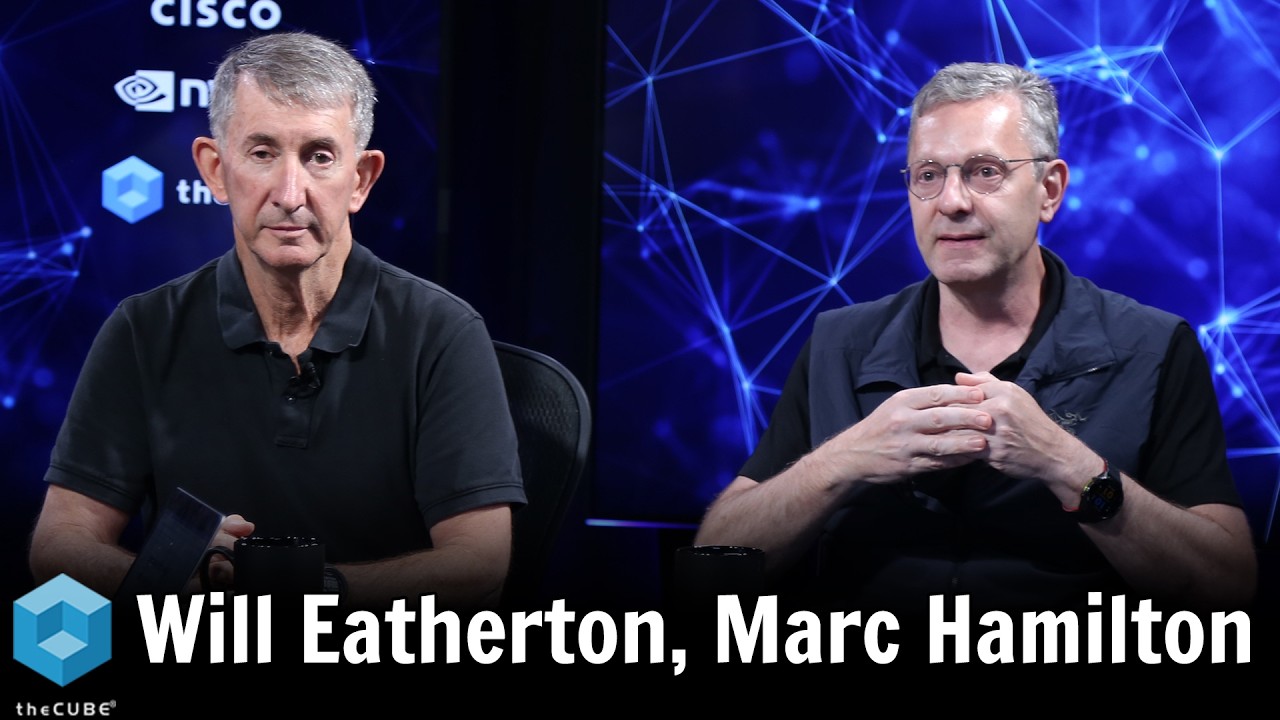
In this interview from "Cisco Secure AI Factory With Nvidia Expands to Rack Scale," Will Eatherton, senior vice president and head of networking engineering at Cisco, joins Marc Hamilton, vice president of solution architecture and engineering at NVIDIA, to talk with theCUBE's John Furrier about how validated rack-scale infrastructure is closing the gap between acquiring GPUs and operating production-ready AI factories. Eatherton details how full rack-scale compute with liquid cooling, spanning HGX, MGX and NVL72 form factors, now integrates Cisco switches for consistent management across scale-out and scale-across networking. He explains the respective roles of Cisco Silicon One and NVIDIA Spectrum-X in delivering AI-optimized networking, while Cisco Cloud Control brings unified visibility and agentic operations across the stack. Hamilton highlights why NVIDIA's reference architecture, built around the NCCL communications library, is essential for troubleshooting performance across complex, multi-vendor GPU clusters.
The conversation also explores how Cisco Validated Designs and joint testing checklists compress deployment timelines from months to weeks, helping neoclouds, sovereign AI programs and enterprises improve GPU utilization and accelerate time to first token. Eatherton unpacks the evolving complexity of multi-tenancy, from partitioning by end customer to subdividing by department and workload, and how Ethernet-based architectures are adapting to meet those demands. Hamilton details how software optimization has driven inference costs down by orders of magnitude on the Blackwell platform, underscoring the importance of continuously upgrading AI factories after deployment. From on-premises supercomputers in hospitals to AI extending toward the telco edge, Eatherton and Hamilton outline a roadmap for how organizations can move AI factories from planning to Day 2 operations faster and with less risk.
Find more SiliconANGLE news and analysis siliconangle.com
Follow theCUBE's wall-to-wall event coverage siliconangle.com/events
Learn about the latest theCUBE events thecube.net
00:00 - Intro
00:06 - Unlocking AI Potential: Cisco-NVIDIA Partnership and Infrastructure
03:34 - Integrating AI: Architecture and Enterprise Synergy
06:52 - Optimizing AI: Managing Complexity and Ensuring Performance
09:29 - Inference in AI and Next-Gen Enterprise Architectures
13:28 - Securing the Future: Multi-Tenancy and Long-Term Perspectives in AI Factories
19:17 - AI Evolution: Enterprise, Edge and Future Horizons
#theCUBE #CiscoNvidiaAIFactory #theCUBEresearch #Cisco #NVIDIA #AIInfrastructure #EdgeComputing
In this interview from "Cisco Secure AI Factory With Nvidia Expands to Rack Scale," Will Eatherton, senior vice president and head of networking engineering at Cisco, joins Marc Hamilton, vice president of solution architecture and engineering at NVIDIA, to talk with theCUBE's John Furrier about how validated rack-scale infrastructure is closing the gap between acquiring GPUs and operating production-ready AI factories. Eatherton details how full rack-scale compute with liquid cooling, spanning HGX, MGX and NVL72 form factors, now integrates Cisco switches for consistent management across scale-out and scale-across networking. He explains the respective roles of Cisco Silicon One and NVIDIA Spectrum-X in delivering AI-optimized networking, while Cisco Cloud Control brings unified visibility and agentic operations across the stack. Hamilton highlights why NVIDIA's reference architecture, built around the NCCL communications library, is essential for troubleshooting performance across complex, multi-vendor GPU clusters.
The conversation also explores how Cisco Validated Designs and joint testing checklists compress deployment timelines from months to weeks, helping neoclouds, sovereign AI programs and enterprises improve GPU utilization and accelerate time to first token. Eatherton unpacks the evolving complexity of multi-tenancy, from partitioning by end customer to subdividing by department and workload, and how Ethernet-based architectures are adapting to meet those demands. Hamilton details how software optimization has driven inference costs down by orders of magnitude on the Blackwell platform, underscoring the importance of continuously upgrading AI factories after deployment. From on-premises supercomputers in hospitals to AI extending toward the telco edge, Eatherton and Hamilton outline a roadmap for how organizations can move AI factories from planning to Day 2 operations faster and with less risk.
Find more SiliconANGLE news and analysis siliconangle.com
Follow theCUBE's wall-to-wall event coverage siliconangle.com/events
Learn about the latest theCUBE events thecube.net
00:00 - Intro
00:06 - Unlocking AI Potential: Cisco-NVIDIA Partnership and Infrastructure
03:34 - Integrating AI: Architecture and Enterprise Synergy
06:52 - Optimizing AI: Managing Complexity and Ensuring Performance
09:29 - Inference in AI and Next-Gen Enterprise Architectures
13:28 - Securing the Future: Multi-Tenancy and Long-Term Perspectives in AI Factories
19:17 - AI Evolution: Enterprise, Edge and Future Horizons
#theCUBE #CiscoNvidiaAIFactory #theCUBEresearch #Cisco #NVIDIA #AIInfrastructure #EdgeComputing