Uploaded April 2022 | Updated September 2026, 6 hours ago
ArtIAMAS Seminar Series: Iterative Preconditioning for Accelerating Machine Learning Problems
Nikhil Chopra
Professor
Department of Mechanical Engineering
University of Maryland at College Park
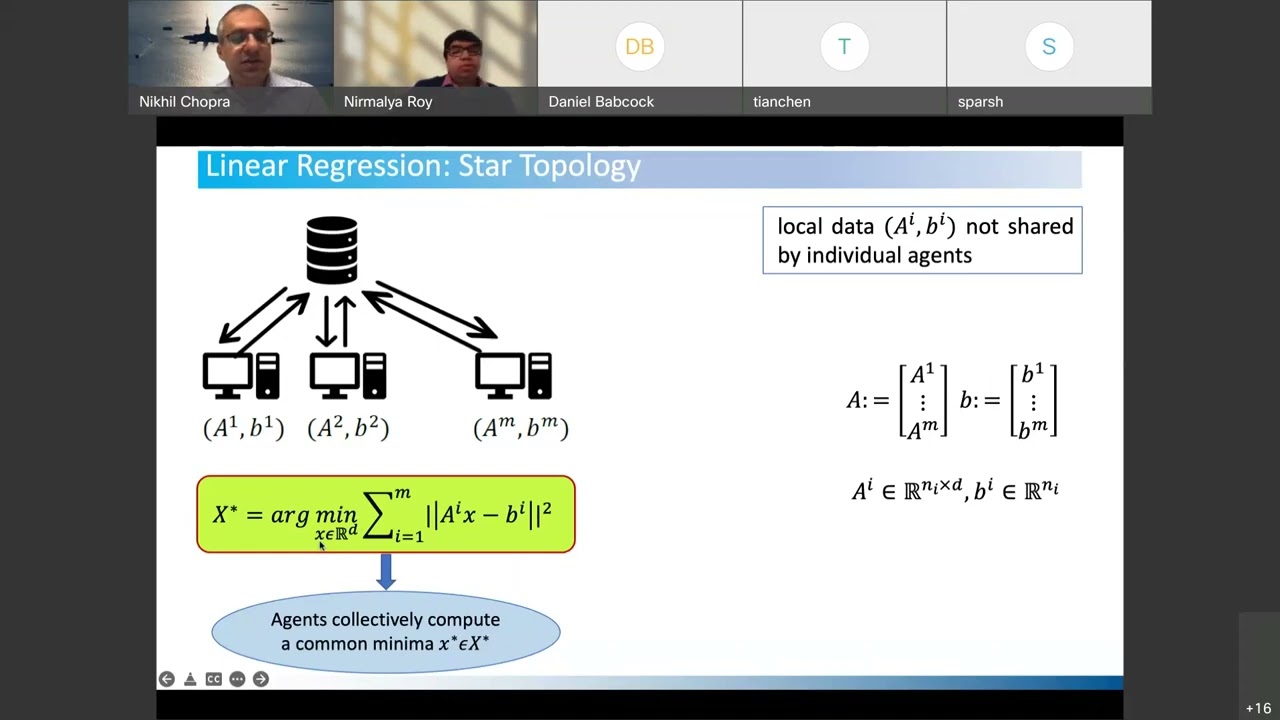
We study a new approach to accelerating machine learning problems in this talk. The system comprises multiple agents, each with a set of local data points and an associated local cost function. The agents are connected to a server, and there is no inter-agent communication. The agents' goal is to learn a parameter vector that optimizes the aggregate of their local costs without revealing their local data points. We propose an iterative preconditioning technique to mitigate the deleterious effects of the cost function's conditioning on the convergence rate of distributed gradient-descent. Unlike the conventional preconditioning techniques, the pre-conditioner matrix in our proposed technique updates iteratively to facilitate implementation on the distributed network. In the particular case when the minimizer of the aggregate cost is unique, our algorithm converges superlinearly. We demonstrate our algorithm's superior performance in machine learning, distributed estimation, and beamforming problems, thereby demonstrating the proposed algorithm's efficiency for distributively solving nonconvex optimization problems.
For more information on the Maryland Robotics Center see:
https://robotics.umd.edu
ArtIAMAS Seminar Series: Iterative Preconditioning for Accelerating Machine Learning Problems
Nikhil Chopra
Professor
Department of Mechanical Engineering
University of Maryland at College Park
We study a new approach to accelerating machine learning problems in this talk. The system comprises multiple agents, each with a set of local data points and an associated local cost function. The agents are connected to a server, and there is no inter-agent communication. The agents' goal is to learn a parameter vector that optimizes the aggregate of their local costs without revealing their local data points. We propose an iterative preconditioning technique to mitigate the deleterious effects of the cost function's conditioning on the convergence rate of distributed gradient-descent. Unlike the conventional preconditioning techniques, the pre-conditioner matrix in our proposed technique updates iteratively to facilitate implementation on the distributed network. In the particular case when the minimizer of the aggregate cost is unique, our algorithm converges superlinearly. We demonstrate our algorithm's superior performance in machine learning, distributed estimation, and beamforming problems, thereby demonstrating the proposed algorithm's efficiency for distributively solving nonconvex optimization problems.
For more information on the Maryland Robotics Center see:
https://robotics.umd.edu