Uploaded November 2025 | Updated November 2026, 4 days ago
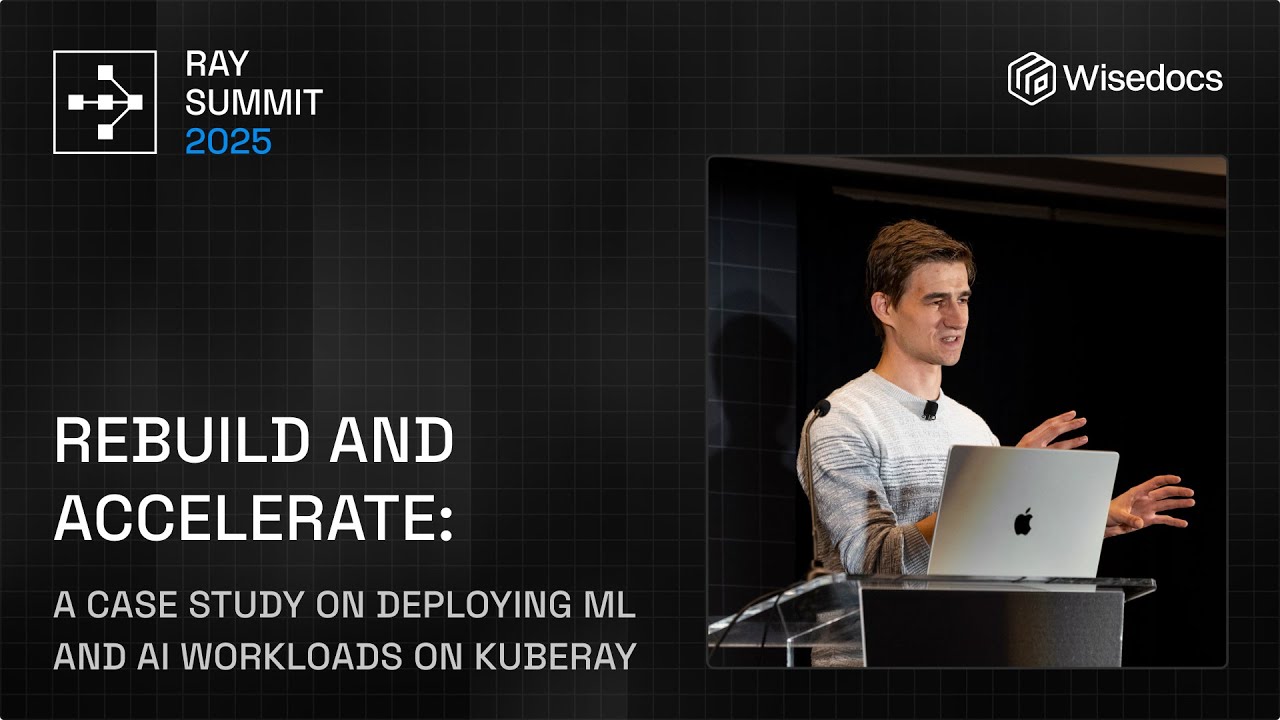
At Ray Summit 2025, Denys Linkov from Wisedocs shares how the company rebuilt its ML and AI serving layer on KubeRay—unlocking major gains in performance, cost efficiency, and deployment velocity.
He begins by outlining the challenges and opportunities involved in redesigning a production-grade serving stack. Wisedocs migrated 10 models to KubeRay to power both real-time and batch workloads, achieving a 50% reduction in cost while improving throughput by 10×. Denys walks through the architectural decisions that made this possible, from compute orchestration to workload isolation and scaling strategies.
The talk also covers the information and technical architecture that enabled Wisedocs to cut its time-to-production dramatically—from one month to just two days. Denys highlights how internal abstractions, standardized deployment patterns, and Ray’s distributed execution model streamlined the entire development-to-production cycle.
Finally, he discusses the tradeoffs of serving GenAI models versus encoder-based models within an internal Kubernetes environment, sharing lessons learned on performance tuning, resource management, and operational complexity.
Attendees will gain practical insights into modernizing ML serving stacks with Ray and KubeRay, balancing efficiency with reliability, and accelerating production deployment at scale.
Subscribe to our YouTube channel to stay up-to-date on the future of AI! youtube.com/c/anyscale
🔗 Connect with us:
LinkedIn: linkedin.com/company/joinanyscale
X: https://x.com/anyscalecompute
Website: anyscale.com
At Ray Summit 2025, Denys Linkov from Wisedocs shares how the company rebuilt its ML and AI serving layer on KubeRay—unlocking major gains in performance, cost efficiency, and deployment velocity.
He begins by outlining the challenges and opportunities involved in redesigning a production-grade serving stack. Wisedocs migrated 10 models to KubeRay to power both real-time and batch workloads, achieving a 50% reduction in cost while improving throughput by 10×. Denys walks through the architectural decisions that made this possible, from compute orchestration to workload isolation and scaling strategies.
The talk also covers the information and technical architecture that enabled Wisedocs to cut its time-to-production dramatically—from one month to just two days. Denys highlights how internal abstractions, standardized deployment patterns, and Ray’s distributed execution model streamlined the entire development-to-production cycle.
Finally, he discusses the tradeoffs of serving GenAI models versus encoder-based models within an internal Kubernetes environment, sharing lessons learned on performance tuning, resource management, and operational complexity.
Attendees will gain practical insights into modernizing ML serving stacks with Ray and KubeRay, balancing efficiency with reliability, and accelerating production deployment at scale.
Subscribe to our YouTube channel to stay up-to-date on the future of AI! youtube.com/c/anyscale
🔗 Connect with us:
LinkedIn: linkedin.com/company/joinanyscale
X: https://x.com/anyscalecompute
Website: anyscale.com