Uploaded September 2026 | Updated November 2026, 2 hours ago
What if robot learning could pre-train on freeform human video instead of relying solely on expensive robot action data?
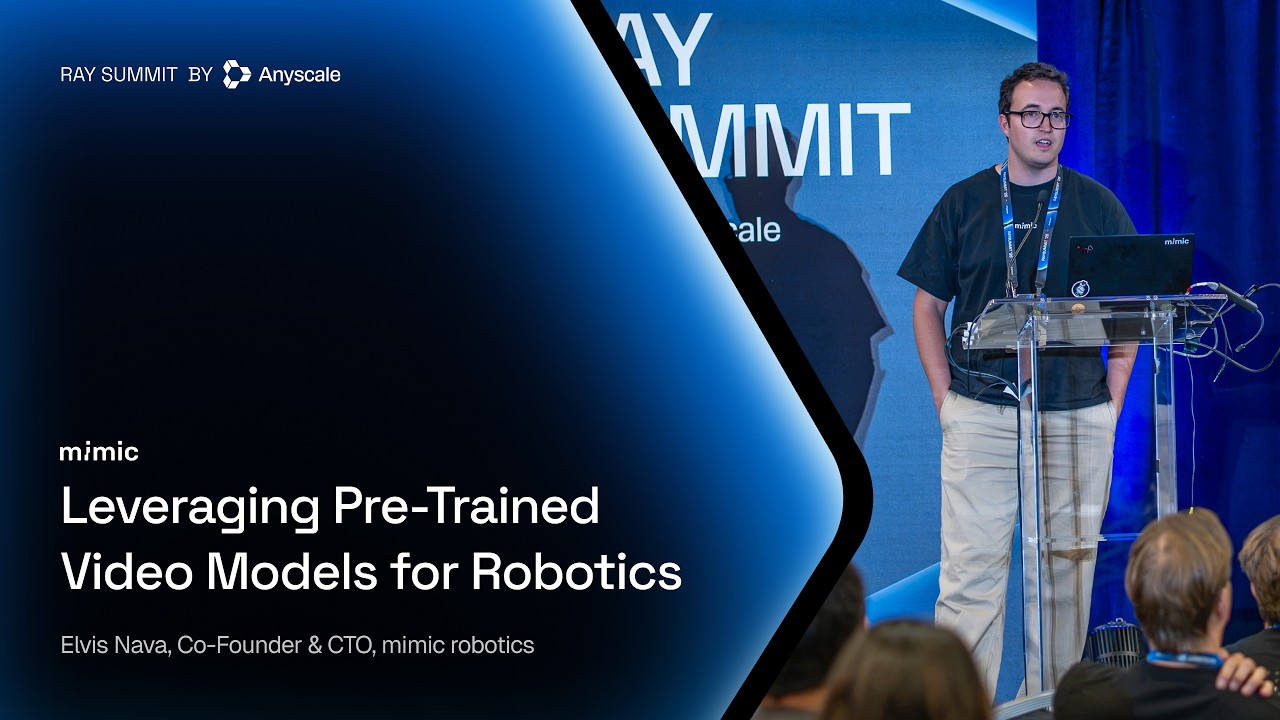
At Ray Summit 2026, Elvis Nava, co-founder and CTO of mimic robotics, introduces Video Action Models, a model class that repurposes generative video model backbones for general-purpose dexterous robot control.
You'll leave with a view of a new frontier for robot learning.
Liked this video? Check out other Ray Summit breakout session recordings: youtube.com/playlist?list=PLZNaJyYZRPdo
Subscribe to our YouTube channel to stay up-to-date on the future of AI: youtube.com/c/anyscale
🔗 Connect with us:
LinkedIn: linkedin.com/company/joinanyscale
X: https://x.com/anyscalecompute
Website: anyscale.com
What if robot learning could pre-train on freeform human video instead of relying solely on expensive robot action data?
At Ray Summit 2026, Elvis Nava, co-founder and CTO of mimic robotics, introduces Video Action Models, a model class that repurposes generative video model backbones for general-purpose dexterous robot control.
You'll leave with a view of a new frontier for robot learning.
Liked this video? Check out other Ray Summit breakout session recordings: youtube.com/playlist?list=PLZNaJyYZRPdo
Subscribe to our YouTube channel to stay up-to-date on the future of AI: youtube.com/c/anyscale
🔗 Connect with us:
LinkedIn: linkedin.com/company/joinanyscale
X: https://x.com/anyscalecompute
Website: anyscale.com