Uploaded November 2026 | Updated November 2026, 2 days ago
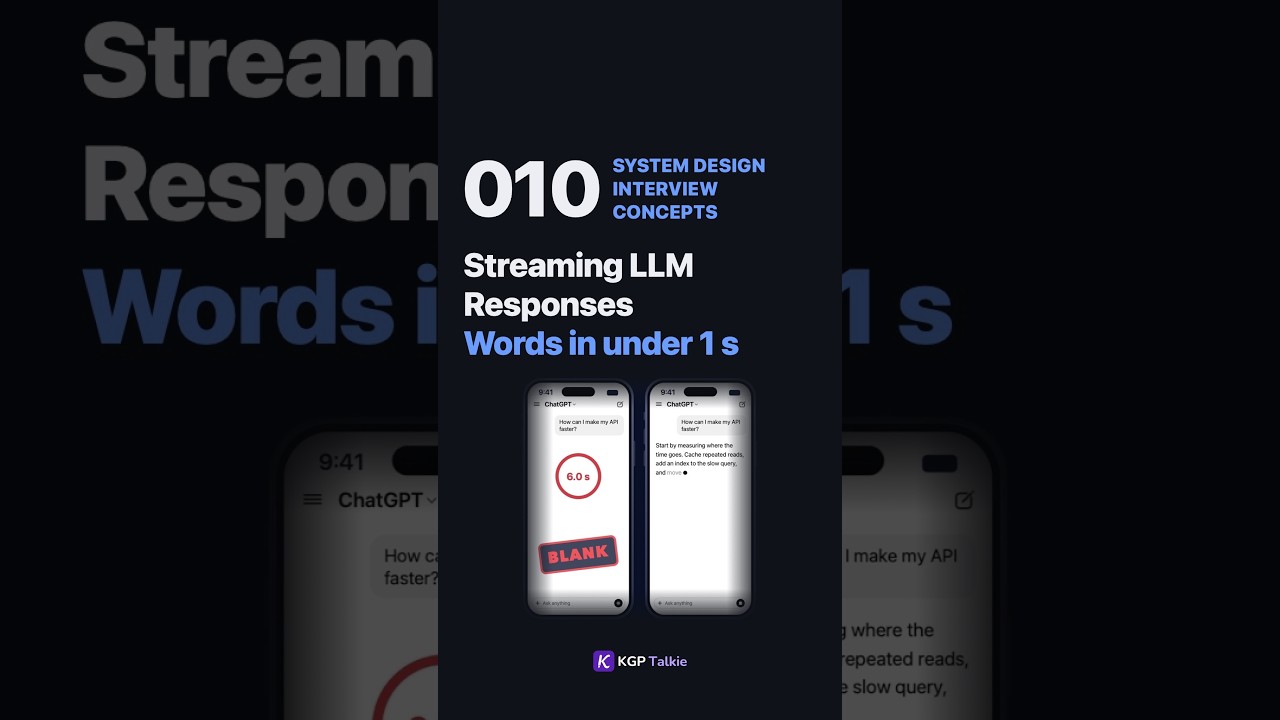
Six seconds staring at a blank screen, or words in under a second?
Why does ChatGPT look like it's typing its answer word by word? An LLM produces one token at a time. Say an answer is 300 tokens and the model writes 50 tokens per second: the full answer takes 6 seconds. Wait for all of it, and the user stares at a blank screen.
Step 1, streaming: send every token the moment it's made. The usual way is SSE, server-sent events: one HTTP response stays open and the server pushes each new token as a small event. The first words show up in under a second.
Step 2, batching: for every token the GPU reads all the model's weights from memory, so for one user the compute cores mostly sit idle. Generate the next token for, say, 32 users in one pass: weights read once, 32 tokens instead of one. Each user is a little slower, the GPU's total output is many times higher.
Step 3, continuous batching: a static batch waits for its longest answer (20 tokens vs 500, the short one's slot sits empty). Continuous batching lets finished requests leave and new ones join after every step.
Step 4, KV cache memory: every request keeps the keys and values of every token in GPU memory, so memory, not compute, decides how many users run at once. Reserving the maximum length up front wastes most of it; vLLM's PagedAttention stores the cache in small fixed-size blocks, like an operating system's memory pages, handed out as needed. Far more requests fit on the same GPU.
The catch: streaming doesn't finish sooner, 6 seconds is still 6 seconds, it just feels shorter. A proxy or load balancer that buffers the response breaks streaming. And every stream is a long-lived connection, so the gateway holds thousands of them.
Next: in today's System Design Interview reel, design ChatGPT. Comment and tell me: answers streamed, or all at once? Follow for the full series.
kgptalkie.com
#shorts #SystemDesign #LLM #ChatGPT #GPU #Streaming #KVCache #vLLM #Backend #DistributedSystems #SystemDesignConcepts #KGPTalkie
Six seconds staring at a blank screen, or words in under a second?
Why does ChatGPT look like it's typing its answer word by word? An LLM produces one token at a time. Say an answer is 300 tokens and the model writes 50 tokens per second: the full answer takes 6 seconds. Wait for all of it, and the user stares at a blank screen.
Step 1, streaming: send every token the moment it's made. The usual way is SSE, server-sent events: one HTTP response stays open and the server pushes each new token as a small event. The first words show up in under a second.
Step 2, batching: for every token the GPU reads all the model's weights from memory, so for one user the compute cores mostly sit idle. Generate the next token for, say, 32 users in one pass: weights read once, 32 tokens instead of one. Each user is a little slower, the GPU's total output is many times higher.
Step 3, continuous batching: a static batch waits for its longest answer (20 tokens vs 500, the short one's slot sits empty). Continuous batching lets finished requests leave and new ones join after every step.
Step 4, KV cache memory: every request keeps the keys and values of every token in GPU memory, so memory, not compute, decides how many users run at once. Reserving the maximum length up front wastes most of it; vLLM's PagedAttention stores the cache in small fixed-size blocks, like an operating system's memory pages, handed out as needed. Far more requests fit on the same GPU.
The catch: streaming doesn't finish sooner, 6 seconds is still 6 seconds, it just feels shorter. A proxy or load balancer that buffers the response breaks streaming. And every stream is a long-lived connection, so the gateway holds thousands of them.
Next: in today's System Design Interview reel, design ChatGPT. Comment and tell me: answers streamed, or all at once? Follow for the full series.
kgptalkie.com
#shorts #SystemDesign #LLM #ChatGPT #GPU #Streaming #KVCache #vLLM #Backend #DistributedSystems #SystemDesignConcepts #KGPTalkie