Uploaded October 2026 | Updated November 2026, 2 days ago
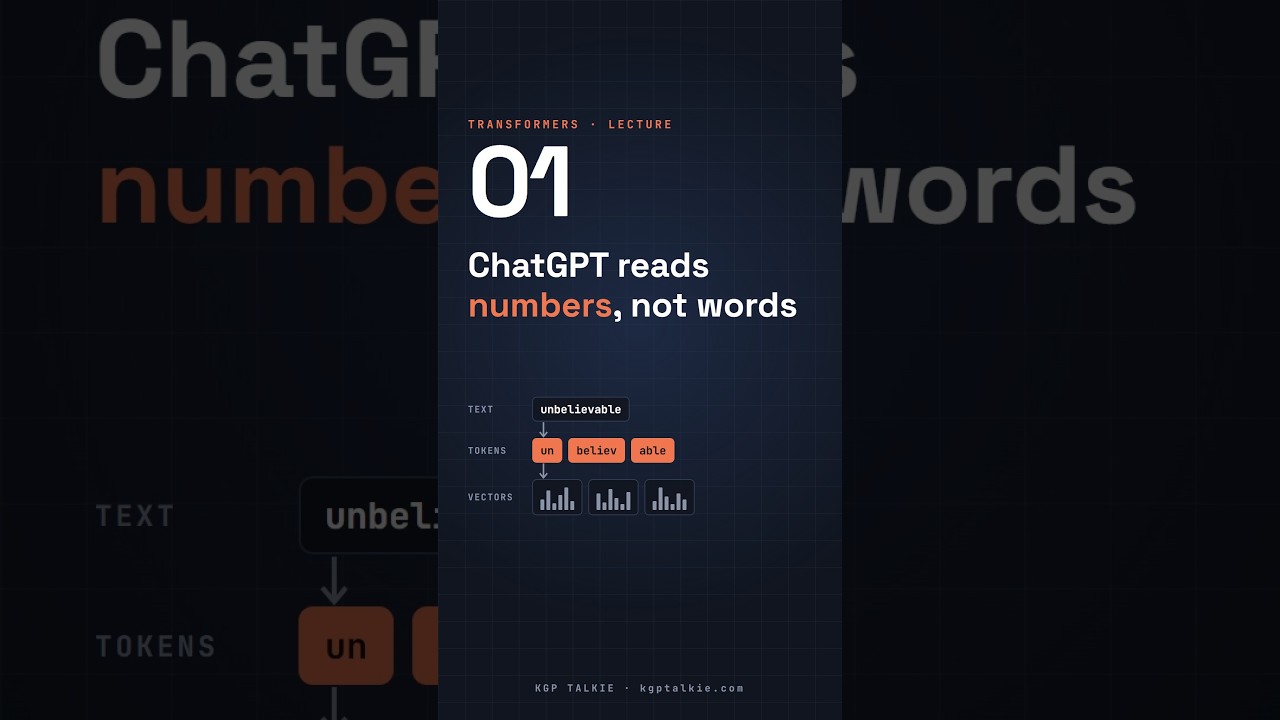
How ChatGPT works: it reads numbers, so let's follow one sentence through a transformer.
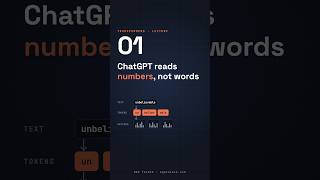
- Tokenization: text splits into tokens, common words stay whole and rare words split ("unbelievable" = un + believ + able), and each token gets a token ID
- Embeddings: each ID becomes a long list of learned numbers, so similar words like king and queen sit close together, like nearby cities on a map
- Attention: in "The trophy did not fit in the suitcase because it was too big", the model weighs the other words and links "it" to the trophy
- Position information is added to every token, so "dog bites man" and "man bites dog" read differently
- Three families: encoders like BERT understand text, decoders like GPT (and ChatGPT) generate one token at a time, encoder-decoders like T5 handle translation and summarization
Full article with code: kgptalkie.com/tutorials/transformers/transformers-and-tokenization
Next lecture: the four ways to split text into tokens. Follow for the full Transformers series.
Go deeper: Fine Tuning LLM with Hugging Face Transformers for NLP (Udemy): kgptalkie.com/udemy-courses
#shorts #ChatGPT #Transformers #LLM #Tokenization #Embeddings #Attention #NLP #GenerativeAI #MachineLearning #AI #KGPTalkie
How ChatGPT works: it reads numbers, so let's follow one sentence through a transformer.
- Tokenization: text splits into tokens, common words stay whole and rare words split ("unbelievable" = un + believ + able), and each token gets a token ID
- Embeddings: each ID becomes a long list of learned numbers, so similar words like king and queen sit close together, like nearby cities on a map
- Attention: in "The trophy did not fit in the suitcase because it was too big", the model weighs the other words and links "it" to the trophy
- Position information is added to every token, so "dog bites man" and "man bites dog" read differently
- Three families: encoders like BERT understand text, decoders like GPT (and ChatGPT) generate one token at a time, encoder-decoders like T5 handle translation and summarization
Full article with code: kgptalkie.com/tutorials/transformers/transformers-and-tokenization
Next lecture: the four ways to split text into tokens. Follow for the full Transformers series.
Go deeper: Fine Tuning LLM with Hugging Face Transformers for NLP (Udemy): kgptalkie.com/udemy-courses
#shorts #ChatGPT #Transformers #LLM #Tokenization #Embeddings #Attention #NLP #GenerativeAI #MachineLearning #AI #KGPTalkie