Uploaded October 2016 | Updated September 2026, 53 minutes ago
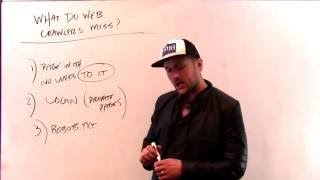
Web crawlers find a lot of the web, but not necessarily everything. Pages get missed for a variety of reasons. Sometimes there are no links to them. Other times accessing them requires permissions that the robot crawler doesn’t have. And well-behaved web crawlers will also ignore pages if told to be the website in the form of a robots.txt file.
Credits: Talking: Geoffrey Challen (Assistant Professor, Computer Science and Engineering, University at Buffalo). Producing: Greg Bunyea (Undergraduate, Computer Science and Engineering, University at Buffalo).
Part of the internet-class.org online internet course. A blue Systems Research Group (https://blue.cse.buffalo.edu) production.
Web crawlers find a lot of the web, but not necessarily everything. Pages get missed for a variety of reasons. Sometimes there are no links to them. Other times accessing them requires permissions that the robot crawler doesn’t have. And well-behaved web crawlers will also ignore pages if told to be the website in the form of a robots.txt file.
Credits: Talking: Geoffrey Challen (Assistant Professor, Computer Science and Engineering, University at Buffalo). Producing: Greg Bunyea (Undergraduate, Computer Science and Engineering, University at Buffalo).
Part of the internet-class.org online internet course. A blue Systems Research Group (https://blue.cse.buffalo.edu) production.