Uploaded August 2026 | Updated November 2026, 2 days ago
This is the Addendum to the and last video of a trilogy of videos titled "The world's smallest transformer model".
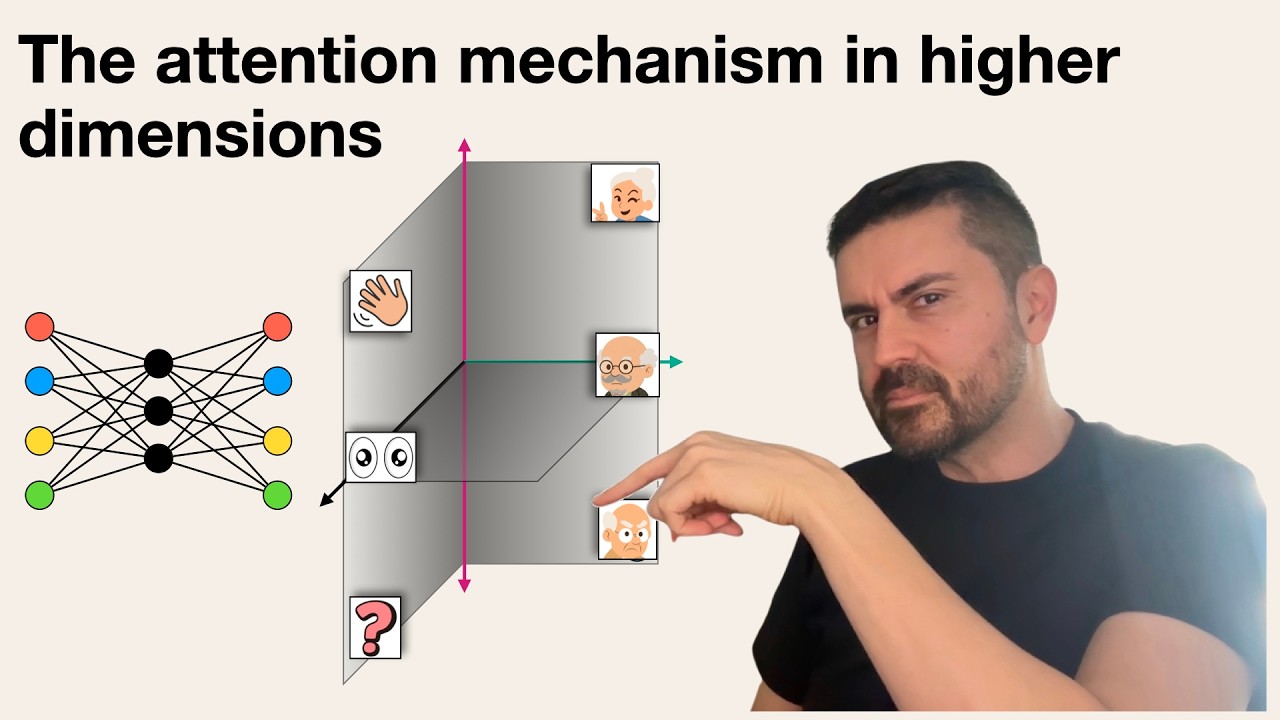
In this video, we work out a calculation that we left in the original video, which is a pair of heads of attention (K and Q matrices) that require a more complex architecture, more specifically, a 4-3-4 architecture which will embed the dataset in a 3-dimensional space instead of 2-dimensions. This extra freedom allows us to build the two new heads of attention.
Video 1: How neural networks bend space youtube.com/watch?v=3THzlSIzfug
Video 2: The world's smallest transformer model youtube.com/watch?v=3ZxbaeqZIHQ
Video 3: The world's smallest attention mechanism youtube.com/watch?v=J4hSc9He614
ADDENDUM: Key and Query Matrices worked out in detail (this one!)
The codelab is here
github.com/luisguiserrano/tiny_llm
Get the second edition of Grokking Machine Learning!
manning.com/books/grokking-machine-learning
Use this code for a 50% discount! Luis50
This is the Addendum to the and last video of a trilogy of videos titled "The world's smallest transformer model".
In this video, we work out a calculation that we left in the original video, which is a pair of heads of attention (K and Q matrices) that require a more complex architecture, more specifically, a 4-3-4 architecture which will embed the dataset in a 3-dimensional space instead of 2-dimensions. This extra freedom allows us to build the two new heads of attention.
Video 1: How neural networks bend space youtube.com/watch?v=3THzlSIzfug
Video 2: The world's smallest transformer model youtube.com/watch?v=3ZxbaeqZIHQ
Video 3: The world's smallest attention mechanism youtube.com/watch?v=J4hSc9He614
ADDENDUM: Key and Query Matrices worked out in detail (this one!)
The codelab is here
github.com/luisguiserrano/tiny_llm
Get the second edition of Grokking Machine Learning!
manning.com/books/grokking-machine-learning
Use this code for a 50% discount! Luis50