Uploaded October 2026 | Updated November 2026, 3 days ago
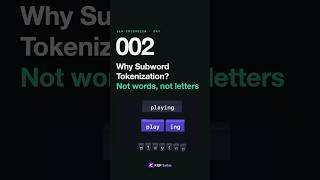
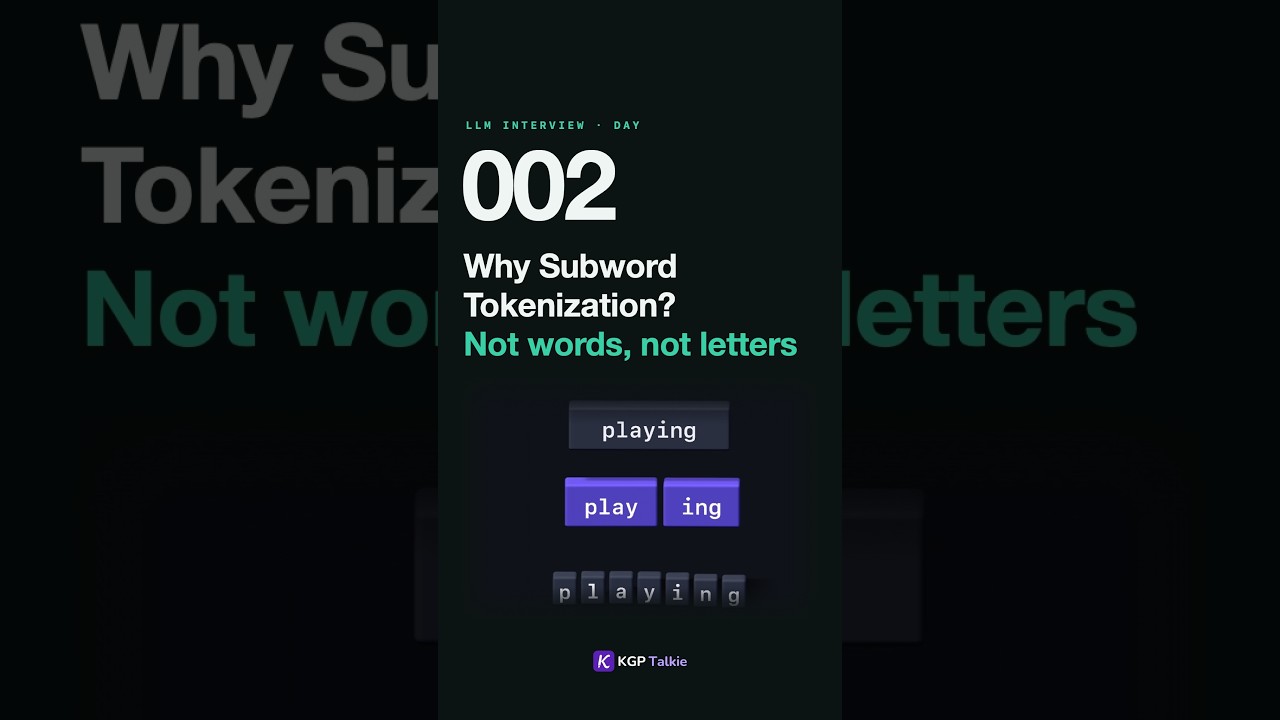
Subword tokenization, an LLM interview question: why do LLMs use subword tokens? Why not whole words, or single letters? Most candidates say "because subwords are more efficient". Not wrong, but not an answer. The interviewer wants the trade-off.
- Whole words: every form needs its own entry (play, plays, played, playing), plus names, typos, hashtags and new slang. The vocabulary explodes into the millions, every entry needs its own row in the embedding table, so the model gets huge. Any word that isn't on the list becomes an unknown token the model can't read
- Single letters: a tiny vocabulary and nothing is ever unknown, but every sentence gets about 4x longer. Attention cost grows with the square of the length, the context window fills 4x faster, writing an answer takes 4x more steps, and the model has to learn spelling before meaning
- Subwords take the middle path: common words stay whole ("the"), rare words split into pieces the model already knows ("unhappiness" becomes un + happi + ness). No unknown words, a fixed vocabulary of roughly 30 thousand to a couple of hundred thousand tokens, short sentences, and pieces like "un" and "ness" are shared by lots of words
- The follow-up: the downside? Letters hide inside tokens. The model sees "strawberry" as two or three chunks, which is why LLMs struggle to count its r's. And languages the tokenizer saw less of, like Hindi, split into many more pieces
One-line answer: words blow up the vocabulary and break on unknown words, letters make sequences far too long, subwords give a fixed vocabulary, no unknown words and short sequences, at the cost of hidden spelling.
Next LLM Interview episode: a bigger vocabulary or a longer context, what's the trade-off? Comment and tell me, which answer would you have given? Follow for the full LLM Interview series.
kgptalkie.com
#shorts #LLM #Tokenizer #Tokenization #SubwordTokens #NLP #MachineLearning #AIInterview #InterviewPrep #GenerativeAI #DeepLearning #KGPTalkie
Subword tokenization, an LLM interview question: why do LLMs use subword tokens? Why not whole words, or single letters? Most candidates say "because subwords are more efficient". Not wrong, but not an answer. The interviewer wants the trade-off.
- Whole words: every form needs its own entry (play, plays, played, playing), plus names, typos, hashtags and new slang. The vocabulary explodes into the millions, every entry needs its own row in the embedding table, so the model gets huge. Any word that isn't on the list becomes an unknown token the model can't read
- Single letters: a tiny vocabulary and nothing is ever unknown, but every sentence gets about 4x longer. Attention cost grows with the square of the length, the context window fills 4x faster, writing an answer takes 4x more steps, and the model has to learn spelling before meaning
- Subwords take the middle path: common words stay whole ("the"), rare words split into pieces the model already knows ("unhappiness" becomes un + happi + ness). No unknown words, a fixed vocabulary of roughly 30 thousand to a couple of hundred thousand tokens, short sentences, and pieces like "un" and "ness" are shared by lots of words
- The follow-up: the downside? Letters hide inside tokens. The model sees "strawberry" as two or three chunks, which is why LLMs struggle to count its r's. And languages the tokenizer saw less of, like Hindi, split into many more pieces
One-line answer: words blow up the vocabulary and break on unknown words, letters make sequences far too long, subwords give a fixed vocabulary, no unknown words and short sequences, at the cost of hidden spelling.
Next LLM Interview episode: a bigger vocabulary or a longer context, what's the trade-off? Comment and tell me, which answer would you have given? Follow for the full LLM Interview series.
kgptalkie.com
#shorts #LLM #Tokenizer #Tokenization #SubwordTokens #NLP #MachineLearning #AIInterview #InterviewPrep #GenerativeAI #DeepLearning #KGPTalkie