Uploaded September 2026 | Updated November 2026, 2 days ago
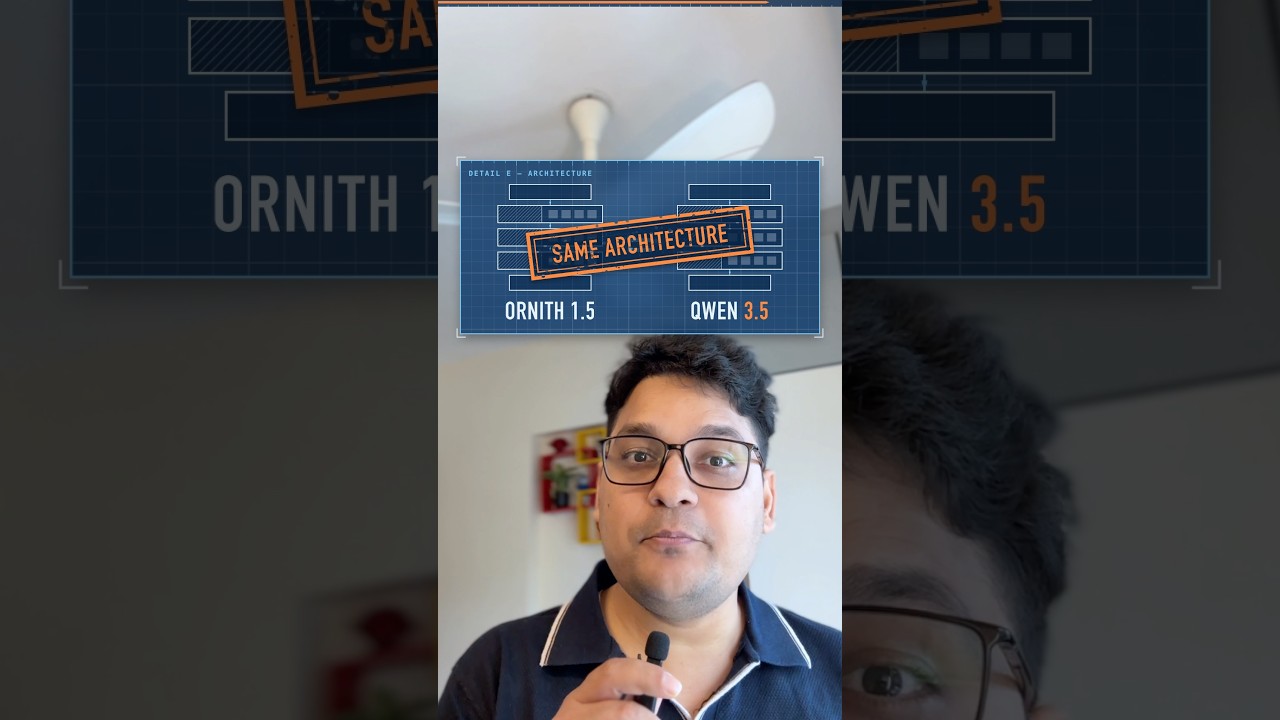
Ornith 1.5 is a brand new model from Ornith AI, but when I opened its GGUF file, it says Qwen. Question is why?
▸ The GGUF header lists each and every tensor inside the model, so you can check everything yourself
▸ Ornith 9B reports its architecture as qwen35, which means Qwen 3.5
▸ Ornith 35B reports qwen35moe, which means Qwen 3.5 MoE
▸ Ornith models have 256 experts in total, and only 8 are active per token
▸ So only a small number of parameters are used per token
If the architecture is the same as Qwen 3.5, where is the improvement coming from? From the post-training, not from the architecture.
Architecture or post-training: which matters more to you? Tell me in the comments 👇
Follow for more AI benchmarks.
#Ornith #Qwen #GGUF #LLM #MixtureOfExperts #AI #Shorts
Full benchmark: kgptalkie.com/tutorials/llm-benchmarking/ornith-1-5-9b-vs-35b-a3b-benchmark
Ornith 1.5 is a brand new model from Ornith AI, but when I opened its GGUF file, it says Qwen. Question is why?
▸ The GGUF header lists each and every tensor inside the model, so you can check everything yourself
▸ Ornith 9B reports its architecture as qwen35, which means Qwen 3.5
▸ Ornith 35B reports qwen35moe, which means Qwen 3.5 MoE
▸ Ornith models have 256 experts in total, and only 8 are active per token
▸ So only a small number of parameters are used per token
If the architecture is the same as Qwen 3.5, where is the improvement coming from? From the post-training, not from the architecture.
Architecture or post-training: which matters more to you? Tell me in the comments 👇
Follow for more AI benchmarks.
#Ornith #Qwen #GGUF #LLM #MixtureOfExperts #AI #Shorts
Full benchmark: kgptalkie.com/tutorials/llm-benchmarking/ornith-1-5-9b-vs-35b-a3b-benchmark