Uploaded November 2026 | Updated November 2026, 3 days ago
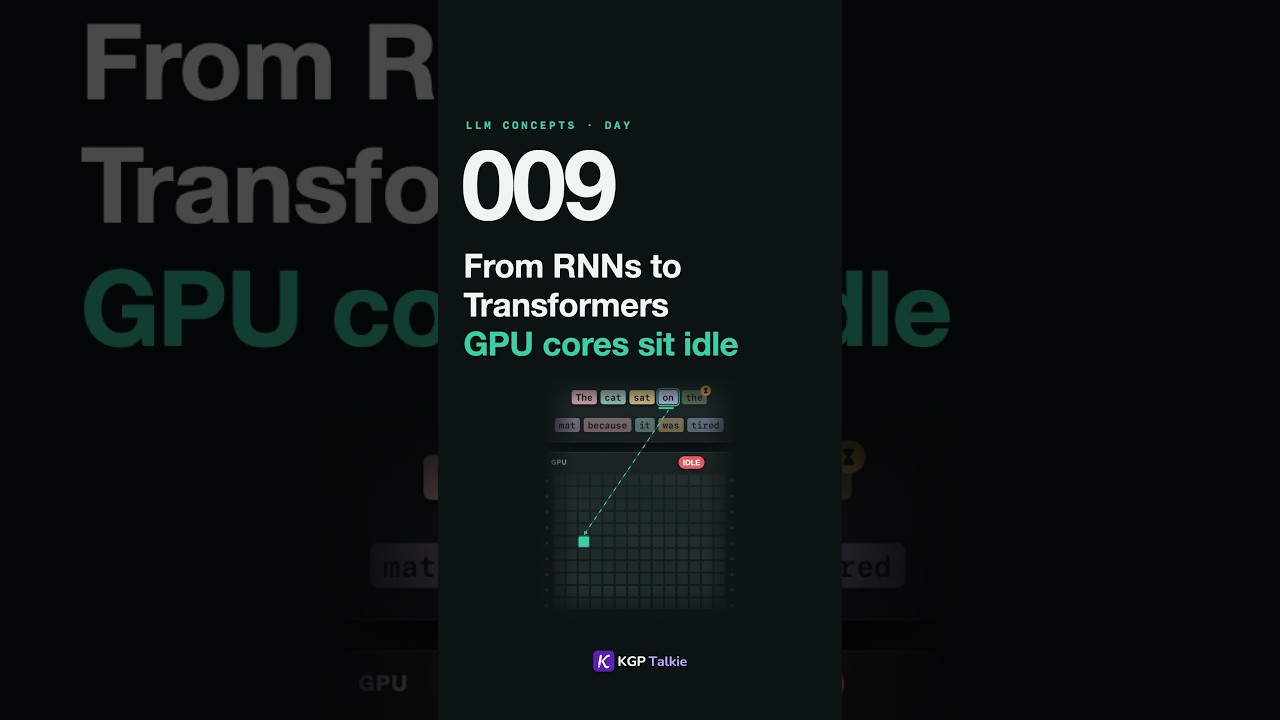
Thousands of GPU cores sit idle, waiting for the previous word to finish. Here is the journey from RNNs to transformers: how language models read text before ChatGPT.
- Before the transformer, the most popular model for text was the RNN, a recurrent neural network. It reads a sentence the way we do: one word at a time, left to right
- Step one, the hidden state: an RNN has one small memory vector. Each new word updates it, and it is carried on to the next word. The gist of the whole sentence lives in that one vector
- Step two, the problem: everything is sequential. To process the tenth word, the ninth has to finish first, so during training thousands of GPU cores sit idle
- Step three, forgetting over long distances: in training, the error signal travels backwards through every step and gets a little smaller at each one. Fifty words back, it's almost gone. That's the vanishing gradient. The LSTM added a forget gate, an input gate and an output gate to decide what to keep and what to forget. It helped a lot, but it still read one word at a time
- Step four, attention: in translation, squeezing a whole sentence into one vector was too much. Around 2014, attention let every output word look back at all the input words and decide which ones to focus on
- Step five, 2017, "Attention Is All You Need": drop the recurrence, keep only attention. Every word looks at every other word directly, in a single step, and training processes the whole sentence at once, in parallel. That's what made training big models possible
- The catch: a transformer still generates one token at a time, the cost of attention grows with the square of the text length, and while an RNN's memory stayed fixed, a transformer has to keep track of every previous token. That's why newer models like Mamba are bringing recurrence back
- Illustrative on screen: the example sentence "The cat sat on the mat because it was tired" and its French translation, the GPU core grid and the IDLE tag, the hidden-state and error-signal bar heights, the attention line weights, the generated answer tokens, the attention grid sizes 4 / 8 / 16, the KV-cache rows (the "KV cache" label names the transformer's memory of previous tokens), the "State-space model" label under Mamba, the comment text "I trained an LSTM" and the LLM Interview card
Next is an LLM Interview reel: why did transformers replace RNNs and LSTMs? Comment and tell me, have you ever trained an LSTM? Follow for the LLM Concepts series.
kgptalkie.com
#shorts #LLM #Transformer #RNN #LSTM #Attention #DeepLearning #GenerativeAI #MachineLearning #AIExplained #LLMConcepts #KGPTalkie
Thousands of GPU cores sit idle, waiting for the previous word to finish. Here is the journey from RNNs to transformers: how language models read text before ChatGPT.
- Before the transformer, the most popular model for text was the RNN, a recurrent neural network. It reads a sentence the way we do: one word at a time, left to right
- Step one, the hidden state: an RNN has one small memory vector. Each new word updates it, and it is carried on to the next word. The gist of the whole sentence lives in that one vector
- Step two, the problem: everything is sequential. To process the tenth word, the ninth has to finish first, so during training thousands of GPU cores sit idle
- Step three, forgetting over long distances: in training, the error signal travels backwards through every step and gets a little smaller at each one. Fifty words back, it's almost gone. That's the vanishing gradient. The LSTM added a forget gate, an input gate and an output gate to decide what to keep and what to forget. It helped a lot, but it still read one word at a time
- Step four, attention: in translation, squeezing a whole sentence into one vector was too much. Around 2014, attention let every output word look back at all the input words and decide which ones to focus on
- Step five, 2017, "Attention Is All You Need": drop the recurrence, keep only attention. Every word looks at every other word directly, in a single step, and training processes the whole sentence at once, in parallel. That's what made training big models possible
- The catch: a transformer still generates one token at a time, the cost of attention grows with the square of the text length, and while an RNN's memory stayed fixed, a transformer has to keep track of every previous token. That's why newer models like Mamba are bringing recurrence back
- Illustrative on screen: the example sentence "The cat sat on the mat because it was tired" and its French translation, the GPU core grid and the IDLE tag, the hidden-state and error-signal bar heights, the attention line weights, the generated answer tokens, the attention grid sizes 4 / 8 / 16, the KV-cache rows (the "KV cache" label names the transformer's memory of previous tokens), the "State-space model" label under Mamba, the comment text "I trained an LSTM" and the LLM Interview card
Next is an LLM Interview reel: why did transformers replace RNNs and LSTMs? Comment and tell me, have you ever trained an LSTM? Follow for the LLM Concepts series.
kgptalkie.com
#shorts #LLM #Transformer #RNN #LSTM #Attention #DeepLearning #GenerativeAI #MachineLearning #AIExplained #LLMConcepts #KGPTalkie