Uploaded November 2026 | Updated November 2026, 3 days ago
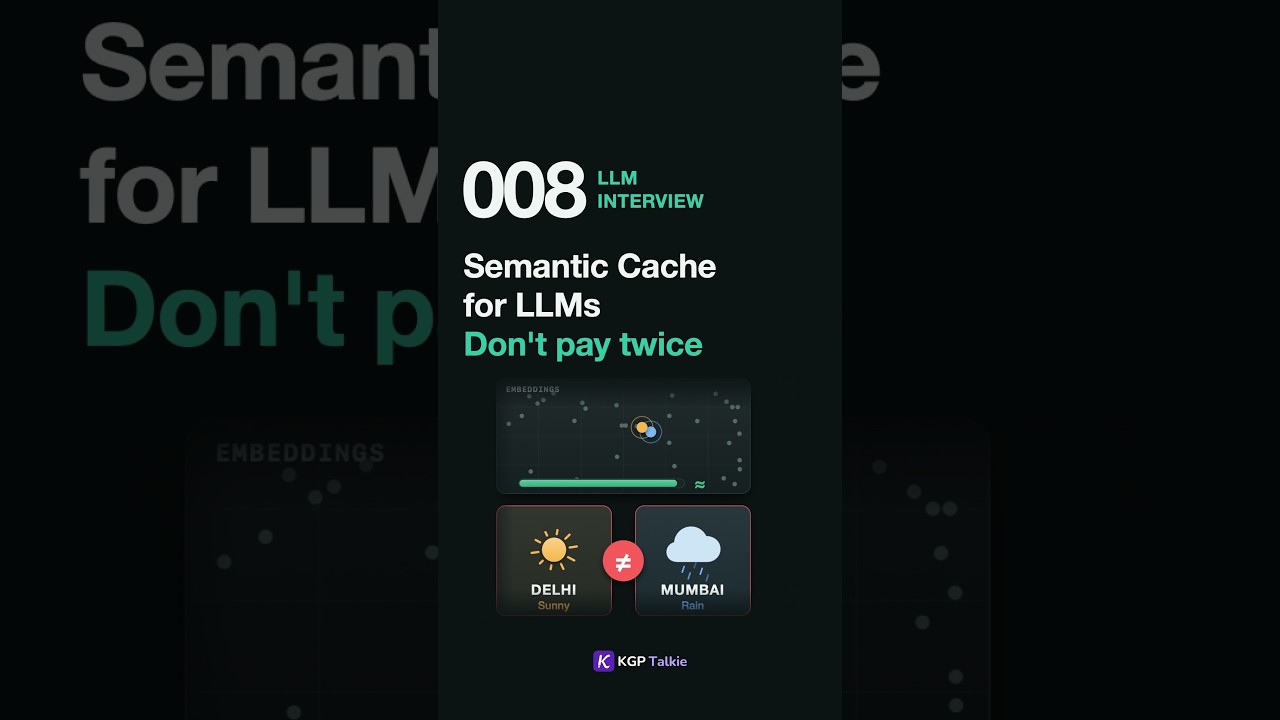
Delhi weather, Mumbai weather. Almost the same embedding, different answers. In an LLM Interview you get exactly this question: "Millions of people ask the same question. Why pay the LLM every time?" Most candidates say "put a Redis cache in front", and the interviewer has already moved on. The real question: what's the cache key, and when is a cached answer the wrong answer?
- Fix 1, two layers: an exact cache up front (hash of the normalized prompt, answer from Redis in a few milliseconds). On a miss, a semantic cache: embed the question, find the nearest neighbour in a vector index, and return the old answer if the similarity is above the threshold. Call the LLM only when both miss
- Fix 2, the key: add the model name, the system prompt's version and settings like temperature. Change the prompt or upgrade the model, bump the version, and old entries stop matching on their own
- Fix 3, what not to cache: answers built on the user's own data ("where's my last order?") are not cached or stay scoped to that user. Fast-changing answers like today's price or a live score get a short TTL
- Fix 4, prompt caching is different: it reuses the processing of the start of the prompt, the model still runs, input just gets cheaper and faster. Use both together
- Follow-up, the threshold: a wrong hit answers a different question. Pick the threshold from labelled question pairs from real traffic where wrong hits are close to zero, add a cheap check that rejects a hit when a number, date or name differs, and keep sampling hits for review
One-line answer: exact first, then semantic, version in the key, rules for personal and fast-changing answers, and a threshold chosen from data.
Next LLM Interview episode: why did transformers replace RNNs and LSTMs? Comment and tell me, what percent of the questions in your app are repeats? Follow for the full LLM Interview series.
kgptalkie.com
#shorts #LLM #LLMInterview #AIInterview #InterviewPrep #SemanticCache #Caching #Embeddings #VectorSearch #SystemDesign #GenAI #KGPTalkie
Delhi weather, Mumbai weather. Almost the same embedding, different answers. In an LLM Interview you get exactly this question: "Millions of people ask the same question. Why pay the LLM every time?" Most candidates say "put a Redis cache in front", and the interviewer has already moved on. The real question: what's the cache key, and when is a cached answer the wrong answer?
- Fix 1, two layers: an exact cache up front (hash of the normalized prompt, answer from Redis in a few milliseconds). On a miss, a semantic cache: embed the question, find the nearest neighbour in a vector index, and return the old answer if the similarity is above the threshold. Call the LLM only when both miss
- Fix 2, the key: add the model name, the system prompt's version and settings like temperature. Change the prompt or upgrade the model, bump the version, and old entries stop matching on their own
- Fix 3, what not to cache: answers built on the user's own data ("where's my last order?") are not cached or stay scoped to that user. Fast-changing answers like today's price or a live score get a short TTL
- Fix 4, prompt caching is different: it reuses the processing of the start of the prompt, the model still runs, input just gets cheaper and faster. Use both together
- Follow-up, the threshold: a wrong hit answers a different question. Pick the threshold from labelled question pairs from real traffic where wrong hits are close to zero, add a cheap check that rejects a hit when a number, date or name differs, and keep sampling hits for review
One-line answer: exact first, then semantic, version in the key, rules for personal and fast-changing answers, and a threshold chosen from data.
Next LLM Interview episode: why did transformers replace RNNs and LSTMs? Comment and tell me, what percent of the questions in your app are repeats? Follow for the full LLM Interview series.
kgptalkie.com
#shorts #LLM #LLMInterview #AIInterview #InterviewPrep #SemanticCache #Caching #Embeddings #VectorSearch #SystemDesign #GenAI #KGPTalkie