Uploaded May 2025 | Updated September 2026, 1 hour ago
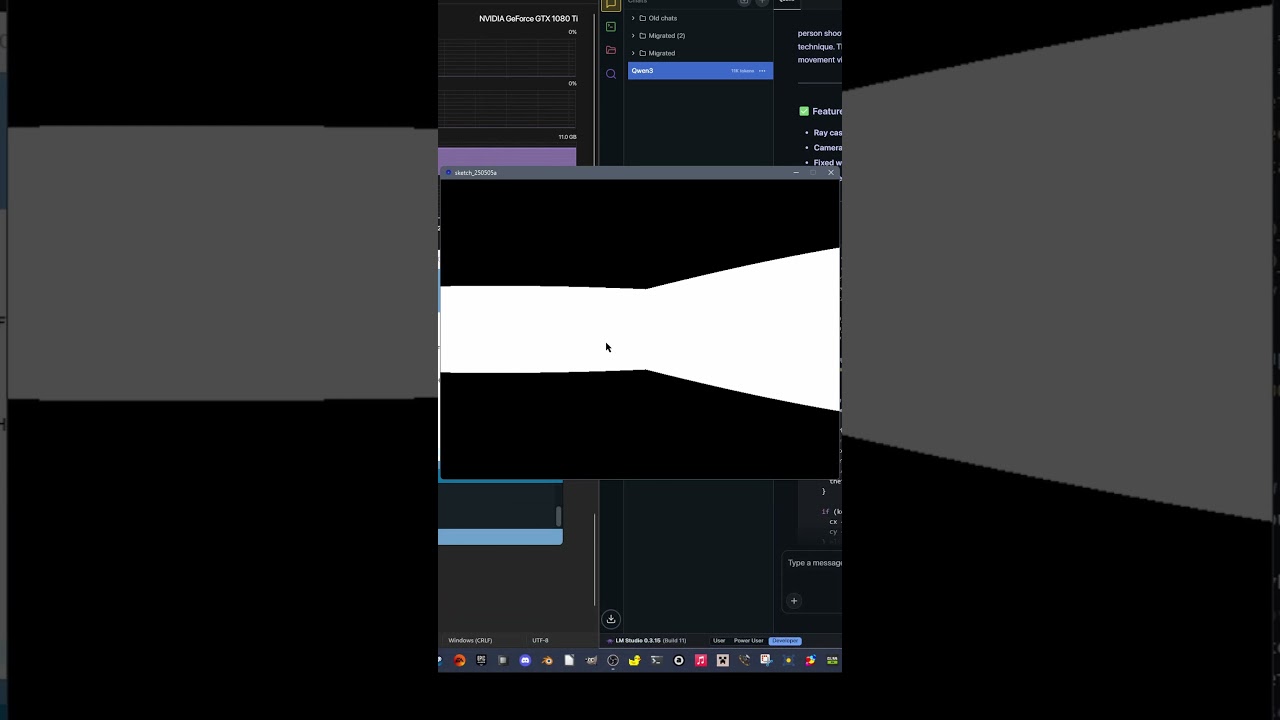
Testing Qwen 3 models out, in this case the 8 billion parameter version, which blew me away with the fact it was able to write a program from scratch that successfully implements ray casting! I've seen larger models, (like 20 billion parameters and up) get this right. Or the Qwen 3 30B-A3B model, which is an Mixture of Experts model (MOE) that only has 3 billion active parameters (out of 30 billion total), and it is able to do this reliably too. Very impressive! Gemma 3 12b fails every time. Gemma 3 27b is able to but not every time. It used to take models like Llama 3 70b to get results like this.
I also tested GPT 4.1 Nano out with this ray casting test and suprisingly it was able to do it no problem first try. And it looks much better than Qwen's version too. Very impressive!
Gemini 1.5 Pro (yes the old one) fails to do this reliably. Gemini 2.5 Flash can no problem.
#gtx1080ti #opensourceai #qwen3
Testing Qwen 3 models out, in this case the 8 billion parameter version, which blew me away with the fact it was able to write a program from scratch that successfully implements ray casting! I've seen larger models, (like 20 billion parameters and up) get this right. Or the Qwen 3 30B-A3B model, which is an Mixture of Experts model (MOE) that only has 3 billion active parameters (out of 30 billion total), and it is able to do this reliably too. Very impressive! Gemma 3 12b fails every time. Gemma 3 27b is able to but not every time. It used to take models like Llama 3 70b to get results like this.
I also tested GPT 4.1 Nano out with this ray casting test and suprisingly it was able to do it no problem first try. And it looks much better than Qwen's version too. Very impressive!
Gemini 1.5 Pro (yes the old one) fails to do this reliably. Gemini 2.5 Flash can no problem.
#gtx1080ti #opensourceai #qwen3