Uploaded April 2026 | Updated November 2026, 5 days ago
Machine Learning for Health (ML4H) Seminar Series
April 1, 2026
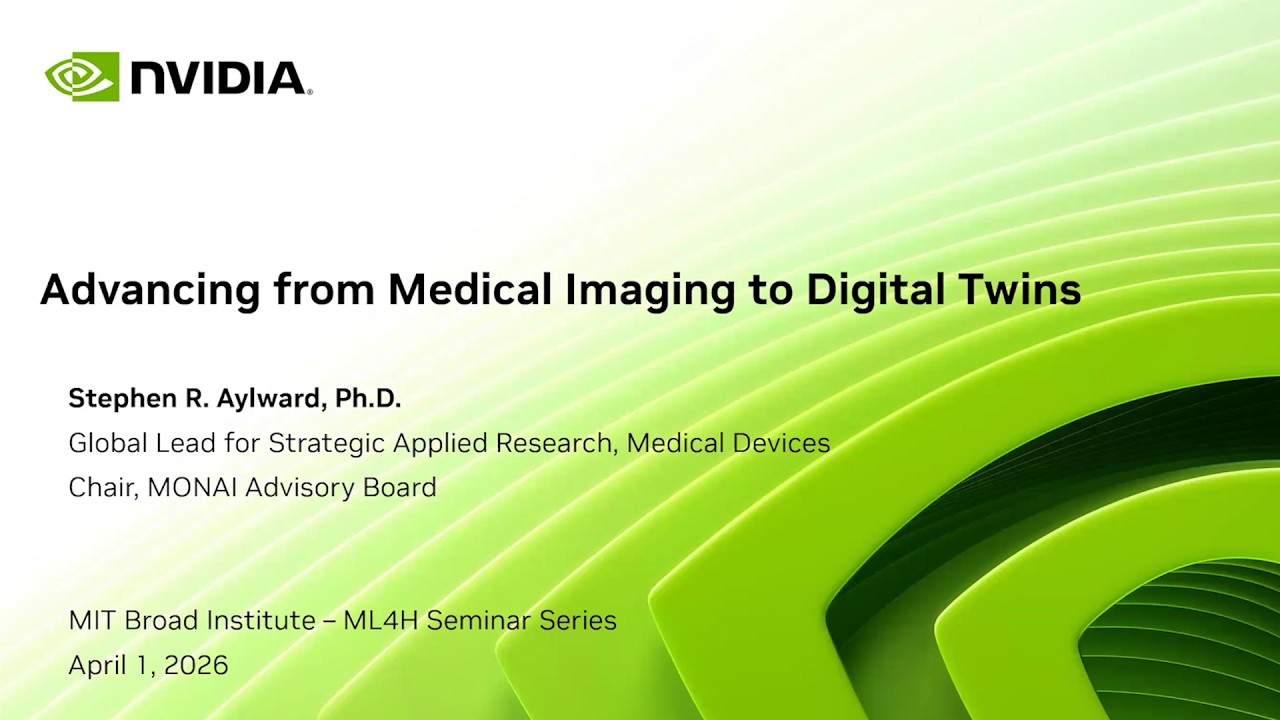
Talk Title: Advancing from Medical Imaging to Digital Twins
Speaker:
Stephen Aylward
NVIDIA
Abstract:
Medical imaging AI has reached an inflection point. In the first part of this talk, I will reflect on the community practices, technical choices, and open-science principles that helped MONAI become a widely adopted platform for medical imaging AI. With more than 8 million downloads, over 4,000 publication acknowledgements, and contributions from more than 240 developers worldwide, MONAI has supported a broad range of research efforts and regulatory-approved products.
The second part of the talk will ask what comes next. As healthcare moves beyond image interpretation toward systems that can sense, predict, and guide intervention, AI must evolve from perception to action. NVIDIA has described this broader direction as Physical AI: systems that perceive and interact with the world around them. I will argue that, in healthcare, this paradigm becomes even more powerful when coupled with simulation through Digital Twins. Together, Physical AI and Digital Twins enable a “sense, simulate, decide, act” framework for optimizing long-term patient outcomes and for shaping a new generation of intelligent healthcare systems.
I will conclude by highlighting the open-source platforms and collaborative ecosystem now emerging to support this future, along with early signals of technical and translational success.
Bio:
Stephen Aylward is the Global Lead for Strategic Applied Research for Medical Devices at NVIDIA. His collaborations focus developing open-source software and innovative algorithms that leverage accelerated computing to advance medical device R&D in academia and industry. His current research focuses on AI-enabled digital twin technologies for personalized surgical planning. Dr. Aylward’s background includes leading NIH, DARPA, and DoD-funded medical research for over 25 years as well as leading the development of numerous open-source platforms, including the Insight Toolkit (ITK), 3D Slicer, and MONAI. He is also a MICCAI Fellow, an adjunct professor in computer science at the University of North Carolina at Chapel Hill (UNC), chair of the MONAI advisory board, and an advisory board member for the Vanderbilt Institute for Surgery and Engineering and for Johns Hopkins Laboratory for Computational Sensing and Robotics. Previously, he was senior director of Strategic Initiatives at Kitware and a tenured professor in radiology at UNC.
For more information, visit: broadinstitute.org/ml4h
Copyright Broad Institute, 2026. All rights reserved.
Machine Learning for Health (ML4H) Seminar Series
April 1, 2026
Talk Title: Advancing from Medical Imaging to Digital Twins
Speaker:
Stephen Aylward
NVIDIA
Abstract:
Medical imaging AI has reached an inflection point. In the first part of this talk, I will reflect on the community practices, technical choices, and open-science principles that helped MONAI become a widely adopted platform for medical imaging AI. With more than 8 million downloads, over 4,000 publication acknowledgements, and contributions from more than 240 developers worldwide, MONAI has supported a broad range of research efforts and regulatory-approved products.
The second part of the talk will ask what comes next. As healthcare moves beyond image interpretation toward systems that can sense, predict, and guide intervention, AI must evolve from perception to action. NVIDIA has described this broader direction as Physical AI: systems that perceive and interact with the world around them. I will argue that, in healthcare, this paradigm becomes even more powerful when coupled with simulation through Digital Twins. Together, Physical AI and Digital Twins enable a “sense, simulate, decide, act” framework for optimizing long-term patient outcomes and for shaping a new generation of intelligent healthcare systems.
I will conclude by highlighting the open-source platforms and collaborative ecosystem now emerging to support this future, along with early signals of technical and translational success.
Bio:
Stephen Aylward is the Global Lead for Strategic Applied Research for Medical Devices at NVIDIA. His collaborations focus developing open-source software and innovative algorithms that leverage accelerated computing to advance medical device R&D in academia and industry. His current research focuses on AI-enabled digital twin technologies for personalized surgical planning. Dr. Aylward’s background includes leading NIH, DARPA, and DoD-funded medical research for over 25 years as well as leading the development of numerous open-source platforms, including the Insight Toolkit (ITK), 3D Slicer, and MONAI. He is also a MICCAI Fellow, an adjunct professor in computer science at the University of North Carolina at Chapel Hill (UNC), chair of the MONAI advisory board, and an advisory board member for the Vanderbilt Institute for Surgery and Engineering and for Johns Hopkins Laboratory for Computational Sensing and Robotics. Previously, he was senior director of Strategic Initiatives at Kitware and a tenured professor in radiology at UNC.
For more information, visit: broadinstitute.org/ml4h
Copyright Broad Institute, 2026. All rights reserved.