Uploaded May 2026 | Updated September 2026, 2 weeks ago
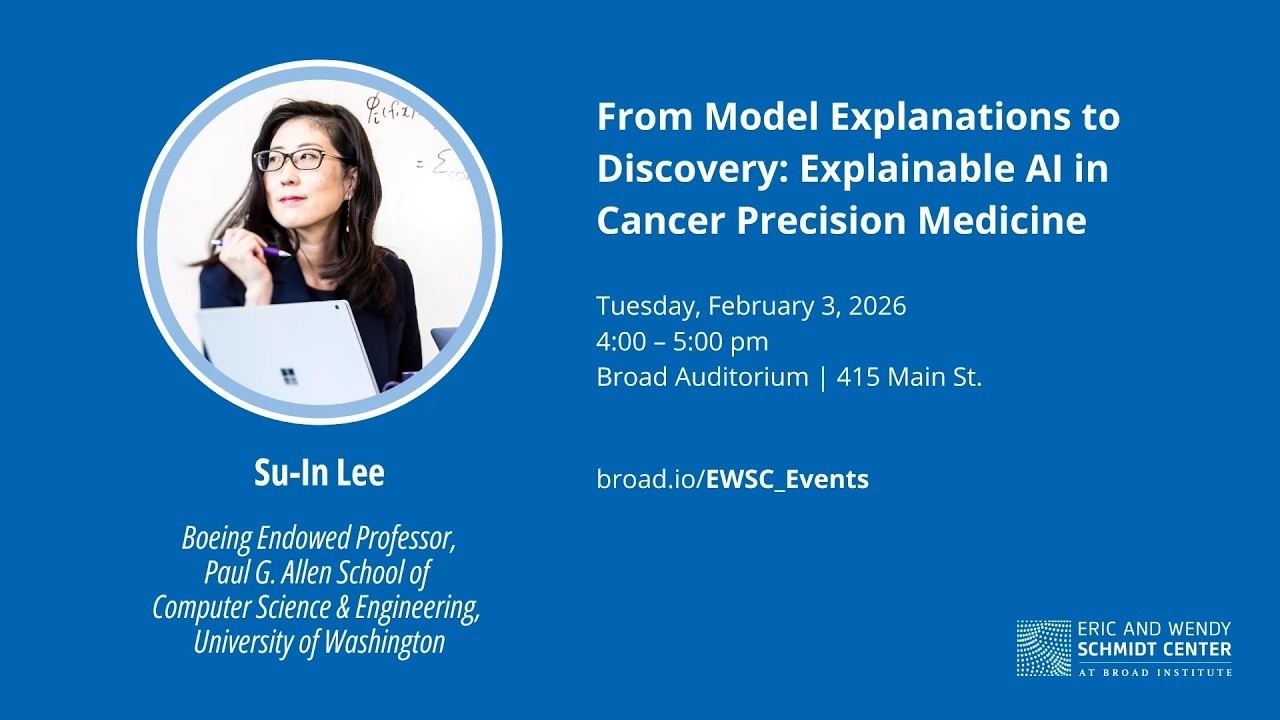
EWSC - MIT EECS Colloquium
February 3, 2026
Broad Institute of MIT and Harvard
Su-In Lee
Boeing Endowed Professor, Paul G. Allen School of Computer Science & Engineering, University of Washington
Abstract:
Explainable AI (XAI) has made significant strides in recent years, offering valuable theories and techniques to interpret complex machine learning models. However, these methods often struggle when applied to interpreting complex datasets for scientific discovery, particularly those involving high-dimensional omics data such as gene expression profiles. These datasets, crucial for understanding biological systems, require novel approaches to fully unlock the potential of XAI. In this talk, I will delve into the practical challenges of applying XAI to gene expression data, showcasing case studies that underscore its potential and limitations. I will present innovative strategies for adapting XAI techniques to accelerate data-driven discoveries in cancer pharmacology and cancer systems biology. The discussion will illuminate how addressing these challenges can lead to profound biological insights and impactful clinical implications. By bridging the gap between advanced XAI principles and techniques and the demands of real-world biomedical datasets, this talk aims to inspire the development of more robust methodologies at the intersection of AI and biomedicine, paving the way for a new era of innovation in biomedical research.
Biography:
Professor Su-In Lee is the Boeing Endowed Professor of Computer Science at the University of Washington (UW). She earned her Ph.D. from Stanford University in 2009 under Professor Daphne Koller and joined UW in 2010 after serving as a Visiting Assistant Professor at Carnegie Mellon University. She is renowned for her groundbreaking research at the intersection of AI, biology, and medicine, and widely recognized as a pioneer in explainable AI (XAI). Her seminal contributions include the SHAP framework and its subsequent algorithms and principles, which have fundamentally transformed the interpretation of machine learning models across disciplines. She has been honored with major awards, including the Samsung Ho-Am Prize in Engineering (the “Korean Nobel Prize,” as its first woman recipient in 34 years), the ISCB Innovator Award, and the NSF CAREER Award. She is an American Cancer Society Research Scholar, an AIMBE Fellow, and an ISCB Distinguished Fellow. Her recent work advances fundamental principles of XAI and applies them to biomedicine—from uncovering molecular drivers of disease to auditing clinical AI systems—fundamentally reshaping how AI is integrated into biomedical research and healthcare. This integration has enabled novel discoveries and produced numerous awards and highly cited publications spanning AI, molecular biology, and clinical medicine.
For more information, visit: broadinstitute.org
Copyright Broad Institute, 2026. All rights reserved.
EWSC - MIT EECS Colloquium
February 3, 2026
Broad Institute of MIT and Harvard
Su-In Lee
Boeing Endowed Professor, Paul G. Allen School of Computer Science & Engineering, University of Washington
Abstract:
Explainable AI (XAI) has made significant strides in recent years, offering valuable theories and techniques to interpret complex machine learning models. However, these methods often struggle when applied to interpreting complex datasets for scientific discovery, particularly those involving high-dimensional omics data such as gene expression profiles. These datasets, crucial for understanding biological systems, require novel approaches to fully unlock the potential of XAI. In this talk, I will delve into the practical challenges of applying XAI to gene expression data, showcasing case studies that underscore its potential and limitations. I will present innovative strategies for adapting XAI techniques to accelerate data-driven discoveries in cancer pharmacology and cancer systems biology. The discussion will illuminate how addressing these challenges can lead to profound biological insights and impactful clinical implications. By bridging the gap between advanced XAI principles and techniques and the demands of real-world biomedical datasets, this talk aims to inspire the development of more robust methodologies at the intersection of AI and biomedicine, paving the way for a new era of innovation in biomedical research.
Biography:
Professor Su-In Lee is the Boeing Endowed Professor of Computer Science at the University of Washington (UW). She earned her Ph.D. from Stanford University in 2009 under Professor Daphne Koller and joined UW in 2010 after serving as a Visiting Assistant Professor at Carnegie Mellon University. She is renowned for her groundbreaking research at the intersection of AI, biology, and medicine, and widely recognized as a pioneer in explainable AI (XAI). Her seminal contributions include the SHAP framework and its subsequent algorithms and principles, which have fundamentally transformed the interpretation of machine learning models across disciplines. She has been honored with major awards, including the Samsung Ho-Am Prize in Engineering (the “Korean Nobel Prize,” as its first woman recipient in 34 years), the ISCB Innovator Award, and the NSF CAREER Award. She is an American Cancer Society Research Scholar, an AIMBE Fellow, and an ISCB Distinguished Fellow. Her recent work advances fundamental principles of XAI and applies them to biomedicine—from uncovering molecular drivers of disease to auditing clinical AI systems—fundamentally reshaping how AI is integrated into biomedical research and healthcare. This integration has enabled novel discoveries and produced numerous awards and highly cited publications spanning AI, molecular biology, and clinical medicine.
For more information, visit: broadinstitute.org
Copyright Broad Institute, 2026. All rights reserved.