Uploaded January 2026 | Updated November 2026, 1 hour ago
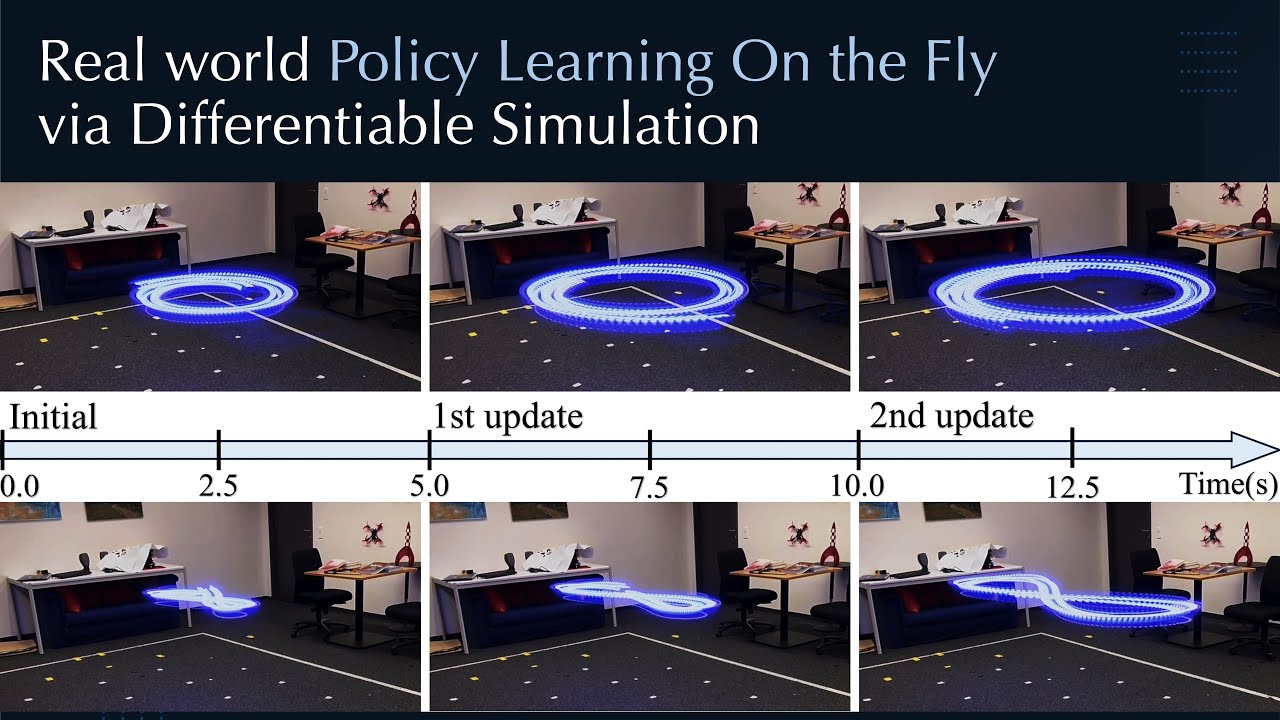
Learning control policies in simulation enables rapid, safe, and cost-effective development of advanced robotic capabilities. However, transferring these policies to the real world remains difficult due to the sim-to-real gap, where unmodeled dynamics and environmental disturbances can degrade policy performance. Existing approaches, such as domain randomization and Real2Sim2Real pipelines, can improve policy robustness, but either struggle under out-of-distribution conditions or require costly offline retraining. In this work, we approach these problems from a different perspective. Instead of relying on diverse training conditions before deployment, we focus on rapidly adapting the learned policy in the real world in an online fashion. To achieve this, we propose a novel online adaptive learning framework that unifies residual dynamics learning with real-time policy adaptation inside a differentiable simulation. Starting from a simple dynamics model, our framework refines the model continuously with real-world data to capture unmodeled effects and disturbances such as payload changes and wind. The refined dynamics model is embedded in a differentiable simulation framework, enabling gradient backpropagation through the dynamics and thus rapid, sample-efficient policy updates beyond the reach of classical RL methods like PPO. All components of our system are designed for rapid adaptation, enabling the policy to adjust to unseen disturbances within 5 seconds of training. We validate the approach on agile quadrotor control under various disturbances in both simulation and the real world. Our framework reduces hovering error by up to 81% compared to L1-MPC and 55% compared to DATT, while also demonstrating robustness in vision-based control without explicit state estimation.
Reference:
J. Pan*, J. Xing*, R. Reiter, Y. Zhai, E. Aljalbout, and D. Scaramuzza,
"Learning on the Fly: Rapid Policy Adaptation via Differentiable Simulation."
IEEE Robotics and Automation Letters RA-L
PDF: https://rpg.ifi.uzh.ch/docs/RAL26_Pan.pdf
Project page: https://rpg.ifi.uzh.ch/lotf/
Code: github.com/uzh-rpg/learning_on_the_fly
More info on our research in Drone Racing:
https://rpg.ifi.uzh.ch/research_drone_racing.html
More info on our research in Agile Drone Flight:
https://rpg.ifi.uzh.ch/aggressive_flight.html
More info on our research on Machine Learning:
https://rpg.ifi.uzh.ch/research_learning.html
Affiliations:
J. Pan, J. Xing, R. Reiter, Y. Zhai, E. Aljalbout, and D. Scaramuzza are with the Robotics and Perception Group, Dep. of Informatics, University of Zurich, https://rpg.ifi.uzh.ch/
Learning control policies in simulation enables rapid, safe, and cost-effective development of advanced robotic capabilities. However, transferring these policies to the real world remains difficult due to the sim-to-real gap, where unmodeled dynamics and environmental disturbances can degrade policy performance. Existing approaches, such as domain randomization and Real2Sim2Real pipelines, can improve policy robustness, but either struggle under out-of-distribution conditions or require costly offline retraining. In this work, we approach these problems from a different perspective. Instead of relying on diverse training conditions before deployment, we focus on rapidly adapting the learned policy in the real world in an online fashion. To achieve this, we propose a novel online adaptive learning framework that unifies residual dynamics learning with real-time policy adaptation inside a differentiable simulation. Starting from a simple dynamics model, our framework refines the model continuously with real-world data to capture unmodeled effects and disturbances such as payload changes and wind. The refined dynamics model is embedded in a differentiable simulation framework, enabling gradient backpropagation through the dynamics and thus rapid, sample-efficient policy updates beyond the reach of classical RL methods like PPO. All components of our system are designed for rapid adaptation, enabling the policy to adjust to unseen disturbances within 5 seconds of training. We validate the approach on agile quadrotor control under various disturbances in both simulation and the real world. Our framework reduces hovering error by up to 81% compared to L1-MPC and 55% compared to DATT, while also demonstrating robustness in vision-based control without explicit state estimation.
Reference:
J. Pan*, J. Xing*, R. Reiter, Y. Zhai, E. Aljalbout, and D. Scaramuzza,
"Learning on the Fly: Rapid Policy Adaptation via Differentiable Simulation."
IEEE Robotics and Automation Letters RA-L
PDF: https://rpg.ifi.uzh.ch/docs/RAL26_Pan.pdf
Project page: https://rpg.ifi.uzh.ch/lotf/
Code: github.com/uzh-rpg/learning_on_the_fly
More info on our research in Drone Racing:
https://rpg.ifi.uzh.ch/research_drone_racing.html
More info on our research in Agile Drone Flight:
https://rpg.ifi.uzh.ch/aggressive_flight.html
More info on our research on Machine Learning:
https://rpg.ifi.uzh.ch/research_learning.html
Affiliations:
J. Pan, J. Xing, R. Reiter, Y. Zhai, E. Aljalbout, and D. Scaramuzza are with the Robotics and Perception Group, Dep. of Informatics, University of Zurich, https://rpg.ifi.uzh.ch/