Uploaded August 2026 | Updated September 2026, 2 weeks ago
🔊 Recorded at PyCon DE & PyData 2026, 14.04.2026
2026.pycon.de/talks/ZYUJH3
🎓 Watch Mirano Tuk and Filip Bacic reveal the architectural trade-offs and practical Kafka patterns used to transform 800 billion noisy records into a reliable, real-time searchable dataset.
Speakers:
Mirano Tuk, Filip Bacic
Description:
Searching through a threat repository containing one trillion records requires a high-throughput pipeline capable of aggregating data from hundreds of microservices. The primary challenge involves handling a flood of partial updates and duplicate file hashes, which can cause significant latency and system instability in search platforms like Apache Solr. An initial architecture using ClickHouse for daily aggregation resulted in a 36-hour data delay, which was unacceptable for users requiring real-time insights.
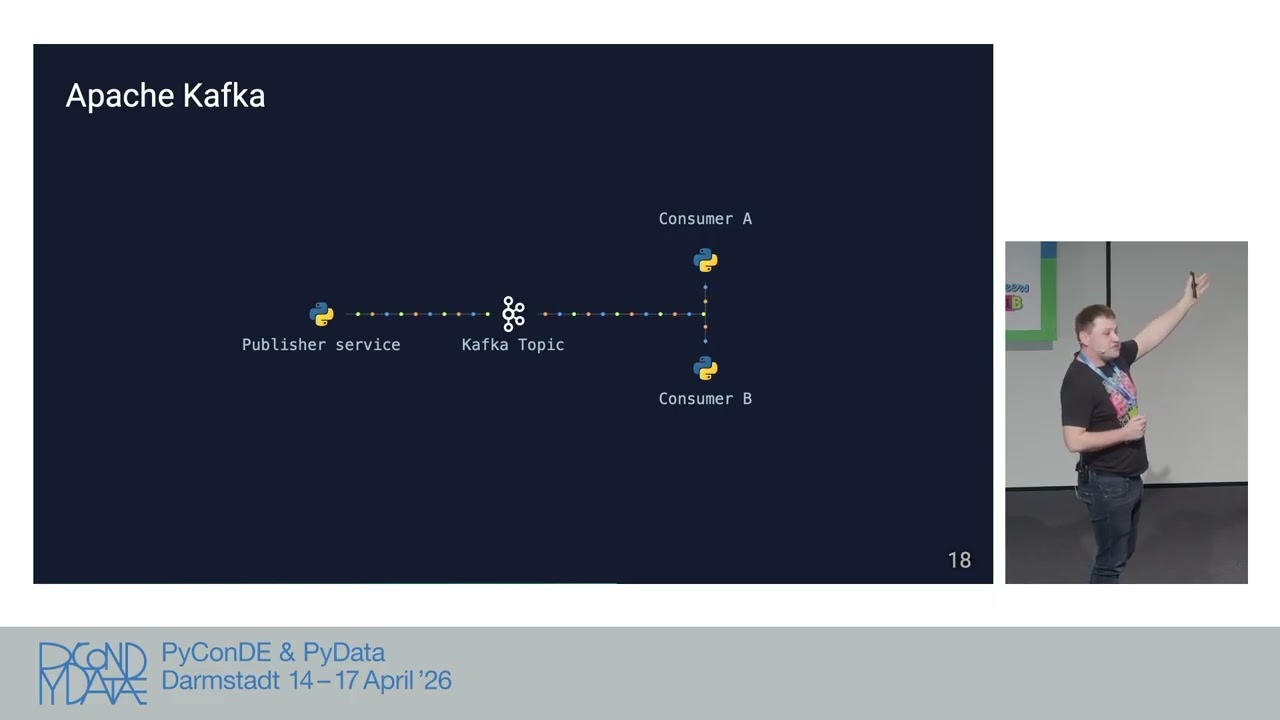
The current solution utilizes ScyllaDB as a high-performance key-value store to maintain the source of truth, where records are stored using a primary key composed of the file hash and feature type. When updates occur, file hashes are published to Kafka topics. A Python-based consumer service fetches the complete data set for each hash from ScyllaDB to build a comprehensive document for Solr. To prevent Solr from being overwhelmed by redundant updates, a custom deduplication buffer was implemented using a Python dictionary to track file hashes across batches. This buffer employs a Time-to-Live (TTL) mechanism and an eviction callback; data is only processed and sent to Solr when a hash is evicted from the buffer, ensuring that only the final state of a file is indexed.
To maintain system stability, the service limits the number of messages processed per iteration to prevent Kafka health-check timeouts during backlog clearing. Additionally, a secondary deduplication layer manages Solr commits and re-indexing across daily collections to avoid heap exhaustion and cluster failure. This architecture reduced update latency from 36 hours to under five minutes and decreased the ingestion volume from 100,000 messages per second to fewer than 2,000.
⭐️ About PyCon DE:
PyCon DE is the leading conference on open-source Python applications in AI and data science. It brings together industry professionals, researchers, AI and data science practitioners, and software engineering communities, providing a unique platform for collaboration, knowledge sharing, and innovation.
The PyCon DE & PyData 2026 conference delivered an exceptional experience, fostering stronger connections within the Python community while showcasing the latest advancements in artificial intelligence and data science. Attendees enjoyed a diverse and engaging program of talks, workshops, and networking opportunities, further establishing the conference as a premier event for Python, AI, and data science enthusiasts across Germany.
PyCon DE 2027 will take place in Heidelberg from 19 to 23 April 2027.
Follow us:
• Newsletter: 2027.pycon.de/newsletter
• LinkedIn: linkedin.com/company/pyconde
• X: x.com/pyconde
Links:
• Conference website: pycon.de
• Other sessions: 2026.pycon.de/talks
The conference was organized by
• Python Softwareverband e.V.: pysv.org
• Pioneers Hub gemeinnützige GmbH: pioneershub.org
in collaboration with NumFOCUS Inc.: numfocus.org
If you enjoyed this session, please like, and subscribe to our channel for more insightful talks and discussions.
Share this video with your network to spread the knowledge!
Hashtags:
#Python #PyConDE #PyData #OpenSource #AI #DataScience #MachineLearning #SoftwareEngineering #LLMs #Community #Sovereignty
Acknowledgements:
Special thanks to all the volunteers and sponsors who made this event possible.
About:
Python Softwareverband e.V.:
PySV is a non-profit that promotes the use and development of Python in Germany through events, education, and advocacy, fostering an open Python community.
Pioneers Hub gemeinnützige GmbH:
is a non-profit fostering innovation in AI and tech by connecting experts and promoting knowledge exchange through events and collaborative initiatives.
NumFOCUS Inc.
supports open-source scientific computing by providing financial and logistical support to key projects like NumPy and Jupyter, promoting sustainable development and collaboration.
pydata.org
PyData is an educational program of NumFOCUS, a 501(c)3 non-profit organization in the United States. PyData provides a forum for the international community of users and developers of data analysis tools to share ideas and learn from each other. The global PyData network promotes discussion of best practices, new approaches, and emerging technologies for data management, processing, analytics, and visualization. PyData communities approach data science using many languages, including (but not limited to) Python, Julia, and R.
🔊 Recorded at PyCon DE & PyData 2026, 14.04.2026
2026.pycon.de/talks/ZYUJH3
🎓 Watch Mirano Tuk and Filip Bacic reveal the architectural trade-offs and practical Kafka patterns used to transform 800 billion noisy records into a reliable, real-time searchable dataset.
Speakers:
Mirano Tuk, Filip Bacic
Description:
Searching through a threat repository containing one trillion records requires a high-throughput pipeline capable of aggregating data from hundreds of microservices. The primary challenge involves handling a flood of partial updates and duplicate file hashes, which can cause significant latency and system instability in search platforms like Apache Solr. An initial architecture using ClickHouse for daily aggregation resulted in a 36-hour data delay, which was unacceptable for users requiring real-time insights.
The current solution utilizes ScyllaDB as a high-performance key-value store to maintain the source of truth, where records are stored using a primary key composed of the file hash and feature type. When updates occur, file hashes are published to Kafka topics. A Python-based consumer service fetches the complete data set for each hash from ScyllaDB to build a comprehensive document for Solr. To prevent Solr from being overwhelmed by redundant updates, a custom deduplication buffer was implemented using a Python dictionary to track file hashes across batches. This buffer employs a Time-to-Live (TTL) mechanism and an eviction callback; data is only processed and sent to Solr when a hash is evicted from the buffer, ensuring that only the final state of a file is indexed.
To maintain system stability, the service limits the number of messages processed per iteration to prevent Kafka health-check timeouts during backlog clearing. Additionally, a secondary deduplication layer manages Solr commits and re-indexing across daily collections to avoid heap exhaustion and cluster failure. This architecture reduced update latency from 36 hours to under five minutes and decreased the ingestion volume from 100,000 messages per second to fewer than 2,000.
⭐️ About PyCon DE:
PyCon DE is the leading conference on open-source Python applications in AI and data science. It brings together industry professionals, researchers, AI and data science practitioners, and software engineering communities, providing a unique platform for collaboration, knowledge sharing, and innovation.
The PyCon DE & PyData 2026 conference delivered an exceptional experience, fostering stronger connections within the Python community while showcasing the latest advancements in artificial intelligence and data science. Attendees enjoyed a diverse and engaging program of talks, workshops, and networking opportunities, further establishing the conference as a premier event for Python, AI, and data science enthusiasts across Germany.
PyCon DE 2027 will take place in Heidelberg from 19 to 23 April 2027.
Follow us:
• Newsletter: 2027.pycon.de/newsletter
• LinkedIn: linkedin.com/company/pyconde
• X: x.com/pyconde
Links:
• Conference website: pycon.de
• Other sessions: 2026.pycon.de/talks
The conference was organized by
• Python Softwareverband e.V.: pysv.org
• Pioneers Hub gemeinnützige GmbH: pioneershub.org
in collaboration with NumFOCUS Inc.: numfocus.org
If you enjoyed this session, please like, and subscribe to our channel for more insightful talks and discussions.
Share this video with your network to spread the knowledge!
Hashtags:
#Python #PyConDE #PyData #OpenSource #AI #DataScience #MachineLearning #SoftwareEngineering #LLMs #Community #Sovereignty
Acknowledgements:
Special thanks to all the volunteers and sponsors who made this event possible.
About:
Python Softwareverband e.V.:
PySV is a non-profit that promotes the use and development of Python in Germany through events, education, and advocacy, fostering an open Python community.
Pioneers Hub gemeinnützige GmbH:
is a non-profit fostering innovation in AI and tech by connecting experts and promoting knowledge exchange through events and collaborative initiatives.
NumFOCUS Inc.
supports open-source scientific computing by providing financial and logistical support to key projects like NumPy and Jupyter, promoting sustainable development and collaboration.
pydata.org
PyData is an educational program of NumFOCUS, a 501(c)3 non-profit organization in the United States. PyData provides a forum for the international community of users and developers of data analysis tools to share ideas and learn from each other. The global PyData network promotes discussion of best practices, new approaches, and emerging technologies for data management, processing, analytics, and visualization. PyData communities approach data science using many languages, including (but not limited to) Python, Julia, and R.