Uploaded May 2018 | Updated September 2026, 2 weeks ago
ICRA 2018 Spotlight Video
Interactive Session Thu AM Pod D.7
Authors: ROY CHOWDHURY, ABHRA; Soh, Gim Song; Foong, Shaohui; Wood, Kristin
Title: Evaluating Robust Trajectory Control of a Miniature Rolling and Spinning Robot in Outdoor Conditions
Abstract:
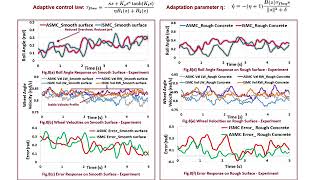
This paper presents trajectory following control experiments of a miniature spherical rolling and spinning robot mechanism on three different types of outdoor surfaces. The research is inspired from the efficient locomotory rolling patterns of various insects in unstructured environment. A nonlinear adaptive sliding mode (ASMC) feedback method maintains the robot stability and robustness in the presence of parameter uncertainties and external disturbances. The proposed trajectory following control policy is developed, implemented and tested for the miniature spherical robot on three different types of irregular surfaces in outdoors. Trajectory following accuracy, roll angle stability and wheel velocity response are three parameters measured to evaluate robot performance. (ASMC)controller is compared with an integral sliding (ISMC)controller. Experimental results show that proposed control policy is able to manage an accurate trajectory following amidst robust control of a rolling and spinning robot on three types of irregular surface in practical outdoor conditions.
ICRA 2018 Spotlight Video
Interactive Session Thu AM Pod D.7
Authors: ROY CHOWDHURY, ABHRA; Soh, Gim Song; Foong, Shaohui; Wood, Kristin
Title: Evaluating Robust Trajectory Control of a Miniature Rolling and Spinning Robot in Outdoor Conditions
Abstract:
This paper presents trajectory following control experiments of a miniature spherical rolling and spinning robot mechanism on three different types of outdoor surfaces. The research is inspired from the efficient locomotory rolling patterns of various insects in unstructured environment. A nonlinear adaptive sliding mode (ASMC) feedback method maintains the robot stability and robustness in the presence of parameter uncertainties and external disturbances. The proposed trajectory following control policy is developed, implemented and tested for the miniature spherical robot on three different types of irregular surfaces in outdoors. Trajectory following accuracy, roll angle stability and wheel velocity response are three parameters measured to evaluate robot performance. (ASMC)controller is compared with an integral sliding (ISMC)controller. Experimental results show that proposed control policy is able to manage an accurate trajectory following amidst robust control of a rolling and spinning robot on three types of irregular surface in practical outdoor conditions.