Uploaded May 2018 | Updated September 2026, 2 weeks ago
ICRA 2018 Spotlight Video
Interactive Session Wed PM Pod I.1
Authors: Williams, Edward; Gopalan, Nakul; Rhee, Mina; Tellex, Stefanie
Title: Learning to Parse Natural Language to Grounded Reward Functions with Weak Supervision
Abstract:
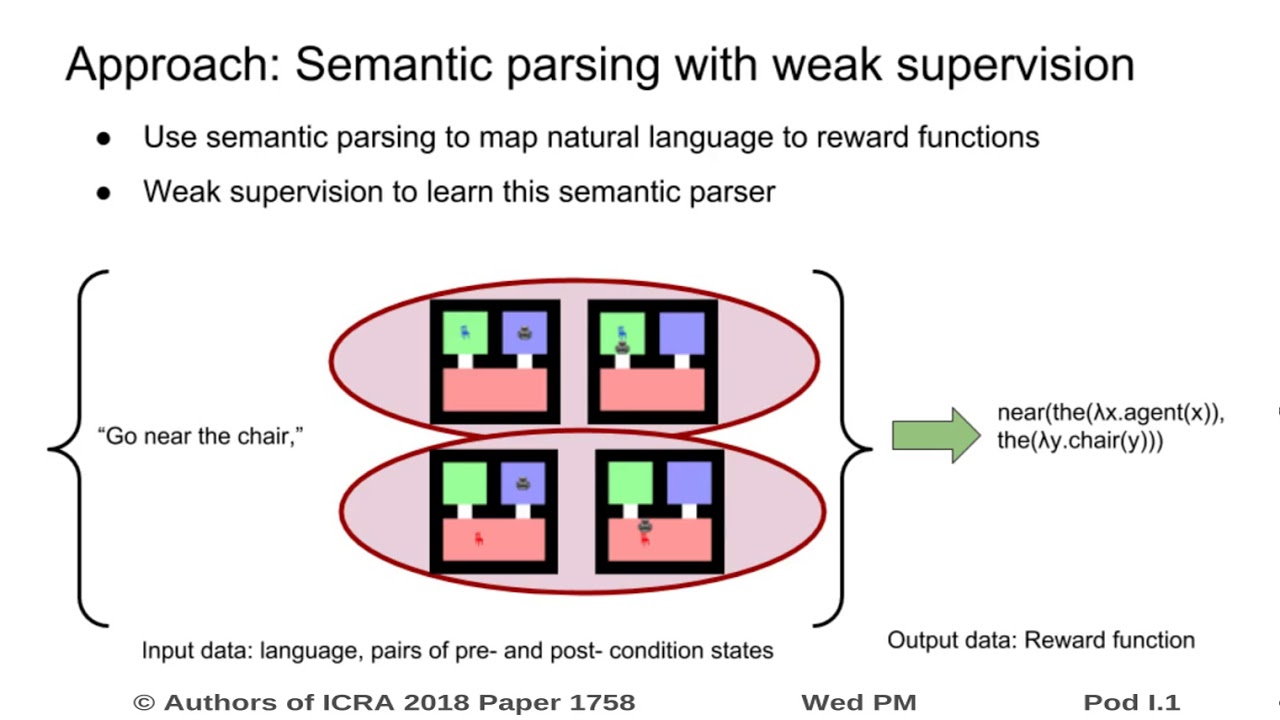
In order to intuitively and efficiently collaborate with humans, robots must learn to complete tasks specified using natural language. We represent natural language instructions as goal-state reward functions specified using lambda calculus. Using reward functions as language representations allows robots to plan efficiently in stochastic environments. To map sentences to such reward functions, we learn a weighted linear Combinatory Categorial Grammar (CCG) semantic parser. The parser, including both parameters and the CCG lexicon, is learned from a validation procedure that does not require execution of a planner, annotating reward functions, or labeling parse trees, unlike prior approaches. To learn a CCG lexicon and parse weights, we use coarse lexical generation and validation-driven perceptron weight updates using the approach of Artzi and Zettlemoyer [4]. We present results on the Cleanup World domain [19] to demonstrate the potential of our approach. We report an F1 score of 0.82 on a collected corpus of 23 tasks containing combinations of nested referential expressions, comparators and object properties with 2037 corresponding sentences. Our goal-condition learning approach enables an improvement of orders of magnitude in computation time over a baseline that performs planning during learning, while achieving comparable results. Further, we conduct an experiment with just 6 labeled demonstrations to show the ease of teaching a robot behaviors using our method.
ICRA 2018 Spotlight Video
Interactive Session Wed PM Pod I.1
Authors: Williams, Edward; Gopalan, Nakul; Rhee, Mina; Tellex, Stefanie
Title: Learning to Parse Natural Language to Grounded Reward Functions with Weak Supervision
Abstract:
In order to intuitively and efficiently collaborate with humans, robots must learn to complete tasks specified using natural language. We represent natural language instructions as goal-state reward functions specified using lambda calculus. Using reward functions as language representations allows robots to plan efficiently in stochastic environments. To map sentences to such reward functions, we learn a weighted linear Combinatory Categorial Grammar (CCG) semantic parser. The parser, including both parameters and the CCG lexicon, is learned from a validation procedure that does not require execution of a planner, annotating reward functions, or labeling parse trees, unlike prior approaches. To learn a CCG lexicon and parse weights, we use coarse lexical generation and validation-driven perceptron weight updates using the approach of Artzi and Zettlemoyer [4]. We present results on the Cleanup World domain [19] to demonstrate the potential of our approach. We report an F1 score of 0.82 on a collected corpus of 23 tasks containing combinations of nested referential expressions, comparators and object properties with 2037 corresponding sentences. Our goal-condition learning approach enables an improvement of orders of magnitude in computation time over a baseline that performs planning during learning, while achieving comparable results. Further, we conduct an experiment with just 6 labeled demonstrations to show the ease of teaching a robot behaviors using our method.