Uploaded February 2026 | Updated September 2026, 2 weeks ago
by Maarten Vandeperre
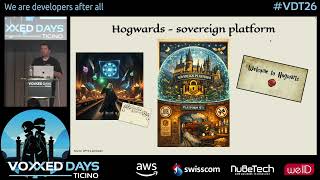
That bill from the Gringotts of third-party LLMs just arrived via owl post. It's... a howler. And the Aurors from your security department are asking pointed questions about which dark wizards are seeing your company's secret spells. In the rush to use powerful magic, we've dabbled in the Dark Arts of black-box APIs, trading control for convenience and inviting Dementors of risk into our infrastructure. It's time to master our own magic.
This session is for wizards of engineering who are ready to move beyond chanting borrowed incantations. We'll learn the potions and charms needed to architect a secure, private model-as-a-service (MaaS) platform using powerful, open-source magic. This isn't Transfiguration theory—it's a practical guide to creating your own Marauder's Map for models. Using API Connectivity as our all-seeing eye, we'll cast protective enchantments (access policies), consult the Pensieve of analytics, and manage our galleon spend.
Leave this session with your own spellbook to stop being a squib (i.e., a person who was born into a wizarding family but does not possess any magical powers) and start being a Master of the AI Arts. It's time to take back control, brew your own powerful potions, and deploy your models with the confidence of Dumbledore himself.
by Maarten Vandeperre
That bill from the Gringotts of third-party LLMs just arrived via owl post. It's... a howler. And the Aurors from your security department are asking pointed questions about which dark wizards are seeing your company's secret spells. In the rush to use powerful magic, we've dabbled in the Dark Arts of black-box APIs, trading control for convenience and inviting Dementors of risk into our infrastructure. It's time to master our own magic.
This session is for wizards of engineering who are ready to move beyond chanting borrowed incantations. We'll learn the potions and charms needed to architect a secure, private model-as-a-service (MaaS) platform using powerful, open-source magic. This isn't Transfiguration theory—it's a practical guide to creating your own Marauder's Map for models. Using API Connectivity as our all-seeing eye, we'll cast protective enchantments (access policies), consult the Pensieve of analytics, and manage our galleon spend.
Leave this session with your own spellbook to stop being a squib (i.e., a person who was born into a wizarding family but does not possess any magical powers) and start being a Master of the AI Arts. It's time to take back control, brew your own powerful potions, and deploy your models with the confidence of Dumbledore himself.