Uploaded April 2026 | Updated September 2026, 2 weeks ago
#VDZ26
Running Your Coding Agent Locally: Lessons from a Real-World Experiment by Stefano Maestri and Alessio Soldano
Cloud-based coding assistants like Claude Code or GitHub Copilot are powerful—but what happens when you try to bring that experience fully on-premise?
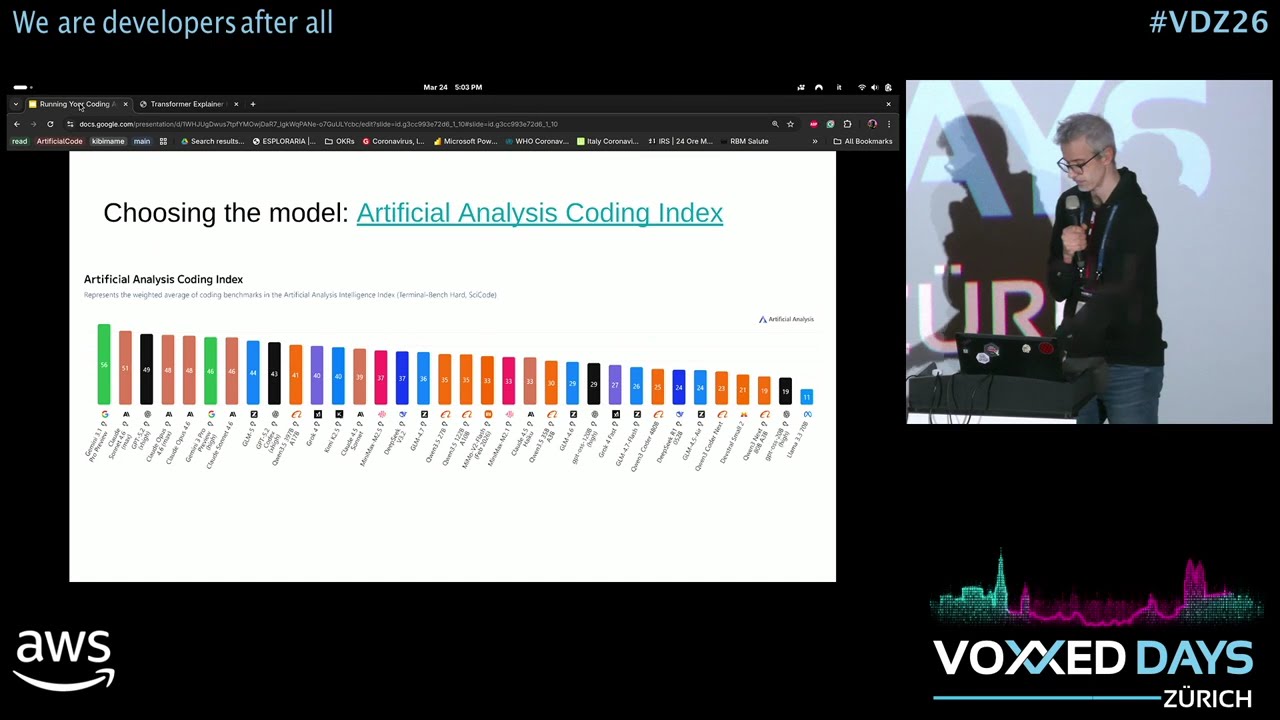
In this talk, we’ll explore the practical journey of building and running a local AI coding setup: choosing models, hosting them on consumer hardware, connecting frontends like LM Studio, and evaluating what really works (and what doesn’t).We’ll discuss trade-offs in latency, memory, and tool integration, the role of KV cache and model routing, and how far open-source models can go in replicating commercial AI dev environments.
Expect a mix of architecture insights, debugging war stories, and honest conclusions about what’s currently feasible—and what’s still wishful thinking—when it comes to local AI coding.
#VDZ26
Running Your Coding Agent Locally: Lessons from a Real-World Experiment by Stefano Maestri and Alessio Soldano
Cloud-based coding assistants like Claude Code or GitHub Copilot are powerful—but what happens when you try to bring that experience fully on-premise?
In this talk, we’ll explore the practical journey of building and running a local AI coding setup: choosing models, hosting them on consumer hardware, connecting frontends like LM Studio, and evaluating what really works (and what doesn’t).We’ll discuss trade-offs in latency, memory, and tool integration, the role of KV cache and model routing, and how far open-source models can go in replicating commercial AI dev environments.
Expect a mix of architecture insights, debugging war stories, and honest conclusions about what’s currently feasible—and what’s still wishful thinking—when it comes to local AI coding.