Uploaded August 2026 | Updated September 2026, 2 weeks ago
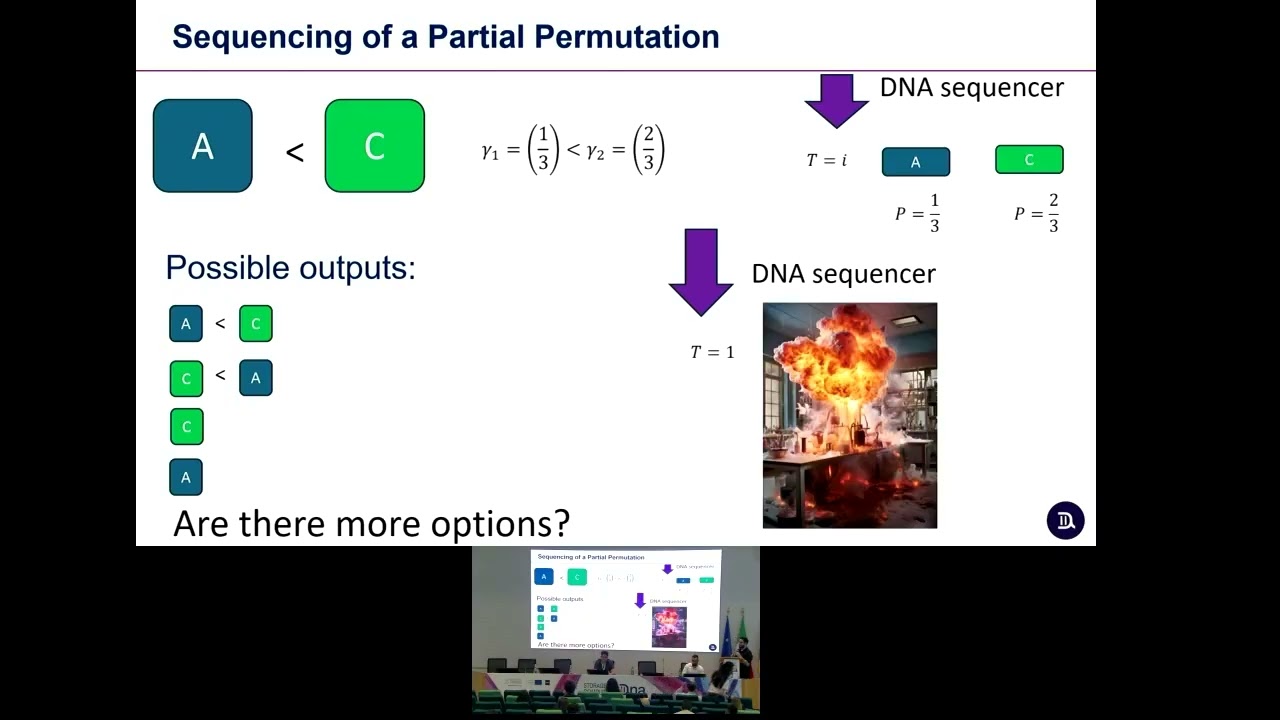
The main obstacle to reducing the cost of DNA-based data storage is the synthesis process. Composite DNA symbols leverage the inherent redundancy in synthesis by representing positions as mixtures of nucleotides, effectively increasing storage density. In this work, we further develop the theory of rank-modulated composite symbols, where information is determined by the relative ordering of motifs rather than exact frequency values. Unlike previous models that used fixed-length permutations and Kendall’s tau distances, we introduce a more faithful physical model considering insertion and deletion errors occurring at the “tail” of the ranking, the lower-frequency motifs. We establish a theoretical equivalence between tail deletion, insertion, and indel codes and present optimal code constructions for variable-length permutations. Furthermore, we extend these results to sequences of symbols using a Tail Tensor Permutation Code (TTPC) construction. Our findings provide both theoretical bounds and efficient practical tools for high-density, error-resilient DNA data storage systems. Furthermore, our results demonstrate that allowing variable permutation resolutions significantly enhances the flexibility and error-resilience of high-density DNA storage systems, offering a practical path toward reducing synthesis cycles without sacrificing reliability.
Presented by
Tomer Cohen, Technion
This is a presentation from the 2026 Storage and Computing with DNA Conference.
· Learn More about the SNIA DNA Data Storage Alliance: snia.org/groups/snia-dna-technology-affiliate
· SNIA Educational Library: snia.org/library
· X: twitter.com/SNIA
· LinkedIn: linkedin.com/company/snia
The main obstacle to reducing the cost of DNA-based data storage is the synthesis process. Composite DNA symbols leverage the inherent redundancy in synthesis by representing positions as mixtures of nucleotides, effectively increasing storage density. In this work, we further develop the theory of rank-modulated composite symbols, where information is determined by the relative ordering of motifs rather than exact frequency values. Unlike previous models that used fixed-length permutations and Kendall’s tau distances, we introduce a more faithful physical model considering insertion and deletion errors occurring at the “tail” of the ranking, the lower-frequency motifs. We establish a theoretical equivalence between tail deletion, insertion, and indel codes and present optimal code constructions for variable-length permutations. Furthermore, we extend these results to sequences of symbols using a Tail Tensor Permutation Code (TTPC) construction. Our findings provide both theoretical bounds and efficient practical tools for high-density, error-resilient DNA data storage systems. Furthermore, our results demonstrate that allowing variable permutation resolutions significantly enhances the flexibility and error-resilience of high-density DNA storage systems, offering a practical path toward reducing synthesis cycles without sacrificing reliability.
Presented by
Tomer Cohen, Technion
This is a presentation from the 2026 Storage and Computing with DNA Conference.
· Learn More about the SNIA DNA Data Storage Alliance: snia.org/groups/snia-dna-technology-affiliate
· SNIA Educational Library: snia.org/library
· X: twitter.com/SNIA
· LinkedIn: linkedin.com/company/snia