Uploaded February 2025 | Updated September 2026, 3 days ago
Abstract:
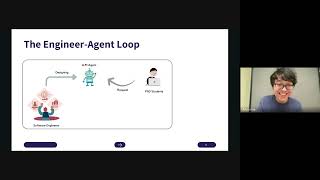
Large language model (LLM) Agents are powerful tools for completing complex tasks but remain underexplored in their ability to self-improve through feedback, adaptation, and exploration. In this talk, I present key advances in these three directions. First, I show that by drawing an analogy between optimization and interactive learning, feedback emerges as a powerful driver of iterative improvement for LLM agents. In particular, I highlight how directional feedback enables stable and efficient performance across a wide range of optimization tasks. Second, I introduce a novel optimization framework, "Optimization with Trace Oracle (OPTO),” that leverages execution traces and rich feedback to optimize LLM agents with complex workflows, akin to how AutoDiff enables differentiable optimization. Finally, I investigate LLMs' exploration capabilities in uncertain decision-making scenarios, proposing algorithm-guided methods that enable
smaller models (Gemini-1.5 Flash) to outperform larger ones (Gemini-1.5 Pro) in exploratory efficiency. Together, these insights outline a foundation for LLM agents that can learn, adapt, and explore autonomously, paving the way for the next generation of interactive AI systems.
Bio:
anie.me/about
Abstract:
Large language model (LLM) Agents are powerful tools for completing complex tasks but remain underexplored in their ability to self-improve through feedback, adaptation, and exploration. In this talk, I present key advances in these three directions. First, I show that by drawing an analogy between optimization and interactive learning, feedback emerges as a powerful driver of iterative improvement for LLM agents. In particular, I highlight how directional feedback enables stable and efficient performance across a wide range of optimization tasks. Second, I introduce a novel optimization framework, "Optimization with Trace Oracle (OPTO),” that leverages execution traces and rich feedback to optimize LLM agents with complex workflows, akin to how AutoDiff enables differentiable optimization. Finally, I investigate LLMs' exploration capabilities in uncertain decision-making scenarios, proposing algorithm-guided methods that enable
smaller models (Gemini-1.5 Flash) to outperform larger ones (Gemini-1.5 Pro) in exploratory efficiency. Together, these insights outline a foundation for LLM agents that can learn, adapt, and explore autonomously, paving the way for the next generation of interactive AI systems.
Bio:
anie.me/about