Uploaded January 2025 | Updated September 2026, 1 day ago
Abstract:
The intersection of language and vision is a fundamental aspect of human cognition. Our ability to interpret visual stimuli is often guided by linguistic constructs, enabling us to describe, understand, and interact with the world around us. This intrinsic connection suggests that language can serve as a powerful prior for creating systems with advanced visual intelligence.
Despite the broad success of existing systems, their applicability to critical domains remains limited, which we hypothesize is due to a lack of appropriate priors. Without the guidance of effective priors, models may
overly rely on in-domain data to form solutions, leading to potential catastrophic failures when deployed in different scenarios.
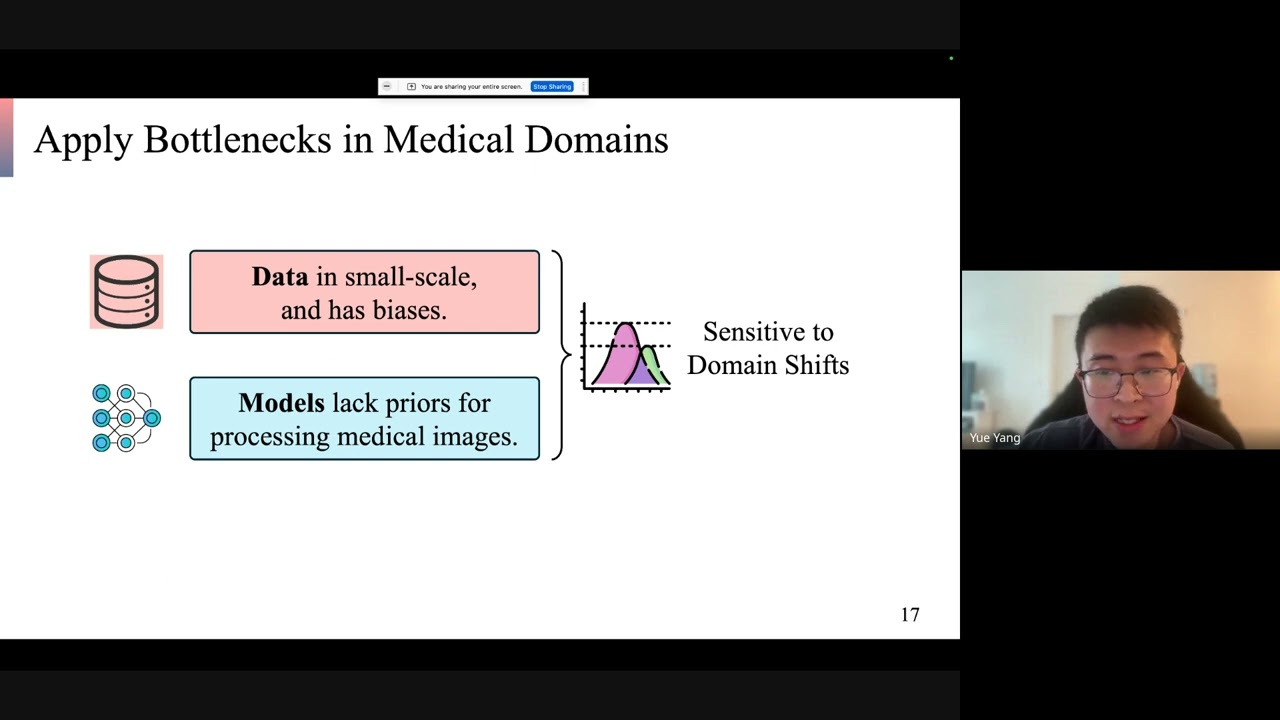
In this talk, I will introduce two ways of applying language priors to vision systems to enhance their interpretability, robustness, and data efficiency. First, I will show how language models can be used to construct high-performance concept bottlenecks for interpretable image classifiers, which exhibit significantly greater robustness to domain shifts in medical applications. Second, to address data scarcity in embodied AI and vision-language models, I will demonstrate how to use language-guided synthetic data to develop more generalizable embodied agents and multimodal models.
Bio:
Yue Yang is a final-year PhD candidate at the University of Pennsylvania, advised by Chris Callison-Burch and Mark Yatskar. His research interests lie in the intersection of Natural Language Processing and Computer Vision. His recent works aim to leverage the knowledge priors from large language models to improve the interpretability, robustness, and data efficiency of vision systems.
Personal Website: yueyang1996.github.io
Abstract:
The intersection of language and vision is a fundamental aspect of human cognition. Our ability to interpret visual stimuli is often guided by linguistic constructs, enabling us to describe, understand, and interact with the world around us. This intrinsic connection suggests that language can serve as a powerful prior for creating systems with advanced visual intelligence.
Despite the broad success of existing systems, their applicability to critical domains remains limited, which we hypothesize is due to a lack of appropriate priors. Without the guidance of effective priors, models may
overly rely on in-domain data to form solutions, leading to potential catastrophic failures when deployed in different scenarios.
In this talk, I will introduce two ways of applying language priors to vision systems to enhance their interpretability, robustness, and data efficiency. First, I will show how language models can be used to construct high-performance concept bottlenecks for interpretable image classifiers, which exhibit significantly greater robustness to domain shifts in medical applications. Second, to address data scarcity in embodied AI and vision-language models, I will demonstrate how to use language-guided synthetic data to develop more generalizable embodied agents and multimodal models.
Bio:
Yue Yang is a final-year PhD candidate at the University of Pennsylvania, advised by Chris Callison-Burch and Mark Yatskar. His research interests lie in the intersection of Natural Language Processing and Computer Vision. His recent works aim to leverage the knowledge priors from large language models to improve the interpretability, robustness, and data efficiency of vision systems.
Personal Website: yueyang1996.github.io