Uploaded May 2022 | Updated September 2026, 20 hours ago
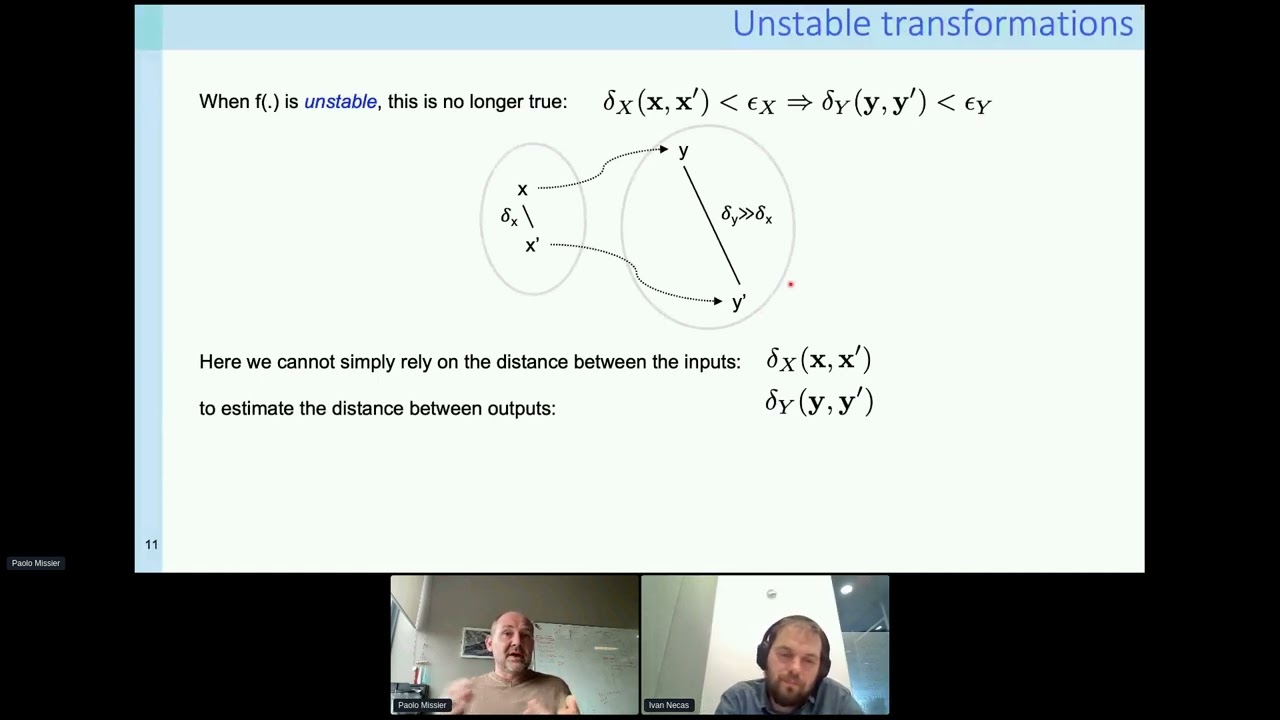
Analytics that are generated from “big data” may be valuable but also short-lived, namely when some of the underpinning data changes over time. When the processing is computationally expensive, it is desirable to be able to assess the need for re-computation in reaction to changes, i.e., in terms of marginal benefits relative to the current results, without actually executing the process. This capability is underpinned by data-diff functions, but we argue that this is not enough, and that a re-compute yes/no decision requires a deeper understanding of the process itself.
In the first part of the talk we suggest that histories of past executions can be used to inform such decisions, and articulate the role of data provenance specifically. We then present ReComp, a framework that we have used to experiment with these ideas, which we believe can be a beneficial addition to generic Data Science infrastructure, specifically in organizations where analytics are central, expensive, and repetitive.
In the second part, we broaden the scope of our research and present a provenance capture, storage, and query facility for generic Data Science pipelines.
Speaker
Paolo Missier, Professor of Big Data Analytics, Newcastle University
Conversation Leader
Ivan Nečas, Senior Principal Software Engineer, Red Hat
Analytics that are generated from “big data” may be valuable but also short-lived, namely when some of the underpinning data changes over time. When the processing is computationally expensive, it is desirable to be able to assess the need for re-computation in reaction to changes, i.e., in terms of marginal benefits relative to the current results, without actually executing the process. This capability is underpinned by data-diff functions, but we argue that this is not enough, and that a re-compute yes/no decision requires a deeper understanding of the process itself.
In the first part of the talk we suggest that histories of past executions can be used to inform such decisions, and articulate the role of data provenance specifically. We then present ReComp, a framework that we have used to experiment with these ideas, which we believe can be a beneficial addition to generic Data Science infrastructure, specifically in organizations where analytics are central, expensive, and repetitive.
In the second part, we broaden the scope of our research and present a provenance capture, storage, and query facility for generic Data Science pipelines.
Speaker
Paolo Missier, Professor of Big Data Analytics, Newcastle University
Conversation Leader
Ivan Nečas, Senior Principal Software Engineer, Red Hat