Uploaded August 2026 | Updated September 2026, 3 weeks ago
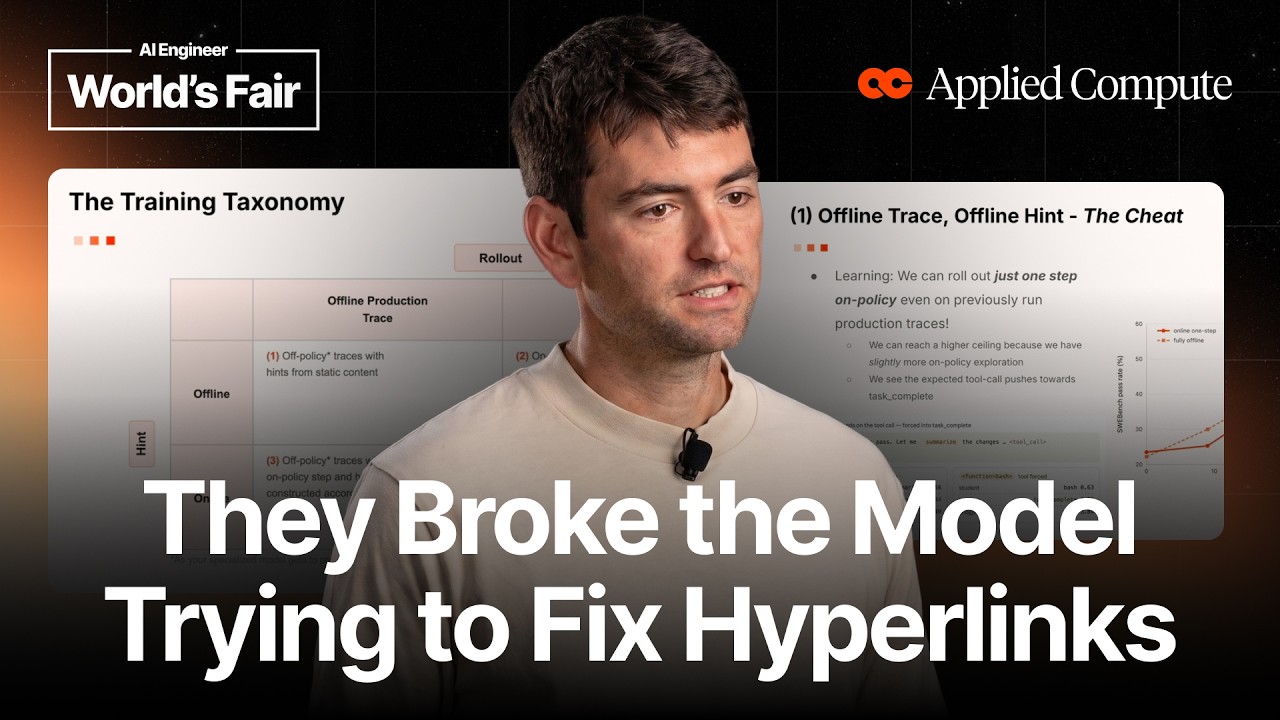
A Qwen thinking model was taking up to 80 turns to submit on SWE bench. Applied Compute wanted it wrapping up by turn 40 and got the submit tool call rate from 22% to 60% with test pass rate flat. The interesting part is the mechanism: because the rollout was conditioned on an old production trace that never called the tool, the teacher never touched the tool call tokens at all. It moved the reasoning path toward the call instead, and the call followed.
Sam Denton's frame is a grid. One axis is how online the traces are, from a single dump of production traces to a unified engine where serving and training are the same loop. The other is where the hint comes from, either static priors, such as knowing a support agent is too quick to refund, or a hint built dynamically from what the on policy model just did. Applied Compute works two corners of that grid. Offline hints on offline traces need no replayable environment and can improve an enterprise agent from a data dump on day one. Online hints on online traces have the far higher ceiling, and that is what fixed a customer whose harness required unusual hyperlink formatting: rewarding the format directly and finetuning on correct examples both degraded coding ability, while a hint written against each rollout took correct formatting from 15% to 80%. Two things he says make it work in practice. Let a judge pick where in the rollout the hint goes and distill only the next few steps, since the learning signal decays with distance from the hint. And mask which tokens you learn from, because the teacher has strong opinions about connector words that have nothing to do with the lesson. Throughout, the constraint he keeps is doing all of this without a golden answer to distill toward.
Speaker info:
- https://x.com/samueldenton
- linkedin.com/in/sam-denton-161b50126
Timestamps:
0:00 - The distillation spectrum, offline to online
2:46 - The holy grail: serving and training as one loop
4:00 - Where the hint comes from
4:42 - Online hints built from the rollout
5:19 - Four quadrants of distillation
7:50 - The two corners they actually work in
9:44 - Improve for free today, raise ceilings tomorrow
10:22 - Doing it without a golden answer
11:00 - SWE bench: wrapping up by turn 40
11:38 - The three metrics that matter
12:17 - What the hint actually says
12:55 - Moving the reasoning path, not the tool call
13:36 - Adding a single on policy step
14:17 - The hyperlink formatting problem
14:56 - Why rewards and finetuning both failed
15:34 - From 15% to 80% with online hints
16:13 - Per step hinting
16:50 - Why the signal decays with distance
17:27 - Relevance masked self distillation
18:07 - What it adds up to