Uploaded July 2026 | Updated September 2026, 3 weeks ago
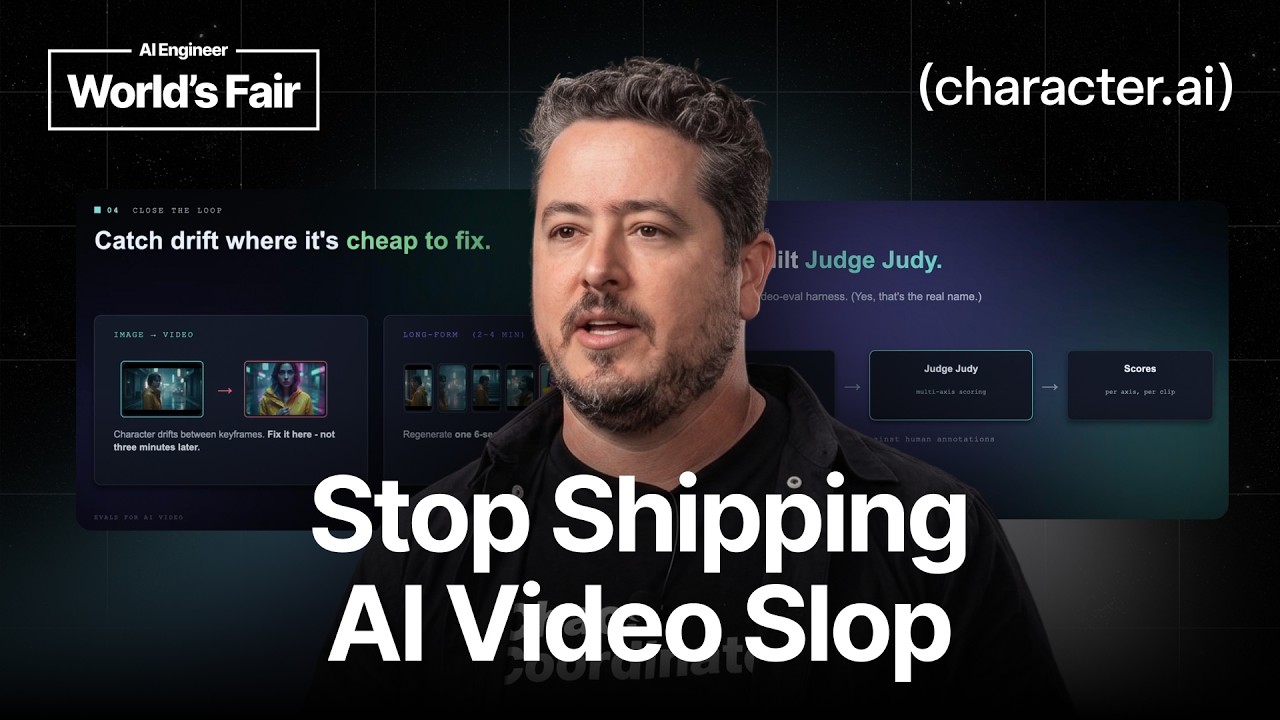
A generated clip where the character stands frozen for four seconds can still score well, because the judge rewarded the gloss and the vibe instead of what actually happened. That failure is the whole problem with evaling video: CLIP score misses temporal incoherence, a team watching clips on Friday does not scale, and any AI judge you wire up drifts from human preference unless you measure the drift. Video breaks the text playbook because it has to hold temporal consistency, shot continuity, and a coherent story across frames, not just look good in a single still.
The fix that stuck was to stop scoring and start comparing. Absolute scores collapsed to one dimension, but pairwise preference, is B a better story than A, held up, so Maor Bril's team trained a Qwen3-VL judge with Bradley-Terry loss on pairs of real and deliberately broken footage to catch slop before it ships. Drift is cheapest to catch early, especially on longer form video, so the judge runs as a regression gate in CI: every AgentX release at Character.ai clears an eval wall, calibrated against human scores, before users ever see it.
Speaker info:
- https://x.com/maorbril
- linkedin.com/in/maorbril
- github.com/character-ai/judgejudy
Timestamps:
0:00 - Introduction: evaluating AI generated video
1:19 - Why video generation drifts between frames
3:14 - Story and sound: what a clip has to get right
4:43 - LLM as a judge, and catching drift early
7:01 - Story and sound failure modes
8:28 - Small model vs bigger model as judge
9:20 - Don't score, compare: pairwise preference
10:47 - When the judge scores vibe over substance
11:53 - Pairing real footage to train a quality detector
13:27 - Self verification in the generation loop
15:05 - Q&A