Uploaded August 2026 | Updated September 2026, 2 weeks ago
[EuroPython 2026 - S4 on 2026-07-16]
π€ *AI Slop to AI Gold: Building Codebases That Last by Dan Jones*
π https://ep2026.europython.eu/session/ai-slop-to-ai-gold-building-codebases-that-last
π Abstract:
AI can generate Python faster than ever before. It can also generate an astonishing amount of code that nobody wants to maintain.
That's not a new problem.
Every generation of software tooling has made writing code cheaper while increasing the cost of poor engineering. AI is simply the latest example.
Some Python features and architectural patterns don't just catch bugs - they make them difficult to write in the first place. Those ideas weren't designed for AI, but they may be exactly what AI needs.
AI hasn't changed what good software engineering looks like. It's made good software engineering impossible to ignore.
---
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: creativecommons.org/licenses/by-nc-sa/4.0
[EuroPython 2026 - S4 on 2026-07-16]
π€ *AI Slop to AI Gold: Building Codebases That Last by Dan Jones*
π https://ep2026.europython.eu/session/ai-slop-to-ai-gold-building-codebases-that-last
π Abstract:
AI can generate Python faster than ever before. It can also generate an astonishing amount of code that nobody wants to maintain.
That's not a new problem.
Every generation of software tooling has made writing code cheaper while increasing the cost of poor engineering. AI is simply the latest example.
Some Python features and architectural patterns don't just catch bugs - they make them difficult to write in the first place. Those ideas weren't designed for AI, but they may be exactly what AI needs.
AI hasn't changed what good software engineering looks like. It's made good software engineering impossible to ignore.
---
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: creativecommons.org/licenses/by-nc-sa/4.0

![Fast and Furious: 26βs Tooling Stack for a Streamlined Developer Experience - Nacho Llorca
[EuroPython 2026 - S4 on 2026-07-17]
π€ *Fast and Furious: 26βs Tooling Stack for a Streamlined Developer Experience by Nacho Llorca*
π https://ep2026.europython.eu/session/fast-and-furious-26s-tooling-stack-for-a-streamlined-developer-experience
π Abstract:
Cohesive, automated quality checks are first-order necessities β especially as LLMs take on more code-writing responsibilities. But developer experience is just as critical: if type checking takes five minutes, developers either lose their flow or feel tempted to skip it. If linting isnβt enforced, reviewer fatigue skyrockets. Blink, and Copilot might commit an API key to your repo β and the list goes on.
The tooling pioneers we know and love (`black`, `mypy`, and others) paved the way, but a new generation of faster, more reliable tools β yup, rewritten in Rust β is here to guardrail and simplify development. This talk presents a setup for Python development, contrasting the available options.
*What you will learn:*
- *The dependency management wars:* Why `uv` has emerged as the gold standard over Poetry or Hatch.
- *One tool to rule them all:* How to use `just` as a command runner to unify your local and CI environments.
- *You shall not pass:* Setting up `ruff` for linting, `pyrefly` (or `ty`) for type hints, and `complexipy` for cyclomatic complexity to keep your codebase cohesive and maintainable. Using `prek` (instead of `pre-commit`) to enforce the standards , including Conventional Commits message syntax and secret detection with `gitleaks`. Replicating pre-commit checks (and test coverage!) with every push in your CI pipeline.
- *Release the troll:* Implementing `semantic-release` to automate versioning and PyPI publishing.
A configurable Copier template will be provided to explore different setups using these frameworks.
*Prerequisites:* Familiarity with Python development and basic CI/CD concepts. No Rust knowledge required (though a high tolerance for Rust-related puns is encouraged).
*Inspiration:* This talk is inspired by Florian Wilhelmβs _Streamlining Python Development: A Guide to a Modern Project Setup_ from PyConDE 2024.
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ Fast and Furious: 26βs Tooling Stack for a Streamlined Developer Experience - Nacho Llorca](https://i.ytimg.com/vi/jg1ZaqcK7ds/mqdefault.jpg)
![Python and HTTP/3: feel the difference in performance - Daniel Vahla
[EuroPython 2026 - S3B on 2026-07-15]
π€ *Python and HTTP/3: feel the difference in performance by Daniel Vahla*
π https://ep2026.europython.eu/session/python-and-http-3-feel-the-difference-in-performance
π Abstract:
# Python and HTTP/3: feel the difference in performance
## Abstract
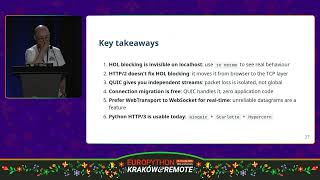
Building real-time Python applications, from live dashboards to multiplayer games, often feels like a battle against an invisible lag. While we focus on optimizing our async code, the underlying transport protocol often sabotages us: `TCP` guarantees ordering at the absolute cost of responsiveness.
In this session, I will show that the standard choice of using Websocket over `HTTP/1.1` or `HTTP/2` can make the application perform horribly, due to the head-of-line blocking problem that is visible when the network is unstable.
Then I will present how `HTTP/3` and `WebTransport` eliminate transport-layer bottlenecks and enable seamless connection migration for network switching users.
The audience will experience the difference between protocols performance firsthand through a live three-round multiplayer snake game demo.
## Description
### The Problem
Application performance is a complex challenge. Users often complain about lag, and regardless of how well we optimize our business logic, the issue persists. All too often, the blame is shifted to the client for having a spotty network. However, even under ideal conditions, users experience disruptions simply by being mobile, due to switching between Wi-Fi access points or cellular towers. The core problem is that many developers are unaware of the limitations of `HTTP/1.1` and `HTTP/2`, or that implementing `HTTP/3` might be a solution.
### Why This is Interesting to the Python Community
As Python applications become more real-time and data-intensive, traditional networking stacks are reaching their limits. There are important advances in technology that the audience should get familiar with, like `HTTP/3`, `QUIC`, and `WebTransport`. What is also important, is to be aware of how the Python ecosystem is still fragmented when it comes to supporting `HTTP/3`.
Despite that, a solution is achievable, and by using a combination of `Starlette` and `aioquic` code across three generations of transport protocols, the audience will experience and learn how protocol choice dictates application reliability on imperfect networks.
### Key takeaways:
- Witness an app suffering from transport-layer head-of-line blocking.
- Understand the Python `HTTP/3` ecosystem, including `aioquic`, `Hypercorn`, and `Starlette`.
- Deploy a `HTTP/3` server handling `WebTransport` datagrams for real-time data.
- Learn how to use Linux traffic control (`tc`) to inject some chaos to the network
- Play multiplayer Snake!
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ Python and HTTP/3: feel the difference in performance - Daniel Vahla](https://i.ytimg.com/vi/jvbCworTC8A/mqdefault.jpg)
![Surviving LLM Traffic Spikes: Routing, Rate Limits, and Failover in Python - Sergi Porta
[EuroPython 2026 - S3B on 2026-07-16]
π€ *Surviving LLM Traffic Spikes: Routing, Rate Limits, and Failover in Python by Sergi Porta*
π https://ep2026.europython.eu/session/surviving-llm-traffic-spikes-routing-rate-limits-and-failover-in-python
π Abstract:
Your team ships an AI feature and users love it. Then one viral post turns normal load into hundreds of LLM requests per second.
LLM calls dont behave like traditional API requests. Theyre slow (sometimes seconds), expensive, rate-limited by providers, and a single provider outage can take your entire feature down. You cant just add more servers. You need a routing layer that knows where to send traffic, when to back off, and how to fail without taking everything with it.
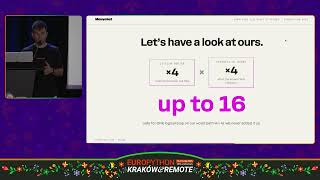
In this talk, well walk through the LLM traffic routing architecture we built in Python at Manychat, where we serve AI-powered automation to thousands of Instagram and messaging accounts. Everything well show is running in production.
Well cover the core gateway patterns for multi-provider LLM traffic, implemented using LiteLLM Router as a reference design.
By the end, youll walk away with:
- A weighted routing blueprint you can adapt to your own provider mix
- Fallback and cooldown rules designed to survive real outages
- Practical rate limiting (requests and tokens) with retry backoff
- The monitoring baseline (latency, tokens, errors by provider, weight drift) to catch issues before they cascade
- A checklist for rolling this out safely, incrementally
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ Surviving LLM Traffic Spikes: Routing, Rate Limits, and Failover in Python - Sergi Porta](https://i.ytimg.com/vi/jwblSAaFnNc/mqdefault.jpg)

![Free-threaded Python: past, present and future - Thomas Wouters
[EuroPython 2026 - S1 on 2026-07-15]
π€ *Free-threaded Python: past, present and future by Thomas Wouters*
π https://ep2026.europython.eu/session/free-threaded-python-past-present-and-future
π Abstract:
Free-threaded Python, the effort to remove the Global Interpreter Lock from CPython, is one of the biggest and most exciting changes to Python in many years. However, It can be hard to follow what that means, what effect it will have on you and your code, and how this isnt yet another Python 2 to 3 migration.
This overview will explain what free-threading is, why its a big deal, how it differs from other ways to deal with the GIL, and what the plan is for ensuring a smooth migration. Well explain the basics of thread safety, data races, and concurrent designs, how those apply to Python code, and how this will and wont change when the GIL is disabled. And yes, well show some threads go _brrr_.
Although well mention some complex, deeply technical problems, this is not a technical deep dive and any experience level is welcome.
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ Free-threaded Python: past, present and future - Thomas Wouters](https://i.ytimg.com/vi/kRq2V_2252A/mqdefault.jpg)


![Defending Open Source from AI Slop: A Maintainers Practical Guide
[EuroPython 2026 - S1 on 2026-07-17]
π€ *Defending Open Source from AI Slop: A Maintainers Practical Guide by Sviatoslav Sydorenko (Π‘Π²ΡΡΠΎΡΠ»Π°Π² Π‘ΠΈΠ΄ΠΎΡΠ΅Π½ΠΊΠΎ)*
π https://ep2026.europython.eu/session/defending-open-source-from-ai-slop-a-maintainer-s-practical-guide
π Abstract:
Open source maintainers are drowning in a new kind of noise. AI-generated pull requests β superficial, poorly reasoned, and submitted without genuine understanding of the codebase β are consuming review bandwidth that was already scarce. These contributions range from cosmetic improvements that introduce subtle bugs to elaborate refactorings that no one asked for, all bearing telltale signs of LLM output: confident tone, plausible-looking code, and zero awareness of project conventions.
This talk presents a practical, battle-tested framework for combating AI slop without discouraging legitimate contributors. Drawing from real experiences maintaining pip-tools, aiohttp, ansible-core, CherryPy, and other Python projects, Ill share concrete strategies that work today.
First, well dissect the anatomy of AI slop PRs β what they look like, why they pass superficial review, and the hidden costs beyond wasted review time: CI compute waste, security risks from plausible-but-wrong code, and the demoralizing effect on genuine contributors who see low-effort submissions getting attention.
Then Ill walk through a defense-in-depth approach being developed across my projects: updating `CONTRIBUTING.md` with explicit expectations about understanding the codebase before submitting changes; crafting repository-level LLM instruction files (like `AGENTS.md`/`CLAUDE.md`) that steer AI tools toward project-specific conventions; configuring PR templates to require evidence of human reasoning; and establishing community norms that set quality expectations without being hostile to newcomers.
Well also tackle the harder questions: Where is the line between AI-assisted (the human drives and understands the change) and AI-generated (the human clicks submit on LLM output)? How do we preserve the welcoming culture that makes open source special while defending against low-effort spam? What should platforms like GitHub improve for maintainers?
Youll leave with a ready-to-adapt policy template and configuration files for your own projects.
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ Defending Open Source from AI Slop: A Maintainers Practical Guide](https://i.ytimg.com/vi/lDxaIKAUBoc/mqdefault.jpg)