Uploaded August 2026 | Updated September 2026, 2 weeks ago
[EuroPython 2026 - S3B on 2026-07-16]
🎤 *Surviving LLM Traffic Spikes: Routing, Rate Limits, and Failover in Python by Sergi Porta*
🔗 https://ep2026.europython.eu/session/surviving-llm-traffic-spikes-routing-rate-limits-and-failover-in-python
📝 Abstract:
Your team ships an AI feature and users love it. Then one viral post turns "normal load" into hundreds of LLM requests per second.
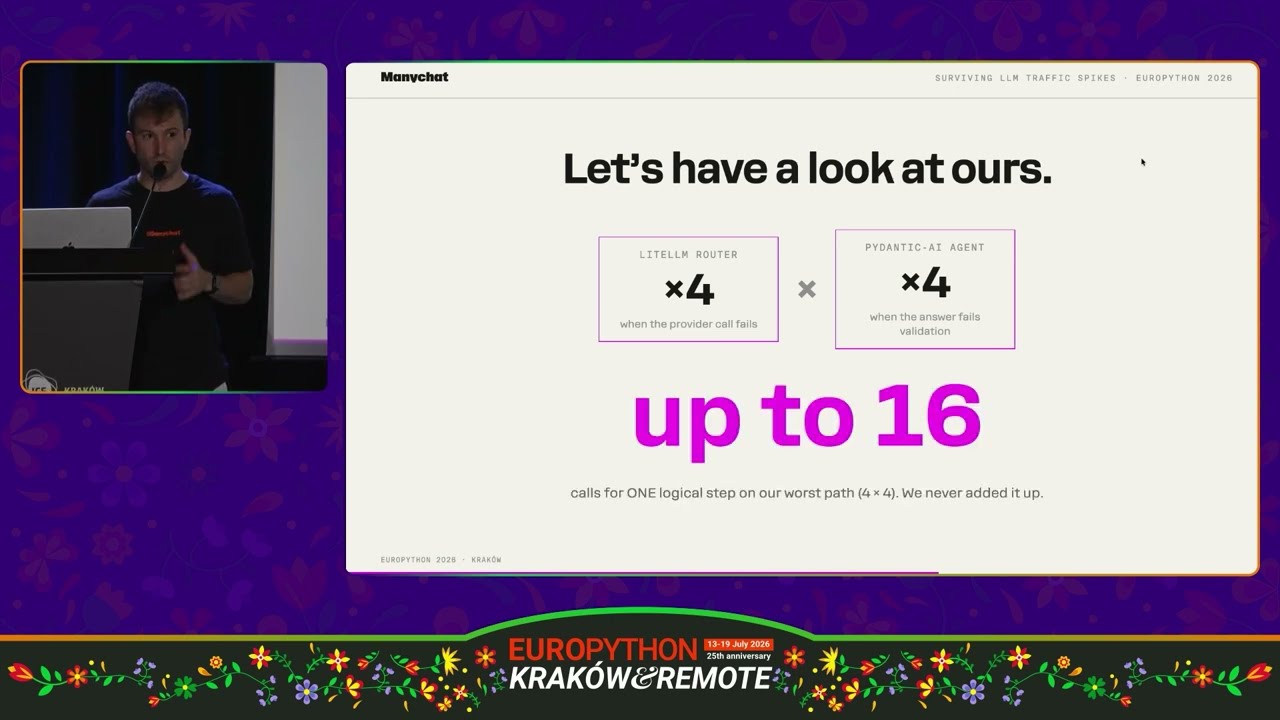
LLM calls don't behave like traditional API requests. They're slow (sometimes seconds), expensive, rate-limited by providers, and a single provider outage can take your entire feature down. You can't just "add more servers." You need a routing layer that knows where to send traffic, when to back off, and how to fail without taking everything with it.
In this talk, we'll walk through the LLM traffic routing architecture we built in Python at Manychat, where we serve AI-powered automation to thousands of Instagram and messaging accounts. Everything we'll show is running in production.
We'll cover the core gateway patterns for multi-provider LLM traffic, implemented using LiteLLM Router as a reference design.
By the end, you'll walk away with:
- A weighted routing blueprint you can adapt to your own provider mix
- Fallback and cooldown rules designed to survive real outages
- Practical rate limiting (requests and tokens) with retry backoff
- The monitoring baseline (latency, tokens, errors by provider, weight drift) to catch issues before they cascade
- A checklist for rolling this out safely, incrementally
---
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: creativecommons.org/licenses/by-nc-sa/4.0
[EuroPython 2026 - S3B on 2026-07-16]
🎤 *Surviving LLM Traffic Spikes: Routing, Rate Limits, and Failover in Python by Sergi Porta*
🔗 https://ep2026.europython.eu/session/surviving-llm-traffic-spikes-routing-rate-limits-and-failover-in-python
📝 Abstract:
Your team ships an AI feature and users love it. Then one viral post turns "normal load" into hundreds of LLM requests per second.
LLM calls don't behave like traditional API requests. They're slow (sometimes seconds), expensive, rate-limited by providers, and a single provider outage can take your entire feature down. You can't just "add more servers." You need a routing layer that knows where to send traffic, when to back off, and how to fail without taking everything with it.
In this talk, we'll walk through the LLM traffic routing architecture we built in Python at Manychat, where we serve AI-powered automation to thousands of Instagram and messaging accounts. Everything we'll show is running in production.
We'll cover the core gateway patterns for multi-provider LLM traffic, implemented using LiteLLM Router as a reference design.
By the end, you'll walk away with:
- A weighted routing blueprint you can adapt to your own provider mix
- Fallback and cooldown rules designed to survive real outages
- Practical rate limiting (requests and tokens) with retry backoff
- The monitoring baseline (latency, tokens, errors by provider, weight drift) to catch issues before they cascade
- A checklist for rolling this out safely, incrementally
---
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: creativecommons.org/licenses/by-nc-sa/4.0

![Free-threaded Python: past, present and future - Thomas Wouters
[EuroPython 2026 - S1 on 2026-07-15]
🎤 *Free-threaded Python: past, present and future by Thomas Wouters*
🔗 https://ep2026.europython.eu/session/free-threaded-python-past-present-and-future
📝 Abstract:
Free-threaded Python, the effort to remove the Global Interpreter Lock from CPython, is one of the biggest and most exciting changes to Python in many years. However, It can be hard to follow what that means, what effect it will have on you and your code, and how this isnt yet another Python 2 to 3 migration.
This overview will explain what free-threading is, why its a big deal, how it differs from other ways to deal with the GIL, and what the plan is for ensuring a smooth migration. Well explain the basics of thread safety, data races, and concurrent designs, how those apply to Python code, and how this will and wont change when the GIL is disabled. And yes, well show some threads go _brrr_.
Although well mention some complex, deeply technical problems, this is not a technical deep dive and any experience level is welcome.
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ Free-threaded Python: past, present and future - Thomas Wouters](https://i.ytimg.com/vi/kRq2V_2252A/mqdefault.jpg)


![Defending Open Source from AI Slop: A Maintainers Practical Guide
[EuroPython 2026 - S1 on 2026-07-17]
🎤 *Defending Open Source from AI Slop: A Maintainers Practical Guide by Sviatoslav Sydorenko (Святослав Сидоренко)*
🔗 https://ep2026.europython.eu/session/defending-open-source-from-ai-slop-a-maintainer-s-practical-guide
📝 Abstract:
Open source maintainers are drowning in a new kind of noise. AI-generated pull requests — superficial, poorly reasoned, and submitted without genuine understanding of the codebase — are consuming review bandwidth that was already scarce. These contributions range from cosmetic improvements that introduce subtle bugs to elaborate refactorings that no one asked for, all bearing telltale signs of LLM output: confident tone, plausible-looking code, and zero awareness of project conventions.
This talk presents a practical, battle-tested framework for combating AI slop without discouraging legitimate contributors. Drawing from real experiences maintaining pip-tools, aiohttp, ansible-core, CherryPy, and other Python projects, Ill share concrete strategies that work today.
First, well dissect the anatomy of AI slop PRs — what they look like, why they pass superficial review, and the hidden costs beyond wasted review time: CI compute waste, security risks from plausible-but-wrong code, and the demoralizing effect on genuine contributors who see low-effort submissions getting attention.
Then Ill walk through a defense-in-depth approach being developed across my projects: updating `CONTRIBUTING.md` with explicit expectations about understanding the codebase before submitting changes; crafting repository-level LLM instruction files (like `AGENTS.md`/`CLAUDE.md`) that steer AI tools toward project-specific conventions; configuring PR templates to require evidence of human reasoning; and establishing community norms that set quality expectations without being hostile to newcomers.
Well also tackle the harder questions: Where is the line between AI-assisted (the human drives and understands the change) and AI-generated (the human clicks submit on LLM output)? How do we preserve the welcoming culture that makes open source special while defending against low-effort spam? What should platforms like GitHub improve for maintainers?
Youll leave with a ready-to-adapt policy template and configuration files for your own projects.
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ Defending Open Source from AI Slop: A Maintainers Practical Guide](https://i.ytimg.com/vi/lDxaIKAUBoc/mqdefault.jpg)


![Stop Guessing, Start Understanding: How Arrow and Pandas Exchange Data
[EuroPython 2026 - S3A on 2026-07-17]
🎤 *Stop Guessing, Start Understanding: How Arrow and Pandas Exchange Data by Alenka Frim, Raúl Cumplido Domínguez*
🔗 https://ep2026.europython.eu/session/stop-guessing-start-understanding-how-arrow-and-pandas-exchange-data
📝 Abstract:
Pandas now natively supports PyArrow-backed data types. But what does that actually mean? If youve ever wondered how these two libraries relate to each other, whether they compete or complement each other, and what happens to your data when it moves between them, this talk is for you.
As PyArrow maintainers, we took on the challenge of digging into the conversion code between PyArrow and Pandas, and were here to share what weve learned. Well show you whats really going on under the hood: how Arrows columnar format differs from Pandas block-based memory layout (including what a BlockManager actually is), when data can be shared without copying, and when a full copy is unavoidable.
Well also clarify what each library is designed for and how they work together rather than against each other. With pandas increasingly adopting PyArrow as a backend, understanding this relationship is becoming essential rather than optional.
This talk is aimed at Python developers and data engineers who want to deepen their understanding of whats happening beneath the surface.
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ Stop Guessing, Start Understanding: How Arrow and Pandas Exchange Data](https://i.ytimg.com/vi/lnEA4ACO2yo/mqdefault.jpg)
![Design Patterns: Build better software from day one — Marine Guyot
[EuroPython 2025 — Terrace 2A on 2025-07-18]
🎤 *Design Patterns: Build better software from day one by Marine Guyot*
🔗 https://ep2025.europython.eu/session/design-patterns-build-better-software-from-day-one
📝 Abstract:
Starting a new software project is exciting! It’s your chance to build something clean, functional, and easy to manage. But without a strong foundation, even small projects can quickly spiral into a confusing mess of bugs, untracked changes, and hard-to-follow code. This is especially true in research environments, where programming often takes a backseat to scientific discovery, and software evolves unpredictably as it adapts to new experiments and shared use. So how do you set yourself up for success from the beginning?
This talk is your beginner-friendly guide to designing smarter, maintainable software using proven design patterns. We’ll explore how patterns like the Singleton (for managing shared resources), the Template Method (for reusable workflows), and the Factory Method (for flexible object creation) can transform your code from fragile and frustrating to solid and scalable.
Using real-world examples from research labs, we’ll walk through how these patterns solve common problems, simplify collaboration, and keep your projects on track, even as they grow. Whether youre developing a new pipeline, a data analysis tool, or an experiment software, this talk will equip you with the foundational knowledge to design software that supports your scientific goals without becoming an unmanageable burden.
Let’s start building research software the right way, so you can focus on science, not debugging.
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ Design Patterns: Build better software from day one — Marine Guyot](https://i.ytimg.com/vi/mB5uGoXYG3A/mqdefault.jpg)