Uploaded June 2019 | Updated September 2026, 35 minutes ago
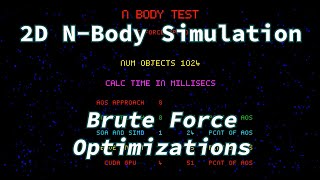
This video demonstrates the various optimizations that one can use to improve the performance of a brute force n-body simulation.
The following approaches were used:
AoS (Array of Structures): This uses a classic OOP design, with each Entity as a separate object, and is the simplest code to write. However, this code would be more difficult to optimize using SIMD directly, as described below.
SoA: This uses the Structure of Arrays approach, where each data type is contained in separate arrays - e.g. each mass of every entity is contained in a "mass" array, so similar data are packed tightly together for (theoretically) faster access and use. See more about AoS vs SoA here: en.wikipedia.org/wiki/AOS_and_SOA
SoA + SIMD: Using 256bit SIMD oprerations allows the CPU to operate on 8 floating points every cycle. This provides a dramatic performance boost, albeit at the expense of code readability. It must be said that the SoA approach does lend itself very well to SIMD, as the data is already packed in such a way as to allow SIMD operations on it, limiting the need to revise existing code. I learned SIMD from various guides on the internet and these tutorials by Chili: youtu.be/GwII1AJzKN4
SoA + SIMD + Multithreading: This approach uses multithreading to use all cores on the CPU. Again, the gains are impressive. I was quite astounded at how much optimization you can get out of SIMD + mt; allowing for big gains in CPU usage and program speed! However, the code bloat is real!
CUDA (GPU): This approach is actually quite simple from a code perspective (although is much more of a pain to figure out how to set it up), and the GPU vastly outpaces the CPU particularly when the simulation size increases. Note that the millisecond values for the GPU are not accurate: OBS (video capture software) impacts the performance of the GPU, so the real gains are about 50-100x that of the traditional AoS / OOP approach. Quite astounding!
What is great about this is that these gains are all without adding "clever" optimization techniques such as quad trees, Barnes–Hut approaches, etc. I will likely look to replicate this visualization using some type of tree approach, hopefully allowing us to get our # of bodies to (far) above 1m using SIMD & mt / CUDA!
Acknowledgements:
This was made using the Chili Framework: http://wiki.planetchili.net/index.php... - thanks Chili!
Music by Eric Skiff, song "All of Us" for the intro and "Arpanauts" for the main sequence. (Available at EricSkiff.com/music)
This video demonstrates the various optimizations that one can use to improve the performance of a brute force n-body simulation.
The following approaches were used:
AoS (Array of Structures): This uses a classic OOP design, with each Entity as a separate object, and is the simplest code to write. However, this code would be more difficult to optimize using SIMD directly, as described below.
SoA: This uses the Structure of Arrays approach, where each data type is contained in separate arrays - e.g. each mass of every entity is contained in a "mass" array, so similar data are packed tightly together for (theoretically) faster access and use. See more about AoS vs SoA here: en.wikipedia.org/wiki/AOS_and_SOA
SoA + SIMD: Using 256bit SIMD oprerations allows the CPU to operate on 8 floating points every cycle. This provides a dramatic performance boost, albeit at the expense of code readability. It must be said that the SoA approach does lend itself very well to SIMD, as the data is already packed in such a way as to allow SIMD operations on it, limiting the need to revise existing code. I learned SIMD from various guides on the internet and these tutorials by Chili: youtu.be/GwII1AJzKN4
SoA + SIMD + Multithreading: This approach uses multithreading to use all cores on the CPU. Again, the gains are impressive. I was quite astounded at how much optimization you can get out of SIMD + mt; allowing for big gains in CPU usage and program speed! However, the code bloat is real!
CUDA (GPU): This approach is actually quite simple from a code perspective (although is much more of a pain to figure out how to set it up), and the GPU vastly outpaces the CPU particularly when the simulation size increases. Note that the millisecond values for the GPU are not accurate: OBS (video capture software) impacts the performance of the GPU, so the real gains are about 50-100x that of the traditional AoS / OOP approach. Quite astounding!
What is great about this is that these gains are all without adding "clever" optimization techniques such as quad trees, Barnes–Hut approaches, etc. I will likely look to replicate this visualization using some type of tree approach, hopefully allowing us to get our # of bodies to (far) above 1m using SIMD & mt / CUDA!
Acknowledgements:
This was made using the Chili Framework: http://wiki.planetchili.net/index.php... - thanks Chili!
Music by Eric Skiff, song "All of Us" for the intro and "Arpanauts" for the main sequence. (Available at EricSkiff.com/music)