Uploaded July 2024 | Updated September 2026, 2 days ago
Speaker: Dylan Hadfield-Menell, Assistant Professor, MIT
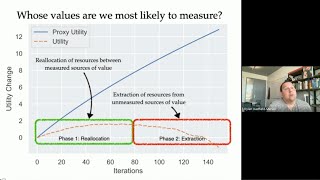
Abstract: The challenge of specifying goals for agents has long been recognized, as Kerr's seminal 1975 paper 'On the Folly of Rewarding A while Hoping for B' highlights the unintended consequences of misaligned reward systems. This issue lies at the heart of AI alignment research, which seeks to design incentive structures that reliably guide AI systems to achieve our intended objectives. In this talk, I will explore how brittle alignment emerges as an inherent result of incomplete goal specification. By presenting a theoretical model, I will demonstrate the sufficient conditions under which the unconstrained optimization of any goal that fails to capture all features of value ultimately leads to worse outcomes than forgoing optimization. Furthermore, I will extend this theoretical framework to address the importance of inclusivity in value specification. By reinterpreting the model such that different features of value represent the diverse perspectives of individuals, optimizing an incomplete goal can be expected to impact those whose values are not taken into account adversely. Consequently, technology that aligns an agent with the values of a single person or organization poses significant risks. I will conclude by outlining potential research avenues for multi-stakeholder alignment and emphasizing the necessity of decentralized value learning and specification.
Bio: I am the Bonnie and Marty (1964) Tenenbaum Career Development Assistant Professor of EECS at MIT. I run the Algorithmic Alignment Group in the Computer Science and Artificial Intelligence Laboratory (CSAIL) and I'm also a Schmidt Sciences AI2050 Early Career Fellow. My research develops methods to ensure that AI systems behavior aligns with the goals and values of their human users and society as a whole, a concept known as 'AI alignment'. My group and I work to address alignment challenges in multi-agent systems, human-AI teams, and societal oversight of machine learning. Our goal is to enable the safe, beneficial, and trustworthy deployment of AI in real-world settings.
Speaker: Dylan Hadfield-Menell, Assistant Professor, MIT
Abstract: The challenge of specifying goals for agents has long been recognized, as Kerr's seminal 1975 paper 'On the Folly of Rewarding A while Hoping for B' highlights the unintended consequences of misaligned reward systems. This issue lies at the heart of AI alignment research, which seeks to design incentive structures that reliably guide AI systems to achieve our intended objectives. In this talk, I will explore how brittle alignment emerges as an inherent result of incomplete goal specification. By presenting a theoretical model, I will demonstrate the sufficient conditions under which the unconstrained optimization of any goal that fails to capture all features of value ultimately leads to worse outcomes than forgoing optimization. Furthermore, I will extend this theoretical framework to address the importance of inclusivity in value specification. By reinterpreting the model such that different features of value represent the diverse perspectives of individuals, optimizing an incomplete goal can be expected to impact those whose values are not taken into account adversely. Consequently, technology that aligns an agent with the values of a single person or organization poses significant risks. I will conclude by outlining potential research avenues for multi-stakeholder alignment and emphasizing the necessity of decentralized value learning and specification.
Bio: I am the Bonnie and Marty (1964) Tenenbaum Career Development Assistant Professor of EECS at MIT. I run the Algorithmic Alignment Group in the Computer Science and Artificial Intelligence Laboratory (CSAIL) and I'm also a Schmidt Sciences AI2050 Early Career Fellow. My research develops methods to ensure that AI systems behavior aligns with the goals and values of their human users and society as a whole, a concept known as 'AI alignment'. My group and I work to address alignment challenges in multi-agent systems, human-AI teams, and societal oversight of machine learning. Our goal is to enable the safe, beneficial, and trustworthy deployment of AI in real-world settings.