Uploaded September 2026 | Updated November 2026, 20 hours ago
Manual code tweaking isn't a testing strategy. Here is how to actually evaluate AI agents for production. In this episode of AI Agent Clinic, Google Cloud engineer Dani Zamora and Matthew Feroz (Merge) take DocsHound, an open-source LangGraph agent, and build an end-to-end evaluation pipeline in 60 minutes.
🔗 Repositories & Resources:
• Open-Source Agent-Eval Toolkit (GitHub): https://g.dev/cloud/agent-eval
• DocsHound Agent Code: https://g.dev/cloud/docshound
• Gemini Enterprise Agent Platform Docs: https://g.dev/cloud/agent-evaluation
Most autonomous loops look great in local demos but fail silently in production. In this hands-on clinic, we compress weeks of testing setup into one hour by:
1. Mapping agent execution flow and inner workings using Antigravity
2. Standardizing multi-turn traces with OpenTelemetry & OpenInference (making your evals work across agentic frameworks like ADK, LangGraph, CrewAI, AutoGen, or custom implementations)
3. Pairing custom LLM-as-a-judge evaluation rubrics and deterministic checkers for quality and performance assessment
4. Additionally, tracking signals like: latency, token usage, and API cost
5. Ensuring zero vendor lock-in by building on open-source standards
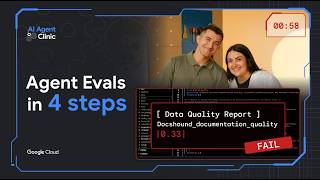
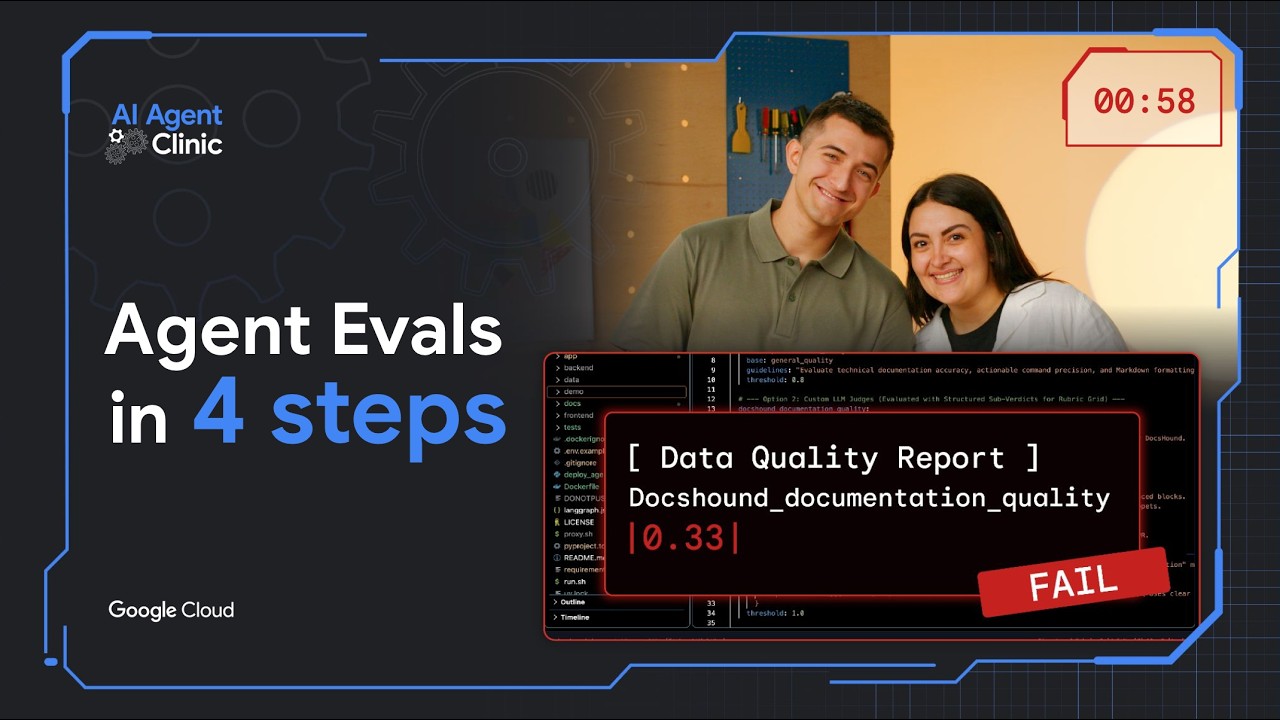
Along the way, our automated scorecard catches a blind spot: a 33% documentation quality score that while eye-balling the results we initially missed.
Chapters:
0:00 — Intro
01:02 — The AI Agent Clinic: Eval Edition
02:11 — Meet DocsHound, a LangGraph Agent
03:40 — Making Agent Traces Evaluation-Ready (OTel & OpenInference)
05:02 — Beyond the “Vibe Check”
05:51 — The 60-Minute Challenge Begins
06:47 — Step 1: Mapping Agent Architecture with Antigravity
11:18 — Step 2: Setting Up the Open-Source Agent Eval Tool
17:14 — Measuring Quality, Latency & Token Cost
18:34 — Step 3: Translating Quality Definitions into Metrics
21:40 — Step 4: Visualizing Results & Spotting the 0.33 Failure
22:36 — Finding Where the Agent Needs Improvement
24:08 — Why Evals Change How You Build Agents
25:03 — Are AI Agent Evals for Everyone?
Watch more of the AI Agent Clinic → youtube.com/playlist?list=PLAz2I7PJjFtA
🔔 Subscribe to Google Cloud Tech → https://goo.gle/GoogleCloudTech
#GoogleCloud #LangGraph #AIAgents #OpenTelemetry #SoftwareEngineering #GenerativeAI # AIDevelopment #OpenSource #Antigravity #GeminiAgentPlatform #GeminiEnterprise #AgentEvals #AgentsCLI
Tech Stack Featured: LangGraph, OpenTelemetry (OTel), OpenInference, Gemini 3.7 , Python
Speakers: Dani Zamora, Matthew Feroz
Products Mentioned: Antigravity, Gemini, Google Cloud, Gemini Enterprise Agent Platform (Vertex AI), Agents CLI
Manual code tweaking isn't a testing strategy. Here is how to actually evaluate AI agents for production. In this episode of AI Agent Clinic, Google Cloud engineer Dani Zamora and Matthew Feroz (Merge) take DocsHound, an open-source LangGraph agent, and build an end-to-end evaluation pipeline in 60 minutes.
🔗 Repositories & Resources:
• Open-Source Agent-Eval Toolkit (GitHub): https://g.dev/cloud/agent-eval
• DocsHound Agent Code: https://g.dev/cloud/docshound
• Gemini Enterprise Agent Platform Docs: https://g.dev/cloud/agent-evaluation
Most autonomous loops look great in local demos but fail silently in production. In this hands-on clinic, we compress weeks of testing setup into one hour by:
1. Mapping agent execution flow and inner workings using Antigravity
2. Standardizing multi-turn traces with OpenTelemetry & OpenInference (making your evals work across agentic frameworks like ADK, LangGraph, CrewAI, AutoGen, or custom implementations)
3. Pairing custom LLM-as-a-judge evaluation rubrics and deterministic checkers for quality and performance assessment
4. Additionally, tracking signals like: latency, token usage, and API cost
5. Ensuring zero vendor lock-in by building on open-source standards
Along the way, our automated scorecard catches a blind spot: a 33% documentation quality score that while eye-balling the results we initially missed.
Chapters:
0:00 — Intro
01:02 — The AI Agent Clinic: Eval Edition
02:11 — Meet DocsHound, a LangGraph Agent
03:40 — Making Agent Traces Evaluation-Ready (OTel & OpenInference)
05:02 — Beyond the “Vibe Check”
05:51 — The 60-Minute Challenge Begins
06:47 — Step 1: Mapping Agent Architecture with Antigravity
11:18 — Step 2: Setting Up the Open-Source Agent Eval Tool
17:14 — Measuring Quality, Latency & Token Cost
18:34 — Step 3: Translating Quality Definitions into Metrics
21:40 — Step 4: Visualizing Results & Spotting the 0.33 Failure
22:36 — Finding Where the Agent Needs Improvement
24:08 — Why Evals Change How You Build Agents
25:03 — Are AI Agent Evals for Everyone?
Watch more of the AI Agent Clinic → youtube.com/playlist?list=PLAz2I7PJjFtA
🔔 Subscribe to Google Cloud Tech → https://goo.gle/GoogleCloudTech
#GoogleCloud #LangGraph #AIAgents #OpenTelemetry #SoftwareEngineering #GenerativeAI # AIDevelopment #OpenSource #Antigravity #GeminiAgentPlatform #GeminiEnterprise #AgentEvals #AgentsCLI
Tech Stack Featured: LangGraph, OpenTelemetry (OTel), OpenInference, Gemini 3.7 , Python
Speakers: Dani Zamora, Matthew Feroz
Products Mentioned: Antigravity, Gemini, Google Cloud, Gemini Enterprise Agent Platform (Vertex AI), Agents CLI