Uploaded November 2026 | Updated November 2026, 11 hours ago
Trained on four thousand tokens. Asked to read sixteen thousand. In an LLM Interview you get exactly this question: "Why do transformers need positional encoding?" Most candidates say "so the model knows the order of the words", and stop there. True, but why can't the model see order on its own, and how do you put position in?
- Fix 1, permutation equivariance: self-attention scores come from query · key dot products and the feed-forward layer runs on each token separately. Shuffle the input tokens and the output just shuffles the same way. A decoder's causal mask hints at order a little, but LLMs still add position explicitly
- Fix 2, absolute position: the original transformer used sinusoidal encoding (sine and cosine waves, no parameters, a formula for any position). BERT and GPT-2 used a learned table, one row per position: 512 in BERT, 1,024 in GPT-2
- Fix 3, add or concat: the position vector is added to the token embedding, not concatenated. Concatenating would widen the vector and every layer's weights. Adding keeps the width, and the model learns to read the two signals apart
- Fix 4, relative position (RoPE): what matters is how close two words are, not where they are. RoPE rotates the query and key by position in every attention layer, so distance shows up in the score. Most open LLMs, like Llama, use it
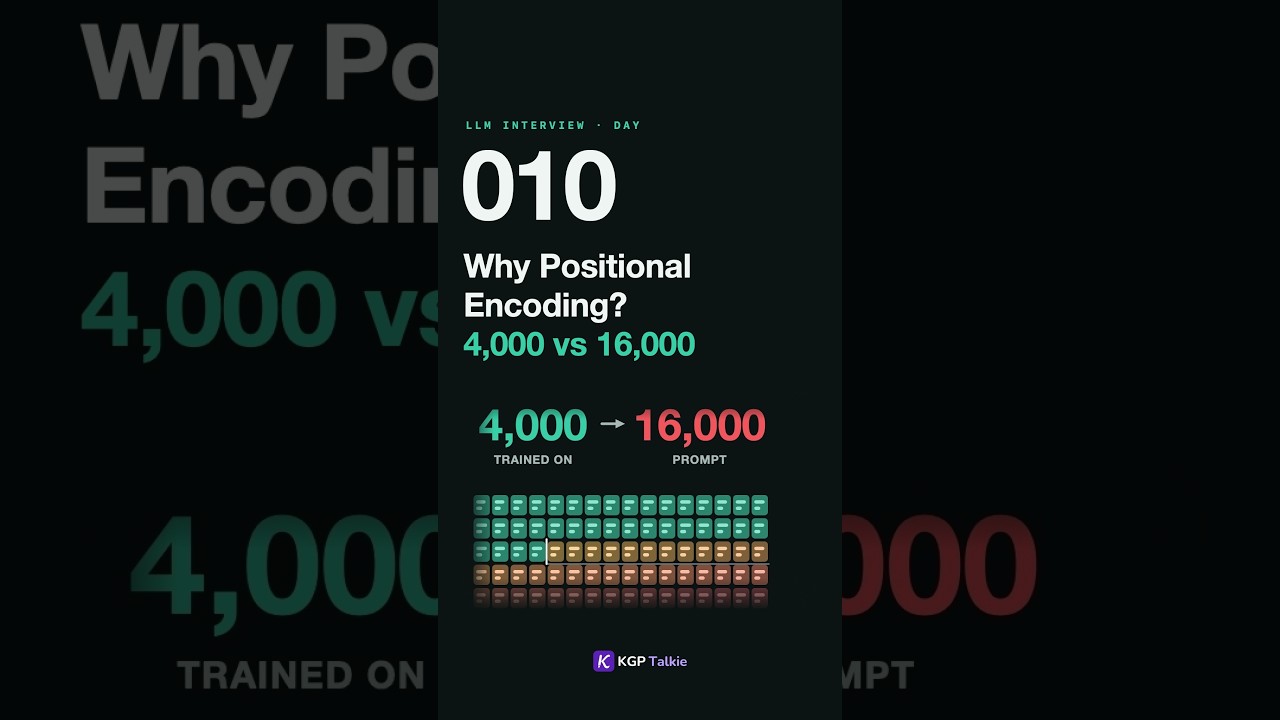
- Follow-up, prompts longer than training: a learned table has no row for position 1,025. Sinusoidal and RoPE compute any position, but the model never saw those values or angles, so quality drops. The fix: position interpolation (trained on 4,000, need 16,000, divide positions by 4) plus a little fine-tuning on long text
One-line answer: attention can't see order, add position (sinusoidal, learned or RoPE) instead of concatenating, and use position interpolation for prompts longer than training.
Next LLM Interview episode: sinusoidal vs learned vs RoPE. Comment and tell me, what's the longest prompt you've ever sent? Follow for the full LLM Interview series.
#shorts #LLM #LLMInterview #AIInterview #InterviewPrep #PositionalEncoding #Transformers #RoPE #Attention #GenAI #MachineLearning #KGPTalkie
Trained on four thousand tokens. Asked to read sixteen thousand. In an LLM Interview you get exactly this question: "Why do transformers need positional encoding?" Most candidates say "so the model knows the order of the words", and stop there. True, but why can't the model see order on its own, and how do you put position in?
- Fix 1, permutation equivariance: self-attention scores come from query · key dot products and the feed-forward layer runs on each token separately. Shuffle the input tokens and the output just shuffles the same way. A decoder's causal mask hints at order a little, but LLMs still add position explicitly
- Fix 2, absolute position: the original transformer used sinusoidal encoding (sine and cosine waves, no parameters, a formula for any position). BERT and GPT-2 used a learned table, one row per position: 512 in BERT, 1,024 in GPT-2
- Fix 3, add or concat: the position vector is added to the token embedding, not concatenated. Concatenating would widen the vector and every layer's weights. Adding keeps the width, and the model learns to read the two signals apart
- Fix 4, relative position (RoPE): what matters is how close two words are, not where they are. RoPE rotates the query and key by position in every attention layer, so distance shows up in the score. Most open LLMs, like Llama, use it
- Follow-up, prompts longer than training: a learned table has no row for position 1,025. Sinusoidal and RoPE compute any position, but the model never saw those values or angles, so quality drops. The fix: position interpolation (trained on 4,000, need 16,000, divide positions by 4) plus a little fine-tuning on long text
One-line answer: attention can't see order, add position (sinusoidal, learned or RoPE) instead of concatenating, and use position interpolation for prompts longer than training.
Next LLM Interview episode: sinusoidal vs learned vs RoPE. Comment and tell me, what's the longest prompt you've ever sent? Follow for the full LLM Interview series.
#shorts #LLM #LLMInterview #AIInterview #InterviewPrep #PositionalEncoding #Transformers #RoPE #Attention #GenAI #MachineLearning #KGPTalkie