Uploaded September 2026 | Updated November 2026, 3 days ago
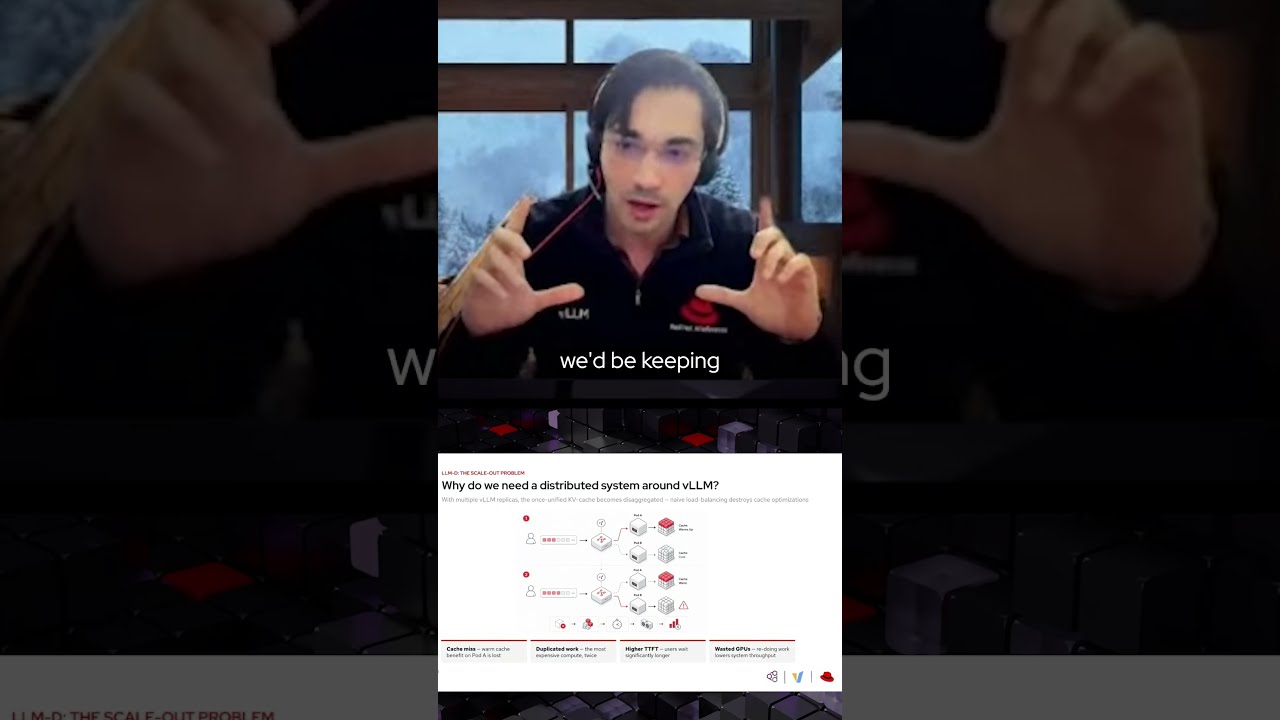
Greg Pereira, Senior Machine Learning Engineer at Red Hat, discusses the scale-out problem: add a second vLLM replica behind a traditional load balancer and you drop to roughly 50% KV cache reuse. It only gets worse from there.
From vLLM Office Hours #55: Mooncake + vLLM/llm-d Deep Dive. Full session: youtu.be/RFyeBEy1AP8
Join us live every other Thursday: https://red.ht/office-hours
#vLLM #llm-d #KVCache #AIInference #RedHat #MLOps
Greg Pereira, Senior Machine Learning Engineer at Red Hat, discusses the scale-out problem: add a second vLLM replica behind a traditional load balancer and you drop to roughly 50% KV cache reuse. It only gets worse from there.
From vLLM Office Hours #55: Mooncake + vLLM/llm-d Deep Dive. Full session: youtu.be/RFyeBEy1AP8
Join us live every other Thursday: https://red.ht/office-hours
#vLLM #llm-d #KVCache #AIInference #RedHat #MLOps