Uploaded June 2026 | Updated September 2026, 2 weeks ago
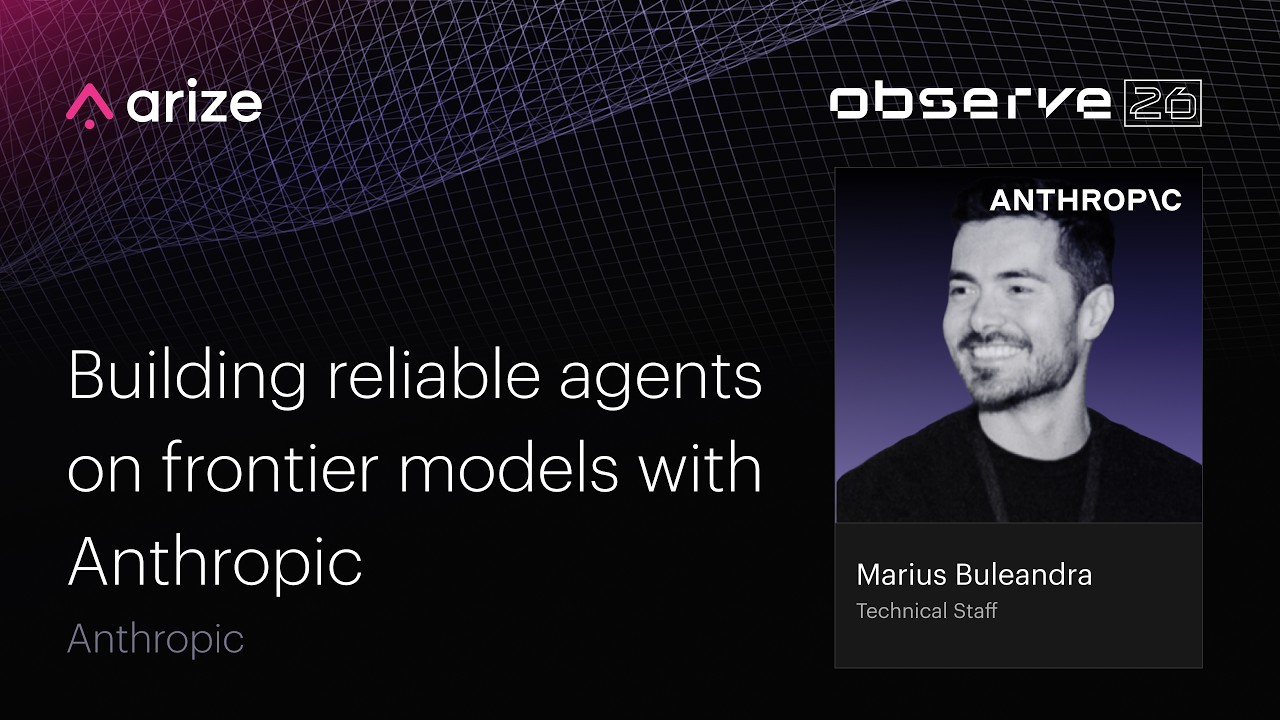
Building AI agents is harder than it looks. In this session from Arize Observe, Marius Buleandra from Anthropic shares practical lessons from working with customers deploying agents in production.
Learn why agent failures compound over time, how to design effective evaluation systems, and why human review remains essential even in an era of AI-assisted development.
Marius walks through the differences between regression and capability evaluations, how leading AI teams mine production transcripts for new evals, and why understanding agent behavior matters more than simply tracking benchmark scores.
You’ll learn:
* Why agent errors compound across long-running workflows
* How to build evaluation systems that catch regressions
* The difference between capability evals and regression evals
* Why transcript analysis is critical for agent improvement
* How Anthropic approaches agent reliability in production
* Practical strategies for scaling human evaluation with AI
Chapters
00:00 Introduction
00:47 Why AI Agents Are Hard to Build
03:09 Why Evals Are Essential
06:09 Regression vs Capability Evals
07:27 Getting Started with Evaluation Design
08:35 Mining Production Transcripts for Evals
10:15 Evaluating Outcomes vs Agent Behavior
11:08 Building Realistic Evaluation Environments
12:18 Why You Must Read the Transcripts
14:51 Scaling Transcript Review with AI
15:55 Final Recommendations
#AIAgents #Anthropic #AgentEvaluation #LLMEvals #AIObservability #ArizeObserve
🔗 Try Arize AX & Phoenix OSS: arize.com
🔔 Subscribe for weekly content on LLMs, agents, and evaluation: youtube.com/@arizeai?sub_confirmation=1
Building AI agents is harder than it looks. In this session from Arize Observe, Marius Buleandra from Anthropic shares practical lessons from working with customers deploying agents in production.
Learn why agent failures compound over time, how to design effective evaluation systems, and why human review remains essential even in an era of AI-assisted development.
Marius walks through the differences between regression and capability evaluations, how leading AI teams mine production transcripts for new evals, and why understanding agent behavior matters more than simply tracking benchmark scores.
You’ll learn:
* Why agent errors compound across long-running workflows
* How to build evaluation systems that catch regressions
* The difference between capability evals and regression evals
* Why transcript analysis is critical for agent improvement
* How Anthropic approaches agent reliability in production
* Practical strategies for scaling human evaluation with AI
Chapters
00:00 Introduction
00:47 Why AI Agents Are Hard to Build
03:09 Why Evals Are Essential
06:09 Regression vs Capability Evals
07:27 Getting Started with Evaluation Design
08:35 Mining Production Transcripts for Evals
10:15 Evaluating Outcomes vs Agent Behavior
11:08 Building Realistic Evaluation Environments
12:18 Why You Must Read the Transcripts
14:51 Scaling Transcript Review with AI
15:55 Final Recommendations
#AIAgents #Anthropic #AgentEvaluation #LLMEvals #AIObservability #ArizeObserve
🔗 Try Arize AX & Phoenix OSS: arize.com
🔔 Subscribe for weekly content on LLMs, agents, and evaluation: youtube.com/@arizeai?sub_confirmation=1