Uploaded September 2026 | Updated November 2026, 4 hours ago
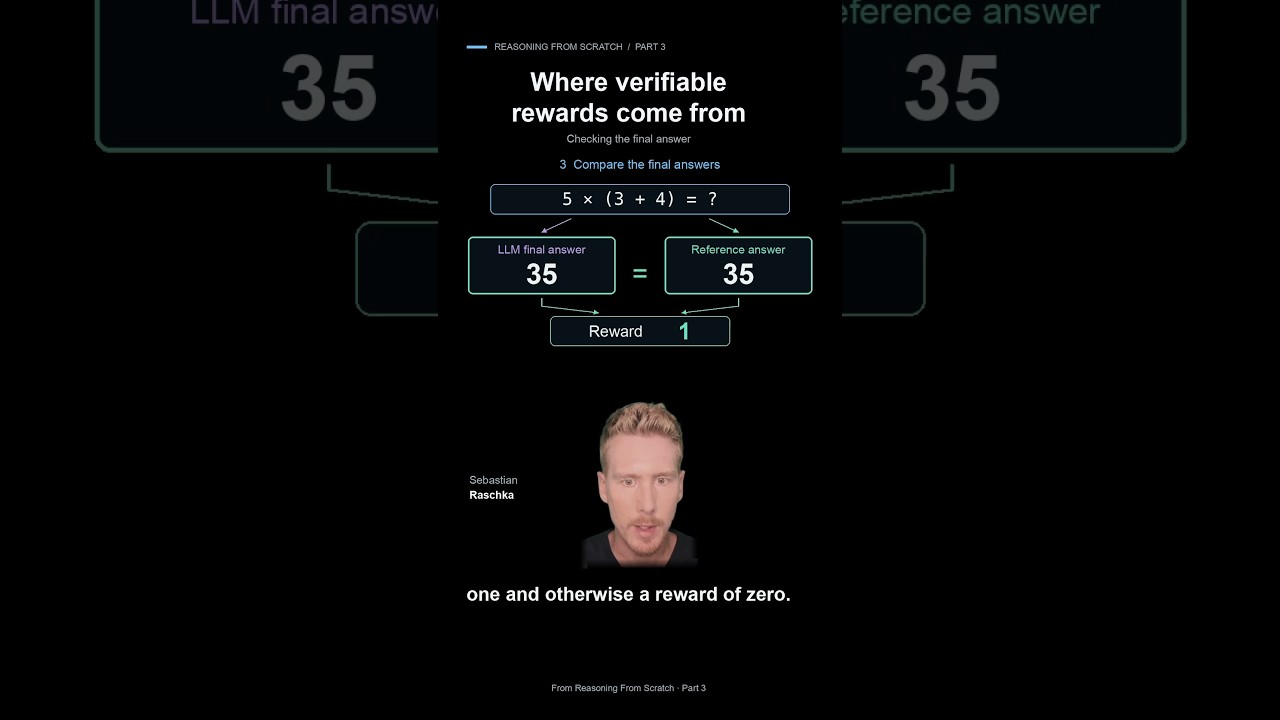
A calculator gives us a reference answer to check an LLM’s response. In this example, a matching final answer receives a reward of 1, and a mismatch receives 0.
An excerpt from my reasoning model series: youtube.com/watch?v=Kh9mqTzjuEQ&list=PLfrHAQCRxtUs&index=1
A calculator gives us a reference answer to check an LLM’s response. In this example, a matching final answer receives a reward of 1, and a mismatch receives 0.
An excerpt from my reasoning model series: youtube.com/watch?v=Kh9mqTzjuEQ&list=PLfrHAQCRxtUs&index=1