Uploaded October 2026 | Updated November 2026, 3 hours ago
Project: simongiebenhain.github.io/video-diffusion-avatars
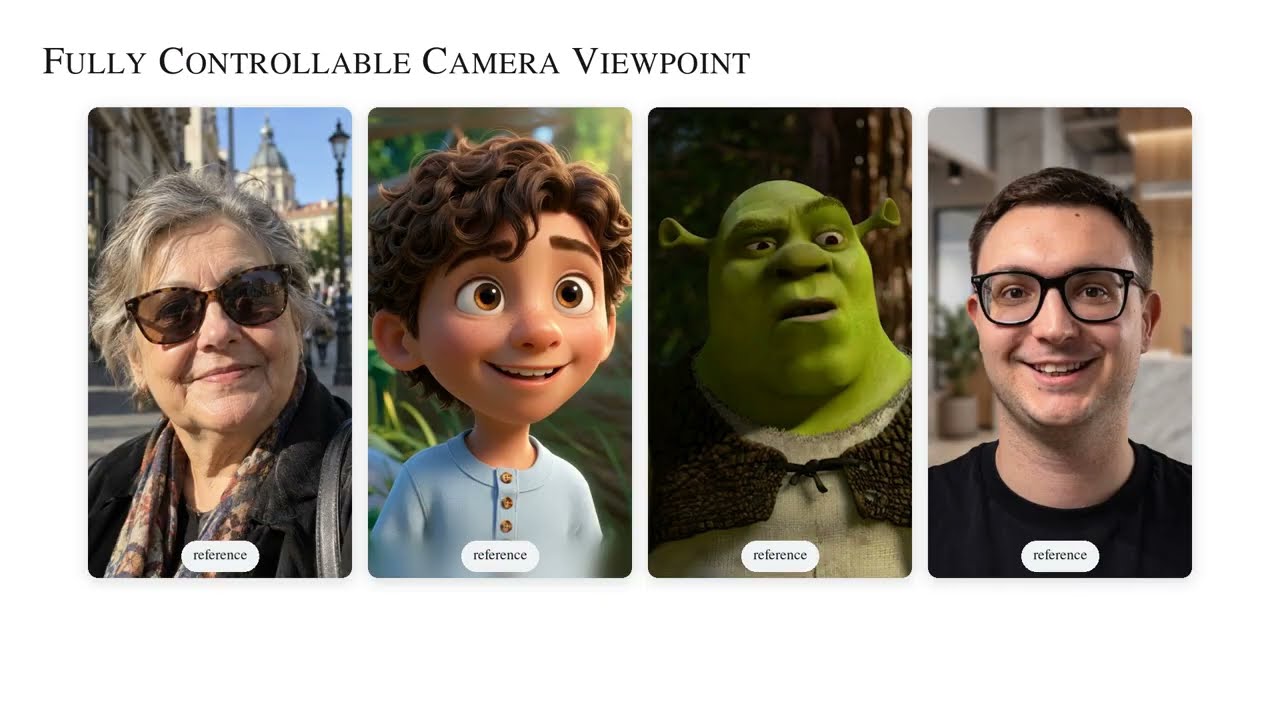
We leverage the world prior of existing video diffusion models (VDMs) to create 3D avatars from a single image, by carefully fine-tuning the VDM on public multi-view datasets and view-disentangled expression codes. VDAs let the user generate videos with free control over facial expressions, rendering camera and neck pose. The videos exhibit physically plausible dynamics and light interactions, such as reflections, shadows and refractions.
Project: simongiebenhain.github.io/video-diffusion-avatars
We leverage the world prior of existing video diffusion models (VDMs) to create 3D avatars from a single image, by carefully fine-tuning the VDM on public multi-view datasets and view-disentangled expression codes. VDAs let the user generate videos with free control over facial expressions, rendering camera and neck pose. The videos exhibit physically plausible dynamics and light interactions, such as reflections, shadows and refractions.


