Uploaded October 2026 | Updated November 2026, 4 days ago
Yue Dong (UC Riverside)
https://simons.berkeley.edu/talks/yue-dong-uc-riverside-2026-10-08
Trustworthy AI: From Hallucinations to Reliable Autonomy
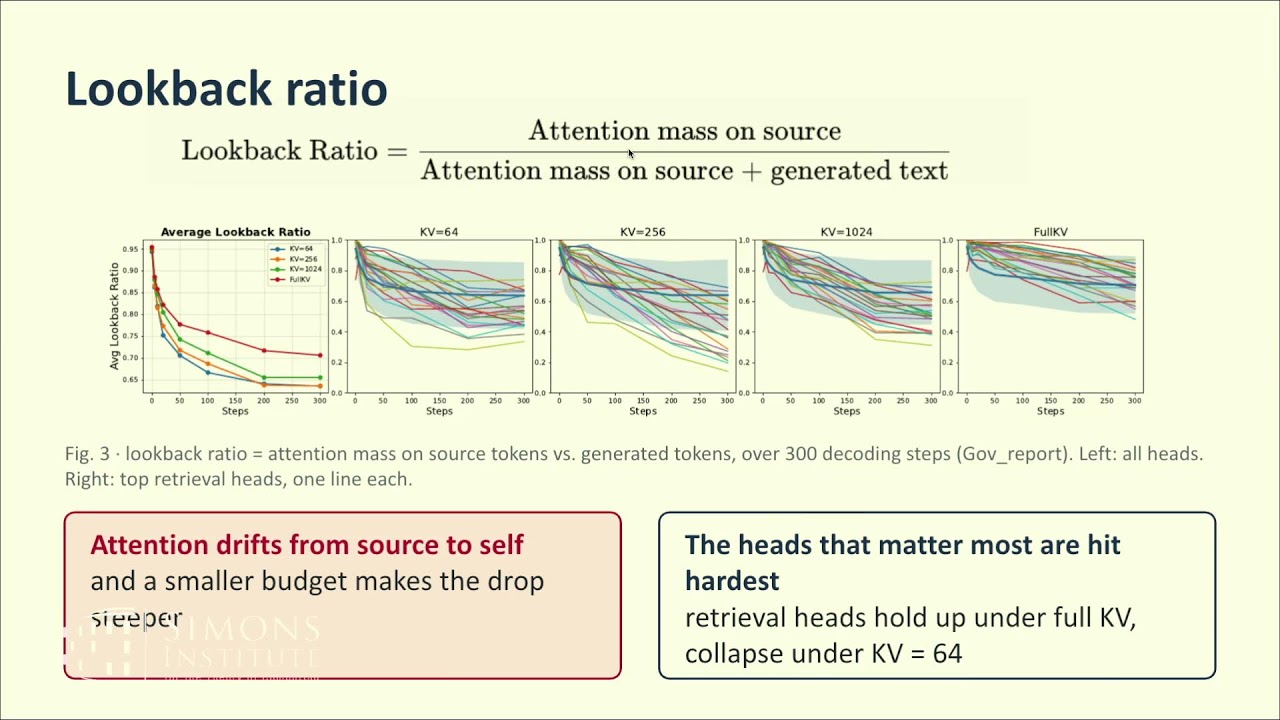
Language model hallucinations arise not only from gaps in knowledge, but also from failures in how models retrieve, select, and integrate information. In this talk, I will examine these failures from two complementary perspectives. First, I will present a mechanistic account of non-factual hallucinations, identifying distinct failures in knowledge enrichment and answer extraction within the model’s factual recall process. I will then extend this analysis to long-context language models, examining how parametric knowledge interacts, and sometimes conflicts, with information provided in context. The results show that stronger contextual retrieval does not necessarily lead to more reliable knowledge use and may even interfere with parametric recall. Together, these studies characterize hallucination as a failure of knowledge coordination and highlight implications for model interpretability, evaluation, mitigation, and design.
Yue Dong (UC Riverside)
https://simons.berkeley.edu/talks/yue-dong-uc-riverside-2026-10-08
Trustworthy AI: From Hallucinations to Reliable Autonomy
Language model hallucinations arise not only from gaps in knowledge, but also from failures in how models retrieve, select, and integrate information. In this talk, I will examine these failures from two complementary perspectives. First, I will present a mechanistic account of non-factual hallucinations, identifying distinct failures in knowledge enrichment and answer extraction within the model’s factual recall process. I will then extend this analysis to long-context language models, examining how parametric knowledge interacts, and sometimes conflicts, with information provided in context. The results show that stronger contextual retrieval does not necessarily lead to more reliable knowledge use and may even interfere with parametric recall. Together, these studies characterize hallucination as a failure of knowledge coordination and highlight implications for model interpretability, evaluation, mitigation, and design.