Uploaded May 2026 | Updated November 2026, 1 day ago
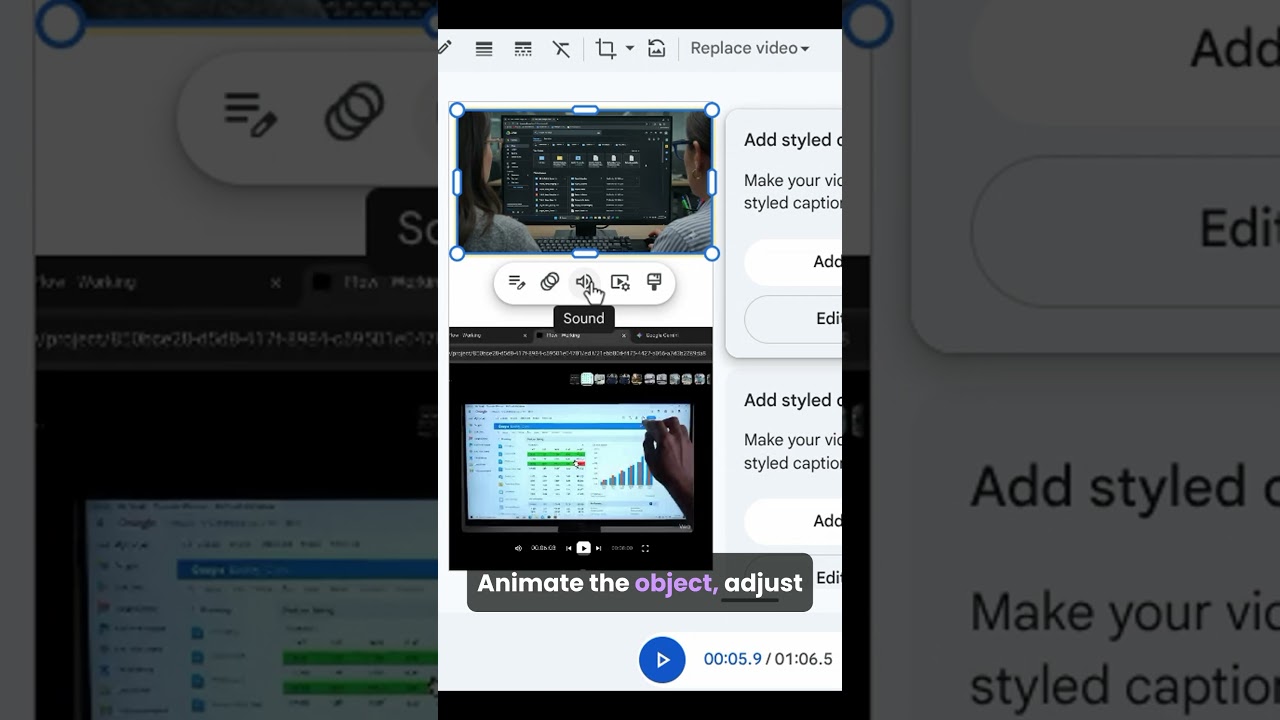
Whenever you click an object—whether it's a block of text, a shape, an image, or a video clip—this context-aware toolbar instantly pops up to let you customize your scene in seconds. You can immediately choose to edit transcripts, animate objects, adjust the sound, and more.
#GoogleVids #GoogleWorkspace #VideoEditing #TechTips #WorkspaceHacks #AI #Productivity #Shorts
Whenever you click an object—whether it's a block of text, a shape, an image, or a video clip—this context-aware toolbar instantly pops up to let you customize your scene in seconds. You can immediately choose to edit transcripts, animate objects, adjust the sound, and more.
#GoogleVids #GoogleWorkspace #VideoEditing #TechTips #WorkspaceHacks #AI #Productivity #Shorts

![DeepSeek Janus Pro-7B Multimodal & Text-to-Image Generation
DeepSeek Janus Pro-7B is a groundbreaking multimodal AI model that excels in text-to-image generation and various visual reasoning tasks. This open-source model, developed by Chinese AI company DeepSeek, has garnered significant attention for its impressive capabilities and efficient architecture.
00:00 DeepSeek Janus Pro-7B Benchmarks
00:44 Using DeepSeek Janus Pro-7B for Free
02:03 DeepSeek Janus Pro’s Multimodal Capabilities
04:45 Text-to-Image Generation
08:13 Assessment Compared to Other Image Generation Tools
In text-to-image generation, DeepSeek Janus Pro-7B has demonstrated remarkable results, with the company claiming it outperforms established models like DALL-E 3 and Stable Diffusion in significant benchmark tests[2].
Despite its compact size of 7 billion parameters, DeepSeek Janus Pro-7B delivers performance comparable to or surpassing larger, more resource-intensive models[3]. This efficiency makes it an attractive option for researchers and developers seeking to implement advanced AI capabilities without excessive computational requirements. The models open-source nature further enhances its accessibility, allowing for community contributions and improvements[1].
Janus Pro-7Bs release has had a notable impact on the AI industry, causing significant market reactions and challenging the competitive balance in global AI development[3]. DeepSeek Janus Pro-7B is a multimodal AI model that excels in text-to-image generation, combining advanced visual understanding with high-quality output capabilities. Built on the DeepSeek-LLM-7B architecture, this open-source framework unifies image analysis and creation through separate visual encoding pathways while maintaining a cohesive transformer core. Its multimodal design enables seamless processing of text, images, and other data types, making it particularly effective for applications requiring both interpretation and generation of visual content.
The model’s text-to-image generation capabilities have demonstrated competitive performance, achieving 80% accuracy on the GenEval benchmark—surpassing DALL-E 3 (67%) and Stable Diffusion 3 Medium (74%). This performance stems from a 72-million-image synthetic dataset balanced with real-world data, 7 billion parameters for detail retention, and intelligent feedback algorithms that refine output stability.
Developers appreciate its open-source nature, allowing customization for specialized workflows through platforms like Hugging Face and GitHub.
While DeepSeek Janus Pro-7B shows promise in multimodal benchmarks (scoring 79.2 on MMB), user feedback highlights current limitations in output resolution (384x384) and occasional inconsistencies in complex scenarios. However, its architecture—featuring SigLIP-L for visual understanding and VQ tokenizers for generation—provides a foundation for future improvements.
Built on the DeepSeek-LLM-7B architecture, this open-source framework unifies image analysis and creation through separate visual encoding pathways while maintaining a cohesive transformer core. Its multimodal design enables the processing of text and images, making it particularly effective for applications requiring both interpretation and generation of visual content.
The model’s efficient training process and optimized inference speed make it accessible for organizations seeking cost-effective AI solutions without compromising on multimodal versatility. As an evolving tool, DeepSeek Janus Pro-7B represents a significant step toward unified AI systems capable of both interpreting and creating visual content at scale.
Citations:
- https://www.merca20.com/what-is-deep-seeks-janus-pro-7b-this-is-how-the-chinese-artificial-intelligence-that-generates-images-works/
- https://economictimes.indiatimes.com/news/international/us/deepseeks-ai-models-explained-find-out-how-v3-r1-janus-pro-7b-function/articleshow/117646284.cms
- https://dev.to/nodeshiftcloud/how-to-install-deepseek-janus-pro-7b-locally-5924
- https://huggingface.co/deepseek-ai/Janus-Pro-7B
- https://huggingface.co/deepseek-ai/Janus-Pro-7B/discussions/75
- https://opentools.ai/news
- https://www.datacamp.com/blog/janus-pro
- https://www.prompthub.us/models/janus-pro-7b
Learn more insights on measuring website traffic, analysis, and reporting, including GA4 and other tools: https://growthlearner.com/?utm_source=youtube&utm_medium=social DeepSeek Janus Pro-7B Multimodal & Text-to-Image Generation](https://i.ytimg.com/vi/u2_nQ9SNXGI/mqdefault.jpg)


![Google DeepMind Releases Gemini 2.0 Pro & 2.0 Flash for All
Google DeepMind released Gemini 2.0 series, including Gemini 2.0 Pro, Gemini 2.0 Flash, Gemini 2.0 Flash Thinking, and Gemini 2.0 Flash-Lite, representing a significant advancement in AI technology. These models offer enhanced capabilities and performance across various applications, from complex problem-solving to efficient everyday tasks.
00:00 AI Model Overviews
01:27 Gemini 2.0 Flash & 2.0 Flash Thinking Model Details
05:51 Head-to-Head Response Comparison
7:30 Accessing Google Apps
09:03 Gemini 2.0 Flash-Lite Model Details
09:44 Gemini 2.0 Pro Details & Testing
Gemini 2.0 Pro, available as an experimental model, is Googles most advanced offering, designed for coding and complex prompts[3]. It features a 2-million token context window, allowing for extensive information processing. This model excels in multimodal understanding, coding, and function calling, making it ideal for developers working on sophisticated projects or researchers dealing with large datasets. Gemini 2.0 Pro also supports grounding with Google Search, enabling real-time information retrieval for up-to-date responses[3].
Gemini 2.0 Flash, now generally available, builds upon its predecessor with improved speed and performance. Its twice as fast as Gemini 1.5 Flash while maintaining comparable quality to the slower Gemini 1.5 Pro[1]. This model introduces multimodal capabilities, supporting inputs like images, video, and audio, as well as outputs including natively generated images and multilingual text-to-speech[5]. With a 1-million token context window, Gemini 2.0 Flash is versatile enough for a wide range of applications, from chatbots to content generation[4].
Gemini 2.0 Flash Thinking, an experimental version, combines the speed of Flash technology with enhanced problem-solving abilities[2]. This model is designed to break down complex questions into smaller, more manageable tasks, resulting in more accurate and comprehensive responses. Its particularly useful for tasks requiring detailed explanations or step-by-step solutions, such as in academic research or intricate coding challenges.
Gemini 2.0 Flash-Lite, introduced as Googles most cost-efficient model, is in public preview[2]. While specific details are limited, this model likely offers a balance between performance and resource efficiency, making it suitable for applications where cost optimization is a priority without significantly compromising on quality.
All these models support multimodal inputs with text output upon release, with additional modalities planned for general availability in the coming months[2]. They represent Googles commitment through Google DeepMind to advancing AI technology, offering developers and businesses powerful tools to enhance productivity, drive innovation, and create more sophisticated AI-powered applications across various industries.
Citations:
- https://www.techtarget.com/whatis/feature/Google-Gemini-20-explained-Everything-you-need-to-know
- https://blog.google/technology/google-deepmind/gemini-model-updates-february-2025/
- https://cloud.google.com/vertex-ai/generative-ai/docs/gemini-v2
- https://ai.google.dev/gemini-api/docs/models/gemini
- https://blog.google/technology/google-deepmind/google-gemini-ai-update-december-2024/
- https://deepmind.google/technologies/gemini/flash/
- https://support.google.com/gemini/thread/321791026?hl=en&msgid=321792231
- https://github.blog/changelog/2025-02-05-google-gemini-2-0-flash-is-now-available-to-all-copilot-users-in-public-preview/
- https://blog.google/feed/gemini-app-experimental-models/
🚀 More templates and resources for tracking and reporting, including a Campaign URL Builder: https://build.growthlearner.com/
Learn more insights on measuring website traffic, analysis, and reporting, including GA4 and other tools: https://growthlearner.com/?utm_source=youtube&utm_medium=social Google DeepMind Releases Gemini 2.0 Pro & 2.0 Flash for All](https://i.ytimg.com/vi/vIIWA3rF6VY/mqdefault.jpg)


