Uploaded July 2025 | Updated September 2026, 2 weeks ago
We are seeing an emerging 3-layer OSS stack for AI compute:
PyTorch + vLLM + Ray + Kubernetes
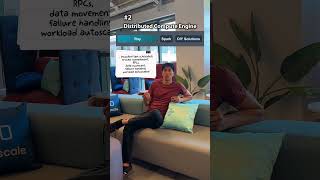
Robert Nishihara gives a quick breakdown of how this stack works together to scale LLMs + GenAI workloads
The AI compute software stack consists of 3 specialized layers:
Layer 1: Training & Inference Framework (PyTorch + vLLM)
• Runs models efficiently on GPUs
• Handles model optimization and model parallelism strategies
• Manages accelerator memory and automatic differentiation
Layer 2: Distributed Compute Engine (Ray)
• Schedules tasks within jobs and coordinates processes
• Ingests and moves data
• Provides workload-aware failure handling and autoscaling
Layer 3: Container Orchestrator (Kubernetes)
• Provisions compute resources
• Schedules entire jobs
• Manages user and workload multitenancy
Each layer handles what it does best. The separation of concerns makes this stack so powerful.
🔗 Read the full blog post with examples from Pinterest, Uber, and Roblox: anyscale.com/blog/ai-compute-open-source-stack-kubernetes-ray-pytorch-vllm
We are seeing an emerging 3-layer OSS stack for AI compute:
PyTorch + vLLM + Ray + Kubernetes
Robert Nishihara gives a quick breakdown of how this stack works together to scale LLMs + GenAI workloads
The AI compute software stack consists of 3 specialized layers:
Layer 1: Training & Inference Framework (PyTorch + vLLM)
• Runs models efficiently on GPUs
• Handles model optimization and model parallelism strategies
• Manages accelerator memory and automatic differentiation
Layer 2: Distributed Compute Engine (Ray)
• Schedules tasks within jobs and coordinates processes
• Ingests and moves data
• Provides workload-aware failure handling and autoscaling
Layer 3: Container Orchestrator (Kubernetes)
• Provisions compute resources
• Schedules entire jobs
• Manages user and workload multitenancy
Each layer handles what it does best. The separation of concerns makes this stack so powerful.
🔗 Read the full blog post with examples from Pinterest, Uber, and Roblox: anyscale.com/blog/ai-compute-open-source-stack-kubernetes-ray-pytorch-vllm