Uploaded July 2026 | Updated September 2026, 2 weeks ago
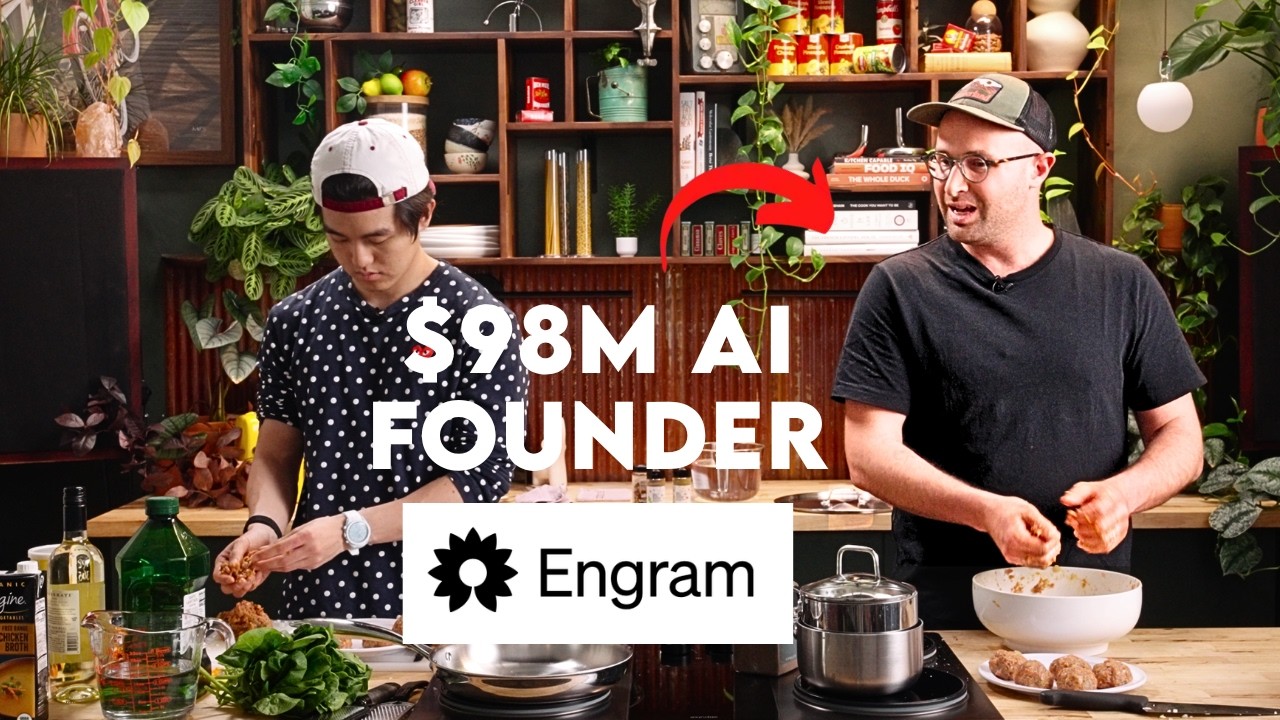
In this episode, Engram co-founder and CEO Dan Biderman joins Allen Park cook Mediterranean meatballs with yellow rice and talk about building AI that actually learns from you: why long context, RAG, and compaction eventually break down, how Engram compresses knowledge into cartridges and model weights, what continual learning could unlock for long-horizon agents, why token efficiency is inseparable from intelligence, how personal models could improve like Tamagotchis, and what it takes to build the research and infrastructure for millions of continuously updated AI memories.
Timestamps:
0:00 Intro
0:26 Engram’s $98M Launch and Meatballs
1:45 From Naval Special Operations to AI Research
4:32 Israeli Military Culture and Founder Maturity
7:12 Why Engram Is Betting on Context and Continual Learning
9:14 Knowledge Cartridges, Compression, and Model Intuition
14:10 Trillion-Token Company Knowledge and Context Rot
18:05 Long-Context Limits, Compaction, and Neural Memory
22:20 Test-Time Training and “Destroying Prefill”
24:31 Harvey and Holistic Enterprise Queries Beyond RAG
27:02 Personal AI Models and Tamagotchi Weights
30:00 What Belongs in Weights vs. Text
32:25 Autonomous Memory and User-Specific Feedback Loops
34:20 Token Efficiency, Model Routing, and Harder Tasks
38:03 Engram’s Research Team and Product Culture
43:02 Hiring Researchers and Infrastructure Engineers
45:25 Doing More With Less
47:41 Where to Find Engram
48:19 Final Taste Test
In this episode, Engram co-founder and CEO Dan Biderman joins Allen Park cook Mediterranean meatballs with yellow rice and talk about building AI that actually learns from you: why long context, RAG, and compaction eventually break down, how Engram compresses knowledge into cartridges and model weights, what continual learning could unlock for long-horizon agents, why token efficiency is inseparable from intelligence, how personal models could improve like Tamagotchis, and what it takes to build the research and infrastructure for millions of continuously updated AI memories.
Timestamps:
0:00 Intro
0:26 Engram’s $98M Launch and Meatballs
1:45 From Naval Special Operations to AI Research
4:32 Israeli Military Culture and Founder Maturity
7:12 Why Engram Is Betting on Context and Continual Learning
9:14 Knowledge Cartridges, Compression, and Model Intuition
14:10 Trillion-Token Company Knowledge and Context Rot
18:05 Long-Context Limits, Compaction, and Neural Memory
22:20 Test-Time Training and “Destroying Prefill”
24:31 Harvey and Holistic Enterprise Queries Beyond RAG
27:02 Personal AI Models and Tamagotchi Weights
30:00 What Belongs in Weights vs. Text
32:25 Autonomous Memory and User-Specific Feedback Loops
34:20 Token Efficiency, Model Routing, and Harder Tasks
38:03 Engram’s Research Team and Product Culture
43:02 Hiring Researchers and Infrastructure Engineers
45:25 Doing More With Less
47:41 Where to Find Engram
48:19 Final Taste Test